

Muon (optimizer)
Muon (short for MomentUm Orthogonalized by Newton-Schulz) is a neural-network optimizer that updates the two-dimensional weight matrices of hidden layers by taking the momentum-based SGD update and orthogonalizing it with a short Newton-Schulz iteration, which approximates the matrix sign function (the nearest semi-orthogonal matrix) by replacing the singular values of the update with ones.[1][2] It was introduced in 2024 by Keller Jordan together with Yuchen Jin, Vlado Boza, Jiacheng You, Franz Cesista, Laker Newhouse, and Jeremy Bernstein, originally as a tool for shaving seconds off the modded-nanogpt training-speed benchmark on eight NVIDIA H100 GPUs.[1][2] In Keller Jordan's words, Muon "optimizes 2D neural network parameters by taking the updates generated by SGD-momentum, and then applying a Newton-Schulz (NS) iteration as a post-processing step," while other parameters (embeddings, scalar gains, biases, and the output head) are still trained with AdamW.[1] Muon set NanoGPT speedrun records and was later scaled to frontier training: Moonshot AI's "Muon is Scalable for LLM Training" report (February 2025) found roughly 2x compute efficiency over AdamW, and a stabilized variant called MuonClip was used to pre-train Kimi K2, a one-trillion-parameter Mixture-of-Experts model.[3][4][5]
| Property | Value |
|---|---|
| Full name | MomentUm Orthogonalized by Newton-Schulz |
| First public release | 4 October 2024 (Keller Jordan, X post and GitHub) |
| Core authors | Keller Jordan, Yuchen Jin, Vlado Boza, Jiacheng You, Franz Cesista, Laker Newhouse, Jeremy Bernstein |
| Target parameters | 2D hidden-layer weight matrices (not embeddings, classifier heads, or biases) |
| Default hyperparameters | momentum = 0.95, Nesterov = true, Newton-Schulz steps = 5, lr = 0.02, weight decay = 0 |
| Newton-Schulz quintic coefficients | |
| Reference write-up | Keller Jordan, "Muon: An optimizer for hidden layers in neural networks", kellerjordan.github.io, 2024 |
| Reference scaling paper | Liu et al., "Muon is Scalable for LLM Training", arXiv:2502.16982, 2025 |
| Reference implementation | github.com/KellerJordan/Muon (MIT) |
What is Muon in simple terms?
Most optimizers, including Adam and AdamW, treat every number in a weight matrix as an independent dial and tune each one separately. Muon takes the opposite view: the numbers in a hidden layer together form a matrix that maps one space of activations to another, so the update should be a sensible matrix too. After computing the usual momentum update, Muon "cleans it up" by forcing it to be (approximately) orthogonal, which spreads the change evenly across directions instead of letting a few large directions dominate. That cleanup is done with five rounds of matrix multiplication (a Newton-Schulz iteration) that run fast on GPU tensor cores in bfloat16. Embeddings, the output head, and one-dimensional parameters such as biases keep using AdamW, because the matrix trick does not make sense for them.
Why was Muon created?
By 2024, AdamW had been the dominant optimizer for large language model pretraining for roughly half a decade, retaining the per-parameter moment estimates of Adam together with the decoupled weight decay introduced by Loshchilov and Hutter. Adam's per-parameter second-moment normalisation is a coordinate-wise operation: it treats every scalar in a matrix as an independent variable, ignoring the fact that the parameters in a linear layer collectively define a matrix that maps one activation space to another. A parallel research thread, beginning with Carlson et al. (2015) and continuing through Shazeer and Stern's Adafactor (2018), Shampoo (Gupta, Koren, and Singer, 2018), and more recently SOAP (Vyas et al., 2024), proposed updates that exploit this matrix structure, typically by preconditioning gradients with statistics of one or both factors. These methods were known to converge faster than Adam in many regimes, but they were memory-heavy, slow per step, and rarely adopted at frontier pretraining scale.[6]
Muon emerged from the modded-nanogpt speedrun, a community benchmark started in May 2024 that races to train GPT-2-small to a validation loss of 3.28 on the FineWeb dataset using eight NVIDIA H100 GPUs.[7] The starting point was Andrej Karpathy's llm.c GPT-2 replication, which reached the target in roughly 45 minutes; by April 2026, descendant runs had pushed the same task below 1.5 minutes, and an August 2026 record reached 0.665 minutes (about 40 seconds).[7] Keller Jordan, a researcher who maintains the modded-nanogpt leaderboard, introduced Muon as Record 3 on 4 October 2024, dropping the wall-clock time from 31.4 minutes to 24.9 minutes by replacing AdamW on the hidden weights.[1][7] Muon and optimizers derived from it have been used in every record since: Keller Jordan's December 2024 write-up counted 12 further records on Muon, and later records adopted variants such as NorMuon (October 2025) and, in August 2026, an orthogonalization-based optimizer stack called ANVIL.[1][7]
The theoretical inspiration came from a parallel line of work by Jeremy Bernstein and Laker Newhouse on modular duality, which casts different optimizers as steepest descent under different choices of norm.[9] Bernstein and Newhouse argued that, under an RMS-to-RMS operator norm on dense linear layers, the optimal update direction is the matrix sign of the gradient, computed by replacing the singular values of the gradient with ones. Muon is essentially a fast, GPU-friendly approximation of this sign operation applied to the momentum buffer rather than to the raw gradient.[9][10]
The historical reference for orthogonalising gradients in deep learning is older than the modular-duality framework. Carlson and colleagues (2015) proposed stochastic spectral descent, which orthogonalized gradient estimates using SVD, and a hybrid with RMSprop called RMSspectral for feedforward networks, while Flynn (2017) proposed duality structure gradient descent.[1][9] These earlier methods were rarely used in practice because the orthogonalisation step was implemented with SVD variants (full or randomized SVD) and lacked momentum that did not scale to billion-parameter models. The novel contribution of the 2024 Muon authors was algorithmic rather than purely conceptual: a quintic Newton-Schulz iteration with hand-tuned coefficients runs in bfloat16 on GPU tensor cores and adds a FLOP overhead below 1 percent of a training step (about 0.7 percent at NanoGPT speedrun scale).[1][9]
How does Muon work?
Muon is described compactly by the reference implementation at github.com/KellerJordan/Muon.[2] For every two-dimensional parameter matrix of shape :
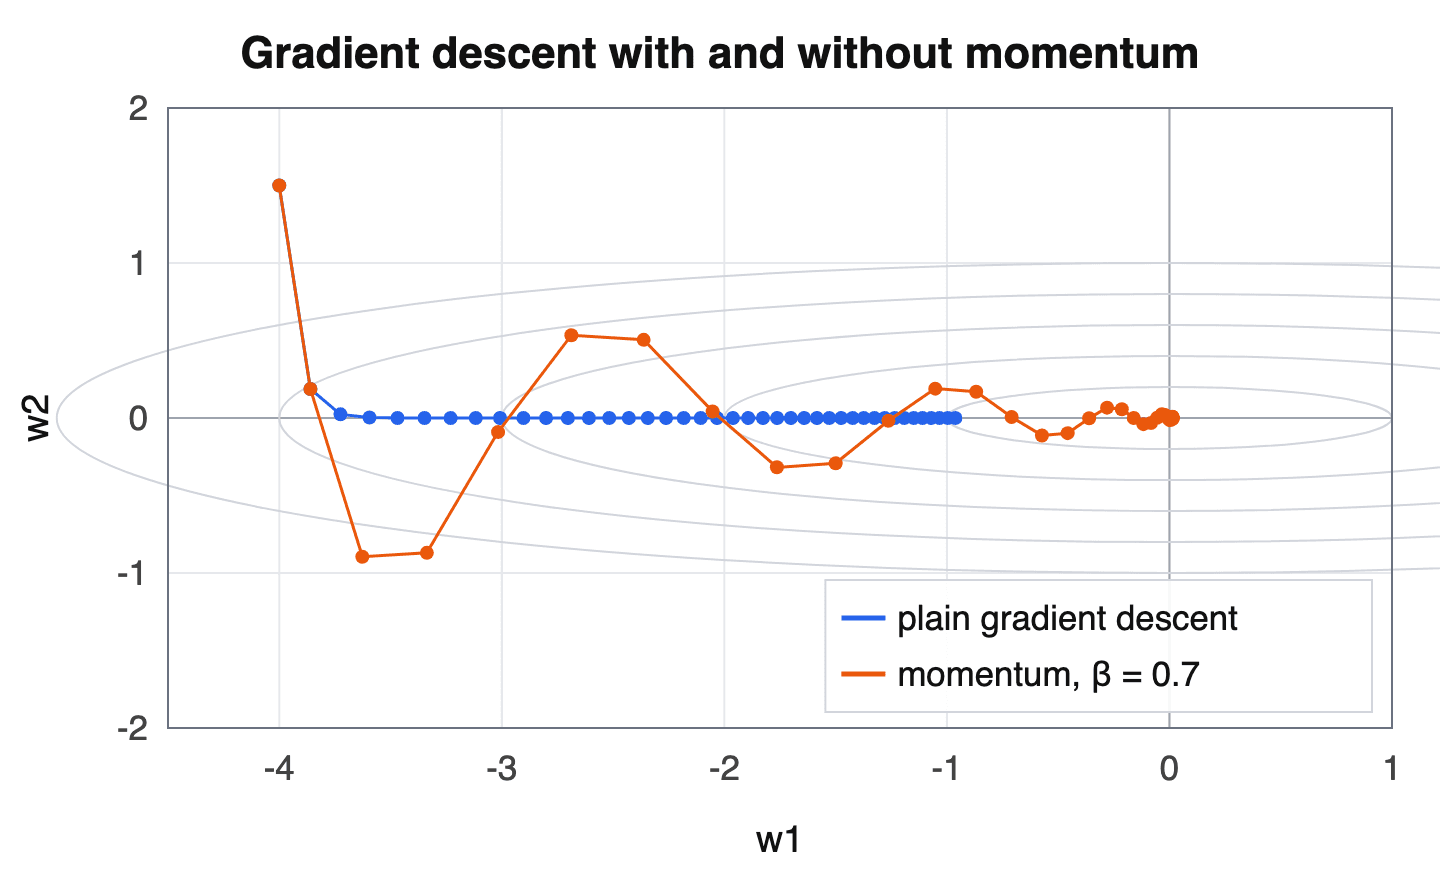
- Maintain an exponential moving-average momentum buffer M over gradients, with the default decay 0.95 and Nesterov correction enabled.
- Form the Nesterov-style update , an interpolation between the gradient and the updated momentum buffer (or use M directly when Nesterov is disabled).[2]
- Pass G' through a short Newton-Schulz iteration
zeropower_via_newtonschulz5that returns an approximately orthogonal matrix O of the same shape. - Apply the update , where lambda is the weight decay.[2] Moonshot's large-scale recipe uses in place of the aspect-ratio factor, with the constant 0.2 calibrating the per-element RMS of the orthogonalised step to roughly match that of an AdamW update.[3]
The Newton-Schulz routine is the algorithmic heart of Muon. Direct singular value decomposition would correctly produce the matrix sign of , but SVD is too slow for an inner-loop optimizer. Instead, Muon iterates a quintic polynomial that commutes with the SVD because it acts only through G' G'^T. The reference iteration normalises so its singular values lie in , then performs five updates of the form:
A = X @ X.T
B = b * A + c * (A @ A)
X = a * X + B @ X
with the tuned coefficients (a, b, c) = (3.4445, -4.7750, 2.0315).[1][2] Five iterations are sufficient to drive the singular values of to lie inside the band in bfloat16 arithmetic, which is empirically close enough to true orthogonality for optimization purposes.[1][2] Because every operation is a matrix-matrix multiply with no division or square root, the iteration runs entirely on the GPU's tensor cores and remains numerically stable at low precision.[1]
Two features distinguish Muon from a strict implementation of "matrix sign of the gradient":
- Momentum first, orthogonalization second. Muon orthogonalizes the momentum buffer, not the raw gradient. Keller Jordan's write-up notes that the design moves "momentum to before the orthogonalization, which we find performs better empirically," so the order matters.[1]
- Aspect-ratio scaling. The reference implementation multiplies the orthogonalized update by , while Moonshot's recipe uses so that the per-element update RMS stays roughly constant across matrix shapes and matches AdamW, letting the Muon and AdamW parameter groups share one learning rate.[2][3]
Default hyperparameters in the reference implementation are momentum 0.95, Nesterov enabled, five Newton-Schulz steps, base learning rate 0.02, and weight decay zero; the GitHub README states that only learning rate and weight decay typically need tuning.[2]
The coefficients (3.4445, -4.7750, 2.0315) were not derived analytically but found by direct numerical search against a target objective that pushes the singular values of the input toward unity in as few steps as possible. Franz Cesista, one of the named co-authors, has documented follow-up work that squeezes an additional 1 to 2 percent of efficiency out of Muon by optimizing a separate coefficient triple for each Newton-Schulz step rather than reusing the same triple for all five iterations.[19] The reference implementation still uses a single fixed triple for every step.[2]
A subtle but important property of the iteration is that it is a polynomial in X X^T, which means it commutes with the singular value decomposition: if , then zeropower_via_newtonschulz5(X) = U f(Sigma) V^T for some scalar function f. The Newton-Schulz design problem is to pick coefficients so that f maps the interval (0, 1] as close to the constant function 1 as possible after five iterations. The choice (3.4445, -4.7750, 2.0315) overshoots slightly so that the output singular values land in roughly [0.5, 1.5] rather than collapsing exactly to 1; the reference implementation notes that this spread "turns out not to hurt model performance at all" relative to exact orthogonalization.[2]
Which parameters does Muon apply to?
Muon is explicitly designed for the 2D weight matrices of hidden layers. The reference write-up is direct about the carve-out: "Scalar and vector parameters of the network, as well as the input and output layers, should be optimized by a standard method such as AdamW."[1] In practice that means leaving the following parameters to AdamW:
- input and output embedding matrices,
- classifier or unembedding heads,
- scalar gains and biases inside normalisation layers and gated activations,
- 1D parameters generally.
The argument for the carve-out is that embedding and unembedding rows correspond to individual tokens whose update statistics differ sharply from one another, so per-coordinate adaptive scaling is genuinely useful there; the orthogonalization step also has no obvious meaning when one dimension has length one. The reference Muon repository ships a MuonWithAuxAdam helper that performs parameter grouping automatically.[2]
What records did Muon set on the NanoGPT speedrun?
The most visible early adopter of Muon was the modded-nanogpt speedrun.[7] The challenge starts from a GPT-2-small-class transformer and lets competitors change the architecture; what it fixes is the training data stream, the validation target (3.28 on a held-out FineWeb shard), and the hardware budget (eight H100s); competitors race to minimise wall-clock training time. Selected records illustrate Muon's role:
| Record | Date | Wall-clock | Headline change |
|---|---|---|---|
| 1 | May 2024 | ~45 min | Karpathy llm.c GPT-2 baseline |
| 2 | 6 Jun 2024 | 31.4 min | Tuned LR plus rotary position embeddings |
| 3 | 4 Oct 2024 | 24.9 min | Switched hidden weights from AdamW to Muon |
| 5 | 14 Oct 2024 | 15.2 min | Architectural refinements on top of Muon |
| 12 | 19 Nov 2024 | 5.03 min | FlexAttention integration |
| 20 | 16 Jan 2025 | 2.99 min | Merged QKV projections plus attention tweaks |
| 50 | 18 Dec 2025 | 2.13 min | Cautious weight decay extended to Adam parameters |
| 62 | 19 Jan 2026 | 1.66 min | Bigram hash embedding |
| 80 | 8 Apr 2026 | 1.41 min | Muon orthogonalizes Q and K matrices in pairs of heads |
| 92 | 30 Aug 2026 | 0.67 min | Sampled softmax, hashed n-gram embedding table, ANVIL optimizer stack |
Sources: modded-nanogpt repository commit history and Keller Jordan's Muon write-up.[1][7]
Muon's introduction at Record 3 improved the speed record "to 3.28 val loss on FineWeb ... by a factor of 1.35x" over the previous AdamW-based record.[1] At larger scales, Keller Jordan's write-up reports that he "trained a 1.5B parameter transformer to GPT-2 XL level performance on HellaSwag in 10 8xH100-hours," adding that "using AdamW to achieve the same result takes 13.3 hours," a comparable ratio.[1] Muon was also used to set training-speed records for CIFAR-10, pushing a long-standing benchmark from 3.3 to 2.6 A100-seconds at fixed accuracy.[2]
The speedrun setting is unusual in several ways that matter for interpreting Muon's results. The model size is small (124M parameters), the dataset is fixed, the validation target is a single loss value rather than a benchmark suite, and the hardware budget is generous relative to model size. Some optimisations that help at this scale, including extremely large batch sizes, aggressive learning-rate schedules, and architectural compression, do not transfer directly to multi-billion-parameter pretraining. Nonetheless, the speedrun has been an unusually useful research environment because it forces every change to demonstrably reduce wall-clock training time on identical hardware, exposing the difference between methods that look better in offline plots and methods that actually run faster on a real GPU. Muon survived this test through 80-plus consecutive records, which is a strong signal that the speedup is real rather than an artefact of cherry-picked seeds or hyperparameter searches.[1][7][8]
How was Muon scaled to large language models?
The most important external validation of Muon came in February 2025 when researchers at Moonshot AI posted "Muon is Scalable for LLM Training" (arXiv:2502.16982).[3] The paper, with 28 named authors including Jingyuan Liu and Jianlin Su, opens by stating that "the Muon optimizer based on matrix orthogonalization has demonstrated strong results in training small-scale language models, but the scalability to larger models has not been proven," then identifies two adjustments that let Muon train large models out-of-the-box without per-scale hyperparameter sweeps:[3]
- Add weight decay. The reference Muon used weight decay zero, suitable for short speedrun-scale runs. For multi-trillion-token pretraining the authors set weight decay to 0.1, applied uniformly across all training stages, matching standard AdamW practice.[3]
- Adjust the per-parameter update scale to a target RMS. For an matrix update O_t, the Moonlight recipe is . The constant 0.2 matches the typical 0.2 to 0.4 update RMS produced by AdamW, so a model can switch optimizers without re-tuning the learning rate.[3]
With these changes, scaling-law experiments reported that "Muon only requires about 52% training FLOPs to match the performance of AdamW under compute-optimal setting," i.e. roughly 2x compute efficiency at compute-optimal token counts.[3]
The paper also introduced Moonlight, an open-weight Mixture-of-Experts model described as having "2.24B activated and 15.29B total parameters (3B activated and 16B total when including embedding)," trained with Muon on 5.7T tokens.[3] Moonlight reuses the DeepSeek V3-Small architecture (27 layers, hidden size 2,048, 64 routed experts plus 2 shared experts, with 6 routed experts active per token)[20] so that its results can be compared directly to the AdamW-trained DSV3-Small baseline. Selected benchmarks at roughly equal token budgets:[3]
| Benchmark | DSV3-Small (AdamW, 1.33T tokens) | Moonlight (Muon, 1.2T tokens) |
|---|---|---|
| MMLU | 53.3 | 60.4 |
| HumanEval | 26.8 | 37.2 |
| GSM8K | 31.4 | 45.0 |
Moonshot also described a distributed implementation, Distributed Muon, layered on top of ZeRO-1-style optimizer-state sharding. The added communication relative to Distributed AdamW is reported to be at most 1.25x (the paper states the communication workload is in the interval (1, 1.25] of Distributed AdamW), while the optimizer's own memory is half that of Distributed AdamW because Muon stores only one momentum buffer rather than two moment estimates.[3] Moonlight, intermediate checkpoints, and the Distributed Muon code were released under the MIT license through Moonshot's GitHub and Hugging Face organisations, with vLLM and SGLang integrations.[11]
The key engineering challenge for Distributed Muon was that the Newton-Schulz iteration is a dense matrix operation on the full update tensor, which is awkward under tensor-parallel or pipeline-parallel sharding. The Moonlight team resolved this inside a ZeRO-1 design: each data-parallel rank applies momentum to its partition of the gradient, gathers the partitions into the full matrix, runs the Newton-Schulz iteration on it, and keeps only the slice of the update that matches its local parameters, which are then all-gathered as in standard ZeRO-1. The paper notes that the gather can be overlapped with computation to reduce latency.[3] Later work moved distributed Muon onto PyTorch's FSDP2: NorMuon (Li et al., 2025), for example, ships an FSDP2 implementation that distributes the orthogonalization computations across devices.[14]
What is MuonClip, and how does it relate to Kimi K2?
Moonshot's follow-on system, Kimi K2, is a one-trillion-parameter MoE language model with 32B activated parameters released in 2025 and described in detail in the Kimi K2 technical report (arXiv:2507.20534).[4][5] The report states that Kimi K2 was "pre-trained on 15.5 trillion high-quality tokens" and that, during pretraining, "the training loss remains smooth and stable, with no observable spikes," using a Muon variant called MuonClip.[4][5] The team frames its optimizer choice plainly: "Muon substantially outperforms AdamW, making it an effective choice for improving token efficiency in large language model training."[4]
MuonClip addresses a failure mode that the Kimi team observed when scaling Muon: exploding attention logits. The report says the problem occurred more frequently with Muon than with AdamW in its experiments and caused training instability. It judged existing mitigations insufficient: logit soft-capping clips the logits only after the query-key dot products have already grown, and query-key normalisation cannot be applied to the multi-head latent attention (MLA) used in Kimi K2 because its key matrices are not fully materialized during inference.[4] MuonClip therefore adds a post-update step called QK-Clip: "QK-Clip works by rescaling the query and key projection weights post-update to bound the growth of attention logits," so for every attention head, whenever the maximum attention logit exceeds a threshold tau (the team reports tau = 100), the corresponding query and key weight matrices are rescaled in place so that the bound is restored.[4][5] This brings the logit magnitude back under control at the source without altering the forward computation.
The Kimi team reports that MuonClip enabled the entire Kimi K2 pretraining run to complete without a single loss spike, a property they attribute to QK-Clip rather than to Muon alone.[4][5] Kimi K2 benchmarks reported in the technical report include 65.8 on SWE-Bench Verified, 53.7 on LiveCodeBench v6, 49.5 on AIME 2025, 75.1 on GPQA-Diamond, and 66.1 on Tau2-Bench, placing it competitively among open-weight non-thinking models at release.[4]
Who else uses Muon?
Beyond Moonshot, Muon has been picked up by several other groups:
- Essential AI posted "Practical Efficiency of Muon for Pretraining" (arXiv:2505.02222, May 2025), with authors including Ashish Vaswani, Ishaan Shah, Anthony M. Polloreno, Karl Stratos, and Philip Monk.[12] The paper argues that Muon retains data efficiency at much larger batch sizes than AdamW, pushing beyond what the AdamW critical-batch-size literature would allow, and presents a "telescoping" hyperparameter-transfer algorithm with O(C log N) overhead. Their experiments use models up to 4B parameters.[12]
- Microsoft Research investigated Muon's effect on the grokking phenomenon in transformers, reporting that Muon significantly accelerates the delayed-generalisation transition compared to AdamW; Microsoft has also used Muon in the training of its on-device Mu language model that powers an agent in Windows Settings.[21]
- GLM-4.5 was trained with Muon for all parameters except word embeddings, biases, and RMSNorm weights, and Prime Intellect's INTELLECT-3, post-trained from the GLM-4.5-Air base model, used a distributed Muon implementation in its post-training runs.[22][23]
- NorMuon (Li et al., arXiv:2510.05491) layers per-row gradient normalisation onto Muon and ships a sharded FSDP2 implementation aimed at very large models.[14]
- The reference repository at github.com/KellerJordan/Muon is MIT-licensed and
pip install-able directly from GitHub; Muon has also been part of PyTorch itself since version 2.9 (October 2025) astorch.optim.Muon, following a feature request in issue #148819.[2][15][24]
Open-source ecosystems also include:
- MoonshotAI/Moonlight, the Distributed Muon implementation and Moonlight checkpoints, MIT-licensed, with Hugging Face hosting for weights and instruct variants.[11]
- MoonshotAI/Kimi-K2, hosting the Kimi K2 weights along with the MuonClip recipe described in the technical report.[4]
- Community PyTorch reimplementations in the Motif-Technologies optimizer collection and in various educational repositories.
What is the theory behind Muon?
The theoretical case for Muon is most fully developed in Jeremy Bernstein's "Deriving Muon" essay and in Bernstein and Newhouse's "Modular Duality in Deep Learning" (arXiv:2410.21265, October 2024).[9][10] Their framing is that any first-order optimizer can be viewed as steepest descent under some choice of norm on the parameter space; the gradient itself is a dual vector and must be mapped back to the primal weight space before it can be subtracted from the weights. For dense linear layers, equipping the layer with the RMS-to-RMS operator norm (the spectral norm scaled by for an matrix) and dualising yields exactly the matrix sign update implemented by Muon.[9][10] In this view:
- The orthogonalisation is the duality map, not a heuristic regulariser.
- The Newton-Schulz iteration is a GPU-friendly substitute for SVD that preserves commutation with the singular value structure because each polynomial step is odd in X.[9]
- The RMS-to-RMS norm choice, rather than the bare spectral norm, is what enables learning-rate transfer across width and is closely related to the construction of maximal update parameterisation (muP).[10]
- The connection to Shampoo is concrete: a simplified Shampoo update is essentially Muon's orthogonalisation applied less aggressively and with extra preconditioner caching.[6][10]
Subsequent papers have begun to formalise Muon's convergence. Among them are "A Note on the Convergence of Muon" (arXiv:2502.02900), "On the Convergence Analysis of Muon" (arXiv:2505.23737), and "Towards Understanding Orthogonalization in Muon" (OpenReview, 2025), which analyse Muon as a non-Euclidean stochastic gradient method under the spectral or Frobenius norm.[16] Thinking Machines Lab's "Modular Manifolds" essay places Muon inside a broader framework that treats each layer's weight space as a manifold with its own metric.[17]
Why does Muon matter?
Muon's significance is twofold. Algorithmically, it is among the first matrix-aware optimizers demonstrated in frontier-scale language model pretraining, a setting long dominated by AdamW. Moonshot reports a roughly 2x compute saving for compute-optimal scaling, though whether that holds across other architectures and data mixtures is still being tested.[3] Conceptually, it has popularised the view that optimizers should respect the geometry of the parameters they update: a transformer hidden layer is a matrix, and the natural update direction is also a matrix object, not a coordinate-wise rescaling of one.[9][10]
For practitioners, Muon also has favourable systems properties:
- Memory: Muon stores one momentum buffer per matrix, versus AdamW's two moment buffers, roughly halving optimizer-state memory.[3]
- Bandwidth: The Newton-Schulz iteration is dense matrix multiplication, well suited to H100 tensor cores and stable in bfloat16.[1]
- Determinism: No division by per-parameter variance estimates means fewer sources of denormal numerics.
What are the limitations of Muon?
Muon is not without caveats:
- Not a drop-in replacement. Muon should not be applied to embeddings, classifier heads, biases, or normalisation gains; the recommended setup uses Muon plus AdamW in parallel, requiring parameter grouping.[1][2]
- Approximate orthogonalisation. The five-step Newton-Schulz iteration produces singular values that lie roughly inside [0.5, 1.5] rather than exactly 1; Keller Jordan reports this does not hurt performance, but it leaves open how to choose the polynomial coefficients for non-default step counts or for unusual matrix aspect ratios.[1] The "Beyond the Ideal: Analyzing the Inexact Muon Update" paper (arXiv:2510.19933) studies the resulting error term.[18]
- Attention-logit instabilities at scale. The need for MuonClip in Kimi K2 indicates that vanilla Muon can produce exploding attention logits when training is scaled up; this is a real engineering complication for trillion-parameter training.[4][5]
- Convergence theory still developing. Several 2025 papers provide convergence guarantees, but the full picture under realistic non-convex objectives with momentum, weight decay, and batched stochasticity is not yet settled.[16]
- Hyperparameter advice still evolving. The Moonshot recipe (weight decay 0.1, RMS-matched update scale) emerged only after deliberate experimentation; transferring it to new architectures or to MoE variants beyond Moonlight may require further tuning.[3]
- Ecosystem maturity. Muon entered
torch.optimonly with PyTorch 2.9 in October 2025, years after AdamW, and distributed implementations vary in quality across the open-source landscape.[24]
How does Muon compare to AdamW and other optimizers?
| Optimizer | Type of update | Per-parameter memory | Notable property |
|---|---|---|---|
| SGD with momentum | First-order, coordinate-wise | 1 buffer | Baseline; no adaptive scaling |
| Adam / AdamW | First-order, coordinate-wise adaptive | 2 buffers | Industry standard for transformers |
| Shampoo | Second-order, block-diagonal preconditioner | Matrix factor statistics | Matrix-aware; expensive inverses |
| SOAP | Shampoo eigenbasis with Adam inside | Adam plus Shampoo factors | Combines first- and second-order signals |
| Lion | First-order, sign of momentum | 1 buffer | Coordinate-wise sign update; memory-light |
| Muon | First-order on momentum, matrix sign | 1 buffer | Matrix-aware via Newton-Schulz; orthogonal step direction |
| MuonClip | Muon plus QK-Clip post-step | 1 buffer | Stabilises attention logits at trillion-parameter scale |
The most important contrasts: relative to AdamW, Muon halves optimizer-state memory (one momentum buffer instead of two moment estimates) and, per Moonshot's scaling-law experiments, reaches the same loss with roughly 52 percent of the FLOPs at compute-optimal settings, at the cost of needing AdamW alongside it for embeddings and 1D parameters.[3] Muon shares Lion's memory frugality but operates on matrices rather than coordinates; it shares Shampoo's matrix awareness but is dramatically cheaper per step because Newton-Schulz replaces full preconditioner inverses.[6]
Continue reading
- AdamWAdamW is a variant of the Adam optimizer that decouples weight decay from the gradient-based update rule, applying the decay directly to the weights instead of folding it into the loss as an L2 penalty.Mentioned 35 times above
- OptimizerAn optimizer in machine learning is an algorithm that iteratively adjusts a model's learnable parameters to minimize (or maximize) an objective function, commonly called a loss functionMentioned 22 times above
- MomentumMomentum is an optimization technique that accelerates gradient descent by accumulating an exponentially weighted moving average of past gradients into a velocity vector and using that velocity, rather than…Mentioned 22 times above
- Weight DecayWeight decay is a regularization technique used in training neural networks that shrinks every parameter toward zero by a small fraction on each update stepMentioned 11 times above
- Kimi K2Kimi K2 is an open-weights Mixture of Experts language model from Moonshot AI, a Beijing startup, released on July 11, 2025 with 1.04 trillion total parameters and 32.6 billion activated per tokenMentioned 10 times above
- Adam optimizerThe Adam optimizer (short for Adaptive Moment Estimation) is an algorithm for first-order gradient descent-based optimization of stochastic objective functionsMentioned 8 times above
More from See also
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19Keller Jordan, "Muon: An optimizer for hidden layers in neural networks", kellerjordan.github.io, 2024-12-08. kellerjordan.github.io/...muon. Accessed 2026-06-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15Keller Jordan et al., "KellerJordan/Muon: Muon is an optimizer for hidden layers in neural networks", GitHub, 2024. github.com/...Muon. Accessed 2026-06-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16Jingyuan Liu, Jianlin Su, Xingcheng Yao, Zhejun Jiang, Guokun Lai, Yulun Du, Yidao Qin, Weixin Xu, Enzhe Lu, Junjie Yan et al., "Muon is Scalable for LLM Training", arXiv:2502.16982, 2025-02-24. arxiv.org/...2502.16982. Accessed 2026-06-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10Kimi Team, "Kimi K2: Open Agentic Intelligence", arXiv:2507.20534, 2025-07-28 (revised 2026-02-03). arxiv.org/...2507.20534. Accessed 2026-06-21.
- ^1 ^2 ^3 ^4 ^5 ^6MoonshotAI, "Kimi-K2: Open-weight agentic language model", GitHub, 2025. github.com/...Kimi-K2. Accessed 2026-06-21.
- ^1 ^2 ^3Nikhil Vyas, Depen Morwani, Rosie Zhao, Itai Shapira, David Brandfonbrener, Lucas Janson, Sham Kakade, "SOAP: Improving and Stabilizing Shampoo using Adam", Harvard University, 2024. lucasjanson.fas.harvard.edu/...am-Vyas_ea-2024.pdf. Accessed 2026-06-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Keller Jordan, "KellerJordan/modded-nanogpt: NanoGPT (124M) in 90 seconds", GitHub, 2024-2026. github.com/...modded-nanogpt. Accessed 2026-06-21.
- ^Tyler Romero, "NanoGPT Speedrun Living Worklog", tylerromero.com, 2025. tylerromero.com/...nanogpt-speedrun-worklog. Accessed 2026-06-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Jeremy Bernstein, "Deriving Muon", jeremybernste.in, 2025-03-07. jeremybernste.in/...deriving-muon. Accessed 2026-06-21.
- ^1 ^2 ^3 ^4 ^5 ^6Jeremy Bernstein and Laker Newhouse, "Modular Duality in Deep Learning", arXiv:2410.21265, 2024-10-28. arxiv.org/...2410.21265. Accessed 2026-06-21.
- ^1 ^2MoonshotAI, "Moonlight: Muon is Scalable for LLM Training", GitHub, 2025. github.com/...Moonlight. Accessed 2026-06-21.
- ^1 ^2Ishaan Shah, Anthony M. Polloreno, Karl Stratos, Philip Monk, Adarsh Chaluvaraju, Ashish Vaswani et al., "Practical Efficiency of Muon for Pretraining", arXiv:2505.02222, 2025-05-04. arxiv.org/...2505.02222. Accessed 2026-06-21.
- MarkTechPost, "Muon Optimizer Significantly Accelerates Grokking in Transformers: Microsoft Researchers Explore Optimizer Influence on Delayed Generalization", marktechpost.com, 2025-04-22. marktechpost.com/...ence-on-delayed-generalization. Accessed 2026-06-21.
- ^1 ^2Zichong Li et al., "NorMuon: Making Muon more efficient and scalable", arXiv:2510.05491, 2025. arxiv.org/...2510.05491. Accessed 2026-06-21.
- ^PyTorch contributors, "Addition of muon optimizer to torch.optim", GitHub Issue #148819, 2025. github.com/...148819. Accessed 2026-06-21.
- ^1 ^2Authors of arXiv:2502.02900 and arXiv:2505.23737, "A Note on the Convergence of Muon" and "On the Convergence Analysis of Muon", arXiv, 2025. arxiv.org/...2502.02900 and arxiv.org/...2505.23737. Accessed 2026-06-21.
- ^Thinking Machines Lab, "Modular Manifolds", thinkingmachines.ai, 2025. thinkingmachines.ai/...modular-manifolds. Accessed 2026-06-21.
- ^Authors of arXiv:2510.19933, "Beyond the Ideal: Analyzing the Inexact Muon Update", arXiv, 2025. arxiv.org/...2510.19933. Accessed 2026-06-21.
- ^Franz Louis Cesista, "Squeezing 1-2% Efficiency Gains Out of Muon by Optimizing the Newton-Schulz Coefficients", leloykun.github.io, 2025-02-21. leloykun.github.io/...muon-opt-coeffs. Accessed 2026-11-05.
- ^Moonshot AI, "Moonlight-16B-A3B config.json", Hugging Face, 2025. huggingface.co/...config.json. Accessed 2026-11-05.
- ^Microsoft, "Introducing Mu language model and how it enabled the agent in Windows Settings", Windows Experience Blog, 2025-06-23. blogs.windows.com/...the-agent-in-windows-settings. Accessed 2026-11-05.
- ^GLM-4.5 Team, "GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models", arXiv:2508.06471, 2025. arxiv.org/...2508.06471. Accessed 2026-11-05.
- ^Prime Intellect, "INTELLECT-3: Technical Report", arXiv:2512.16144, 2025-12-18. arxiv.org/...2512.16144. Accessed 2026-11-05.
- ^1 ^2PyTorch, "torch.optim.Muon", PyTorch 2.9 documentation, 2025. docs.pytorch.org/...torch.optim.Muon. Accessed 2026-11-05.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
7 revisions by 1 contributor · v7 · 4,860 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (120 claims, 31 sources fetched); 8 material + 24 minor fixed
Cite this page: AI Wiki. "Muon (optimizer)." aiwiki.ai, updated 27 Jun 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/muon_optimizer