

Noam Shazeer
Noam Shazeer (born 1975 or 1976) is an American computer scientist and software engineer who is one of the most prolific and influential researchers in the modern era of deep learning, best known as a co-author of the 2017 paper Attention Is All You Need and as the inventor or co-inventor of many of the core techniques inside today's large language models. The paper, which he co-wrote with seven Google colleagues, introduced the Transformer architecture that now underlies essentially all contemporary large language models, and Shazeer is separately credited with the sparsely-gated Mixture-of-Experts layer, the Mesh-TensorFlow framework for model parallelism, multi-query attention, GLU activation variants such as SwiGLU and GEGLU, the Adafactor optimizer, the T5 text-to-text transfer transformer, and the Switch Transformer.[1][2][3]
Shazeer spent roughly two decades at Google (joining in 2000), where he was an early engineer on advertising and search infrastructure; after a few years away from the company he rejoined Google in 2012 to work with the Google Brain research team.[30] He left Google in October 2021, reportedly after the company declined to publicly release a conversational chatbot he had built with Daniel De Freitas, and co-founded the consumer AI company Character.AI, which filed for Chapter 11 bankruptcy in October 2026.[4][5][39] In August 2024, in one of the highest-profile "reverse acqui-hire" transactions in Silicon Valley history, Google paid approximately $2.7 billion to license Character.AI's technology and brought Shazeer back, where he became co-technical lead of the Gemini model effort alongside Jeff Dean and Oriol Vinyals.[6][7][8] Less than two years later, on 17 June 2026, Shazeer announced that he was leaving Google to join OpenAI to lead its AI architecture research.[31][34]
In 2023 Time magazine named Shazeer one of the 100 most influential people in artificial intelligence, and in February 2026 he was elected to the U.S. National Academy of Engineering as part of its Class of 2026.[9][10] Together, his combination of a long single-author technical track record, a near-uniquely broad set of foundational contributions, and his senior technical roles on Google's Gemini program and then at OpenAI has made him one of the most-discussed individual figures in the post-ChatGPT period of artificial-intelligence development.
Key facts
| Field | Detail |
|---|---|
| Born | 1975 or 1976 (Philadelphia, Pennsylvania, U.S.)[1] |
| Nationality | American |
| Education | Duke University, B.S. in mathematics and computer science (1994-1998)[1] |
| Known for | Co-author of Attention Is All You Need; Mixture-of-Experts; T5; Mesh-TensorFlow; multi-query attention; Adafactor; SwiGLU/GEGLU; Switch Transformer[1][2] |
| Affiliations | Google (2000-2021, with a break of a few years before 2012), Character.AI (2021-2024), Google / Google DeepMind (2024-2026), OpenAI (2026-present)[1][5][31] |
| Current role | Lead for AI architecture research, OpenAI (from June 2026)[34] |
| Honors | Time 100 in AI (2023); National Academy of Engineering (2026)[9][10] |
Early life and education
Shazeer was born in Philadelphia, Pennsylvania, in 1975 or 1976. He attended grade school at Cohen Hillel Academy in Marblehead, Massachusetts, and Swampscott High School in Swampscott, Massachusetts.[1] As a high school student he competed on the U.S. team at the 1994 International Mathematical Olympiad in Hong Kong, where he won a gold medal with a perfect score.[1][12]
From 1994 to 1998 he studied mathematics and computer science at Duke University, where he held an Angier B. Duke Memorial Scholarship (Duke's most selective merit scholarship) and was a star member of Duke's prize-winning Putnam team. In his first semester he finished in the group of five individuals ranked directly after the five Putnam Fellows on the William Lowell Putnam Mathematical Competition, and as a member of Duke's math team he won further Putnam prizes; Duke placed first in the team competition in 1996 and second in 1997.[1][37][38] He earned a Bachelor of Science degree in mathematics and computer science from Duke in 1998, and briefly entered a graduate program at the University of California, Berkeley, before leaving without completing a doctorate.[1] His Olympiad and Putnam track record, taken together with his later research output, has been frequently cited as evidence that elite competitive-mathematics ability can translate directly into productive machine-learning research.
What did Noam Shazeer do at Google (2000-2021)?
Early years: search, spell-checking, and PHIL/AdSense
Shazeer joined Google in 2000, when the company was still a young start-up.[1] One of his earliest contributions was a substantial rewrite of Google's web-search spell-checker. The new spell-checker used statistical models trained on the web's own text to detect and correct misspellings, and became one of the search engine's most visible early uses of language models.[1][14][30]
He later co-developed, with fellow early Google engineer Georges Harik, a probabilistic page-classification system known internally as PHIL (typically expanded as "Probabilistic Hierarchical Inferential Learner"), which categorized web pages by topic by learning the co-occurrence patterns of terms and concepts.[1][14][29] PHIL was used to match contextually relevant ads to publisher pages and, according to Steven Levy's In the Plex, was the in-house technology that actually powered Google's content-targeted advertising product, AdSense, even though the AdSense brand had been inherited from the externally acquired Applied Semantics company.[29] Shazeer's contributions in this period helped him earn a reputation inside Google as an unusually productive engineer with a deep grasp of large-scale statistical modeling.
Google Brain (2012-2021)
In 2012, after a few years away from Google, Shazeer rejoined the company to work with the newly formed Google Brain research group, where Jeff Dean and others were experimenting with applying very large neural networks to speech, vision, and language tasks.[30] Over the following decade he became one of Brain's most prolific authors and was widely regarded as the team's principal architect of large-scale neural-language models.
Across the 2010s Shazeer's research output focused on three intertwined themes: (1) increasing model capacity through conditional computation and sparsity; (2) increasing model throughput through better attention mechanisms, optimizers, and parallelism primitives; and (3) unifying NLP tasks under a single sequence-to-sequence formulation. Many of the techniques he and his collaborators introduced are now standard components of frontier large language models. In a 2025 retrospective interview on the Dwarkesh Podcast, Shazeer and Jeff Dean discussed his role across this era; Dwarkesh Patel summarized that Shazeer had "invented or co-invented all the main architectures and techniques that are used for modern LLMs: from the Transformer itself, to Mixture of Experts, to Mesh Tensorflow, to Gemini and many other things."[30]
His first major Brain-era contribution was Exploring the Limits of Language Modeling (Józefowicz, Vinyals, Schuster, Shazeer & Wu, 2016), an empirical study of scaling LSTM language models on the One Billion Word Benchmark that prefigured the systematic scaling work he would do later in the decade.
What are Noam Shazeer's main research contributions?
Sparsely-gated Mixture-of-Experts (2017)
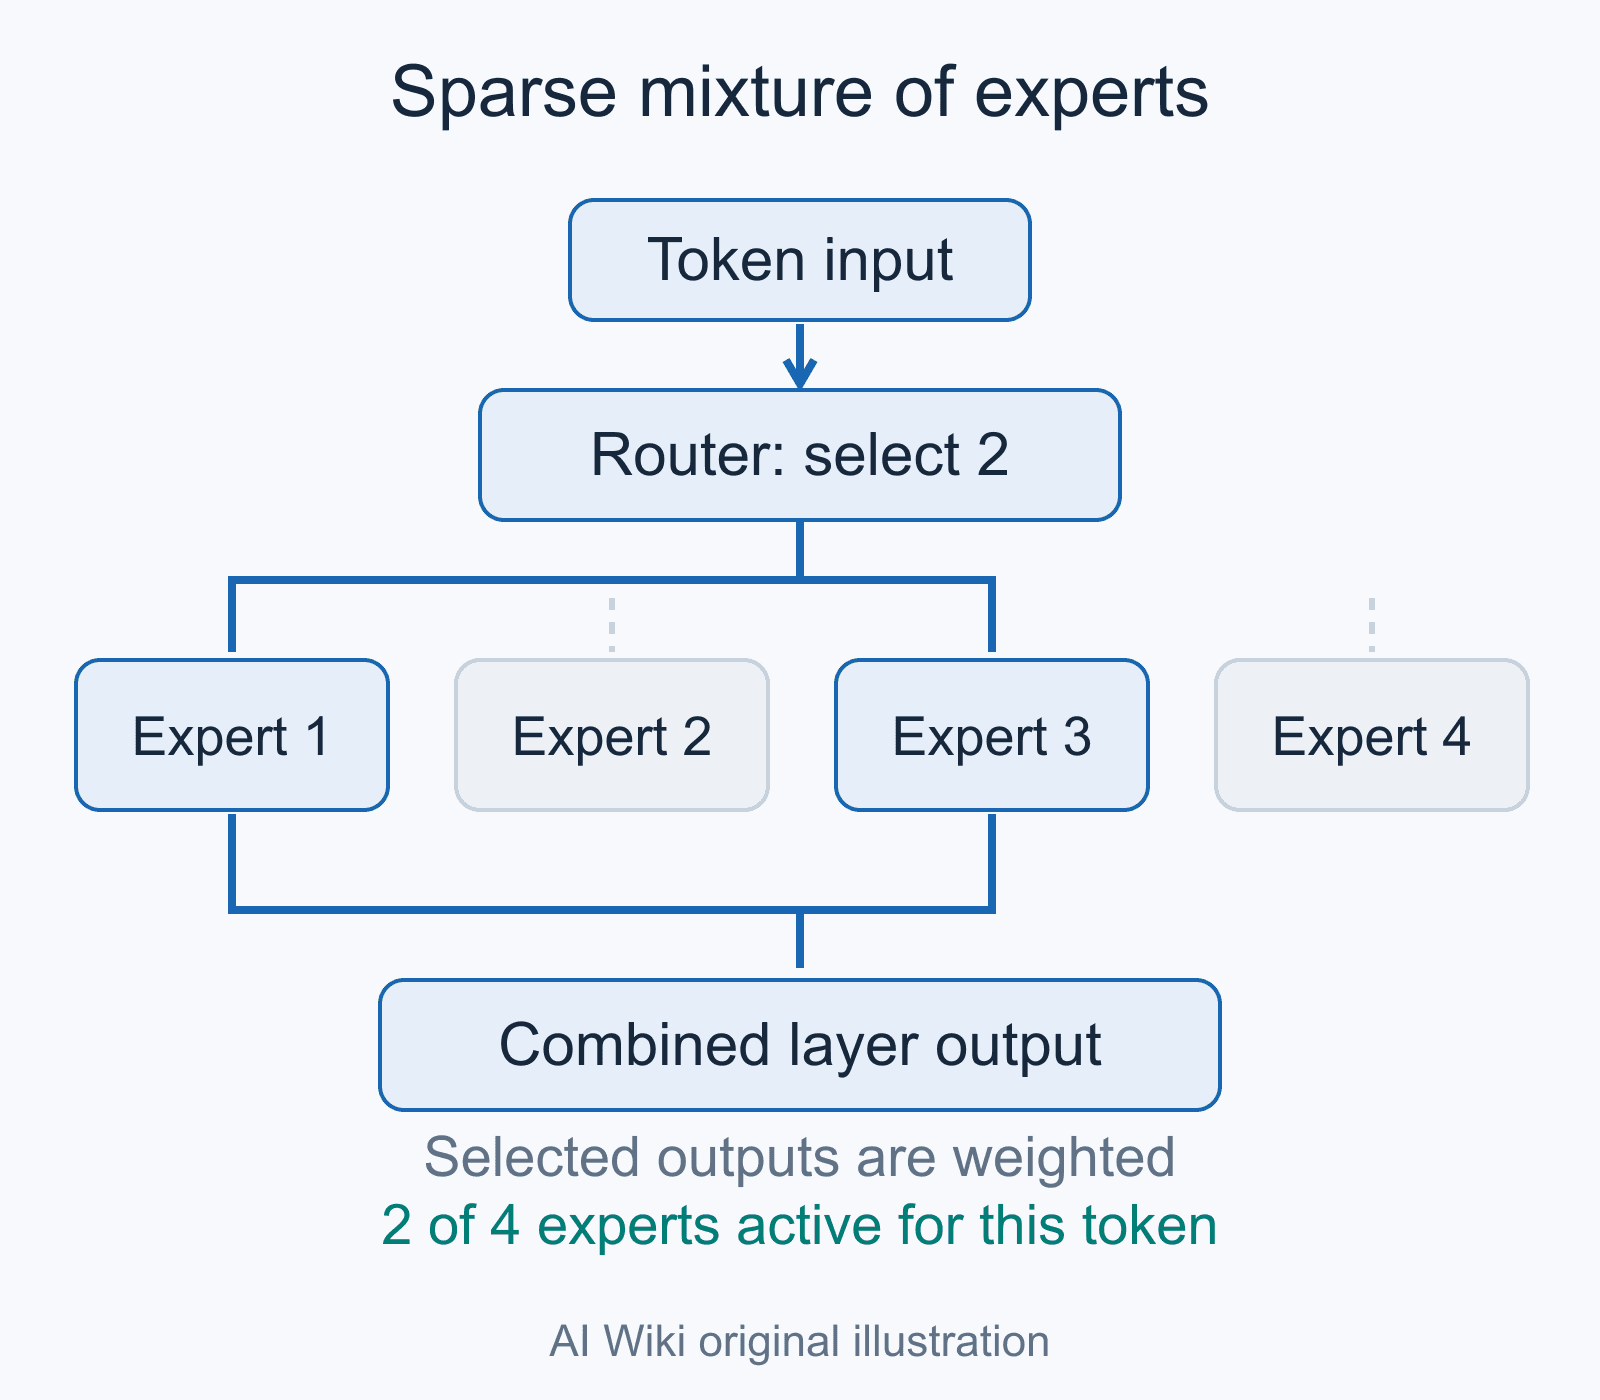
In January 2017 Shazeer and collaborators (Azalia Mirhoseini, Krzysztof Maziarz, Andy Davis, Quoc Le, Geoffrey Hinton and Jeff Dean) published Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer.[2] The paper introduced a layer consisting of up to thousands of small feed-forward expert sub-networks plus a trainable gating network that selects only a small sparse subset of experts to evaluate for each input. By activating only a few experts per token, the layer makes it possible to expand a model's parameter count by orders of magnitude while keeping its per-example computational cost roughly fixed.[2]
Applied between stacked LSTM layers, the technique produced language and translation models with up to 137 billion parameters that significantly outperformed dense state-of-the-art models at comparable compute.[2] The Sparsely-Gated MoE layer is the direct ancestor of every modern Mixture-of-Experts language model: from Google's GShard, Switch Transformer and GLaM, to Mixtral, the MoE versions of Gemini, and DeepSeek's models (OpenAI has not disclosed whether GPT-4 uses MoE). The paper also established two ideas that have proven durable across all subsequent MoE work: (i) using a learned, sparse top-k gate to route tokens to a small subset of experts, and (ii) adding auxiliary load-balancing losses to keep expert utilisation roughly uniform during training.[2]
Attention Is All You Need (2017)
In June 2017 Shazeer was one of eight co-authors of Attention Is All You Need, published on arXiv on 12 June 2017 and presented at NeurIPS later that year.[3][15] The paper introduced the Transformer architecture, a sequence-to-sequence neural network that replaces recurrence and convolution with a stack of scaled dot-product self-attention layers and position-wise feed-forward networks.[3]
All eight authors (Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez (aidan gomez), Łukasz Kaiser, and Illia Polosukhin) are credited as equal contributors and listed in randomized order.[3][15] In the paper's footnote of acknowledgements, Shazeer is specifically credited with proposing scaled dot-product attention, multi-head attention, and the parameter-free positional representation, and with being "the other person involved in nearly every detail."[15] The paper has since become one of the most cited works in computer science and is the foundational reference for modern large language models. For the full architecture and history, see Attention Is All You Need.
Several of the design choices the paper attributes to Shazeer, including scaled dot-product attention (dividing the dot-product by the square root of the head dimension to stabilise softmax gradients), splitting attention into multiple parallel heads, and using sinusoidal position encodings, are now textbook material; subsequent work on attention variants (multi-query attention, grouped-query attention, FlashAttention, rotary position embeddings, etc.) has refined rather than replaced this basic structure.[3][15]
Mesh-TensorFlow (2018)
Training models with billions of parameters quickly outgrew the memory of any single accelerator. In November 2018 Shazeer and a Google Brain team (Youlong Cheng, Niki Parmar, Dustin Tran, Ashish Vaswani (ashish vaswani), Penporn Koanantakool, Peter Hawkins, HyoukJoong Lee, Mingsheng Hong, Cliff Young, Ryan Sepassi, and Blake Hechtman) introduced Mesh-TensorFlow: Deep Learning for Supercomputers at NeurIPS 2018.[16] Mesh-TensorFlow is a language for specifying distributed tensor computations in which the user can declare that any tensor dimension is split across any dimension of a multi-dimensional mesh of processors. This enabled a clean expression of model parallelism (splitting individual weight tensors across many chips) in addition to the more common data parallelism. The paper demonstrated Mesh-TensorFlow on Transformer models with up to 5 billion parameters on TPU meshes of up to 512 cores.[16] Mesh-TensorFlow was an important conceptual precursor to today's large-model parallelism systems such as GSPMD, JAX's pjit / shard_map, and DeepSpeed.
Adafactor optimizer (2018)
Together with Mitchell Stern, Shazeer published Adafactor: Adaptive Learning Rates with Sublinear Memory Cost at ICML 2018.[17] Standard adaptive optimizers such as Adam maintain two extra tensors per parameter (first and second moments), doubling or tripling the memory footprint of training. Adafactor maintains only per-row and per-column statistics of weight matrices, reconstructing per-parameter second-moment estimates from these factorized statistics. Combined with update clipping and a gradually increasing second-moment decay rate (and with momentum dropped), the optimizer achieves results comparable to Adam while using sublinear auxiliary memory, making it possible to train much larger Transformer models on the same hardware.[17] Adafactor became the default optimizer for T5 and many later very-large-model training runs.
T5: Text-to-Text Transfer Transformer (2019)
In October 2019, Colin Raffel, Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J. Liu published Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer, introducing the T5 model family and the C4 (Colossal Clean Crawled Corpus) pre-training dataset.[18] T5 recast every NLP task (translation, summarization, classification, question answering) as a text-to-text problem: a string in, a string out. This unified formulation, combined with a systematic empirical study of pre-training objectives, model sizes, and dataset sizes, established a new state of the art on a wide range of NLP benchmarks and influenced the design of virtually every subsequent encoder-decoder language model.[18]
Multi-query attention (2019)
In November 2019 Shazeer single-authored Fast Transformer Decoding: One Write-Head Is All You Need, which proposed multi-query attention (MQA).[19] In a standard multi-head attention layer, each attention head maintains its own keys and values; during autoregressive decoding this requires loading a separate key/value cache per head per layer, and the resulting memory bandwidth becomes the dominant cost of inference. MQA shares a single set of keys and values across all heads, drastically reducing the size of the key/value cache and dramatically improving decoding throughput, with only minor quality degradation.[19] MQA, and its later generalization grouped-query attention (GQA), are now standard in production large language models such as PaLM 2, LLaMA, Mistral, and the Gemini family.
GLU Variants Improve Transformer / SwiGLU (2020)
In February 2020 Shazeer published a short single-author paper, GLU Variants Improve Transformer, which explored replacing the standard ReLU/GELU activation in the Transformer feed-forward sub-layer with variants of the Gated Linear Unit (GLU).[20] Among the variants introduced were GEGLU (using GELU as the gating non-linearity) and SwiGLU (using Swish). The paper showed that GEGLU and SwiGLU produced consistent improvements in perplexity over ReLU and GELU baselines.[20] SwiGLU was subsequently adopted as the standard feed-forward activation in PaLM, LLaMA, Mistral, Gemini and many other modern large language models.
Switch Transformer (2021)
In January 2021, William Fedus, Barret Zoph, and Shazeer published Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity.[21] The Switch Transformer simplified the Mixture-of-Experts routing scheme by sending each token to exactly one expert (top-1 routing), which substantially reduced the communication and load-balancing costs of MoE training.[21] Built on top of T5, the Switch Transformer achieved up to seven-times speed-ups in pre-training over dense baselines at the same compute budget and was scaled to over one trillion total parameters, among the first publicly described language models to reach that scale. The paper was published in the Journal of Machine Learning Research in 2022.[21] The Switch Transformer's simplified routing and load-balancing loss influenced later MoE models, although many production models, such as Mixtral (top-2) and DeepSeek-MoE (several fine-grained experts plus shared experts), route each token to more than one expert.
PaLM and other late-Brain contributions (2021-2022)
Shazeer was one of dozens of contributors to Google's PaLM: Scaling Language Modeling with Pathways, the 540-billion-parameter dense Transformer that briefly held the title of largest publicly described dense language model and that demonstrated strong few-shot performance on hundreds of language and reasoning benchmarks.[22] PaLM was trained on 6,144 TPU v4 chips across two pods using Google's then-new Pathways system; many of its architectural choices, including SwiGLU feed-forwards, multi-query attention, parallel attention/feed-forward layers, and rotary positional embeddings, build directly on Shazeer-era Brain research, with the SwiGLU activation and multi-query attention components originating in Shazeer's own single-author papers.[22][19][20] PaLM's release in April 2022 was widely seen as Google's headline counter to OpenAI's GPT-3 and was the immediate technical antecedent of the Bard / Gemini effort.
LaMDA / Meena and the path to public chatbots
Inside Google, Shazeer and Daniel De Freitas led the development of a large open-domain dialogue model originally called Meena and later renamed LaMDA (Language Model for Dialogue Applications).[4][5][23] Meena, described in a January 2020 Google paper, was a 2.6-billion-parameter open-domain chatbot; it was followed by LaMDA, a family of Transformer-based dialogue models with up to 137 billion parameters.[23][35][36] The team built a system capable of strikingly fluent multi-turn conversation; however, Google's leadership declined to release the model publicly, citing concerns about safety, fairness, and the reputational risk of consumer-facing chatbots. The disagreement over public release was widely reported as a principal reason for Shazeer's and De Freitas's eventual departure from the company in 2021.[4][5]
Why did Shazeer leave Google to found Character.AI (2021-2024)?
Shazeer left Google in October 2021.[5] Together with Daniel De Freitas (daniel de freitas) he co-founded Character Technologies, Inc., doing business as Character.AI, which incorporated in November 2021.[24] Character.AI's product was a consumer web (and later mobile) application that let users create and chat with AI characters, including original personas, fictional figures, historical figures, or assistants, built on top of a custom large language model trained in-house.[24]
The company raised an initial $43 million in seed funding shortly after incorporation, and in March 2023 closed a $150 million Series A round led by Andreessen Horowitz at an approximately $1 billion valuation, with participation from Nat Friedman, Elad Gil, SV Angel, and A.Capital.[25][26] Character.AI's public beta launched in September 2022, its iOS and Android apps launched in May 2023 (and were downloaded more than 1.7 million times in their first week), and the optional Character.AI+ subscription tier was introduced the same month.[24]
By early 2024 Character.AI had become one of the most-used consumer AI products on the web, with millions of daily active users, the majority of them under 30; the company reported roughly 3.5 million daily visitors as of January 2024.[24] Throughout this period Shazeer served as Character.AI's chief executive officer and De Freitas as its president.[5][24]
Shazeer's stated thesis for Character.AI was that conversational AI should be a mass-market consumer product rather than purely an enterprise tool, and that a small team able to ship directly to end users would iterate faster on safety, personality, and product fit than a research division embedded inside a large incumbent.
How did Shazeer return to Google to lead Gemini (August 2024)?
On 2 August 2024 Google and Character.AI jointly announced an arrangement in which Google would license Character.AI's underlying model technology on a non-exclusive basis, provide Character.AI with substantial additional funding, and hire Shazeer, De Freitas, and a small number of Character.AI's researchers into Google.[6] Press reporting from Reuters, The Information, the Wall Street Journal and others described the transaction as a "reverse acqui-hire" worth approximately $2.7 billion, paid out as licensing fees rather than as an acquisition price, in a structure that some analysts argued was designed to avoid antitrust review.[7][8][27] Subsequent reporting indicated that the U.S. Department of Justice opened an inquiry into the deal's structure.[8] Press accounts estimated Shazeer's personal share of the proceeds at $750 million-$1 billion.[1]
At Google, Shazeer was given the title of Vice President of Engineering and was announced (in an internal Google memo first reported by The Information) as one of three co-technical leads of the Gemini model effort, working alongside Jeff Dean (Google's chief scientist) and Oriol Vinyals.[11] In its public statement, Google described Shazeer as "a preeminent researcher in machine learning."[6]
Since rejoining Google, Shazeer served as a co-technical lead of the Gemini models during the development of the Gemini 2.5 family, including Gemini 2.5 Pro and Gemini 2.5 Flash, and of Gemini 3, which launched in November 2025.[11][30][31]
In a February 2025 Dwarkesh Podcast interview alongside Jeff Dean, the two discussed a vision, set out mainly by Dean, of a single modular mixture-of-experts model that could be continuously grown and updated, and Shazeer embraced forecasts of very large numbers of automated AI researchers running in Google's data centers.[30]
When did Noam Shazeer join OpenAI?
On 17 June 2026, less than two years after his $2.7 billion return to Google, Shazeer announced that he was leaving Google to join OpenAI; OpenAI Chief Research Officer Mark Chen said Shazeer would be the company's lead for AI architecture research.[31][32][34] In a post on X he wrote, "I'm excited to share that I'll be joining OpenAI and look forward to working with the exceptional team there," and OpenAI chief executive Sam Altman publicly welcomed him as "one of the people I have most wanted to work with since the very beginning of openai."[33]
CNBC and other outlets framed the move as a major talent shift in the frontier-AI race, noting that it came less than two years after Google brought him back through its reported $2.7 billion deal with Character.AI.[31][32] The hire came weeks after OpenAI, the maker of ChatGPT, confidentially filed for an initial public offering.[31]
Recognition and honors
- 1994: gold medal (perfect score), 35th International Mathematical Olympiad, Hong Kong (USA team).[12]
- 1994: ranked among the next five individuals after the Putnam Fellows, William Lowell Putnam Mathematical Competition; 1996 and 1997: member of the Duke math team while Duke placed first and second in the team competition.[1][37][38]
- 2023: Time 100 in AI list.[9]
- 2026: Elected member of the U.S. National Academy of Engineering.[10]
Selected publications
- Shazeer, N. et al. Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer. ICLR 2017. arXiv:1701.06538.[2]
- Vaswani, A.; Shazeer, N. et al. Attention Is All You Need. NeurIPS 2017. arXiv:1706.03762.[3]
- Shazeer, N. et al. Mesh-TensorFlow: Deep Learning for Supercomputers. NeurIPS 2018. arXiv:1811.02084.[16]
- Shazeer, N.; Stern, M. Adafactor: Adaptive Learning Rates with Sublinear Memory Cost. ICML 2018. arXiv:1804.04235.[17]
- Raffel, C.; Shazeer, N. et al. Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer. JMLR 2020. arXiv:1910.10683.[18]
- Shazeer, N. Fast Transformer Decoding: One Write-Head Is All You Need. arXiv:1911.02150 (2019).[19]
- Shazeer, N. GLU Variants Improve Transformer. arXiv:2002.05202 (2020).[20]
- Fedus, W.; Zoph, B.; Shazeer, N. Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity. JMLR 2022. arXiv:2101.03961.[21]
- Chowdhery, A. et al. (incl. Shazeer, N.). PaLM: Scaling Language Modeling with Pathways. JMLR 2023. arXiv:2204.02311.[22]
Continue reading
- Character.AICharacter.AI (stylized as character.ai or c.ai) is an AI chatbot platform that lets users create and converse with virtual characters powered by large language models, founded in November 2021 by former Google…Mentioned 17 times above
- Gemini (language model)Gemini is a family of natively multimodal large language models developed by Google DeepMind, first announced on December 6, 2023, that can reason across text, images, audio, video, and code within a single…Mentioned 14 times above
- OpenAIOpenAI is an American artificial intelligence research and deployment organization.Mentioned 13 times above
- Mixture of Experts (MoE)A mixture of experts (MoE) is a machine-learning architecture that contains multiple component functions called experts and a gating or routing mechanism that determines how their outputs contribute to a…Mentioned 9 times above
- Switch TransformerThe Switch Transformer is a sparsely activated Mixture of Experts (MoE) Transformer architecture introduced by William Fedus, Barret Zoph, and Noam Shazeer at Google in January 2021.Mentioned 9 times above
- PaLMPaLM (Pathways Language Model) is a family of dense, decoder-only large language models developed by Google Research. Google announced the original family on April 4, 2022.Mentioned 7 times above
More from See also
- Transformers
- Attention Is All You Need
- T5 (language model)
- Gemini 2.5 Pro
- Gemini 3
- Google Brain
- Google DeepMind
- LaMDA
- Ashish Vaswani
- Aidan Gomez
- daniel de freitas
Topics:AI ResearchGooglePeople
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14"Noam Shazeer", Wikipedia. en.wikipedia.org/...Noam_Shazeer
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Shazeer, N., Mirhoseini, A., Maziarz, K., Davis, A., Le, Q., Hinton, G., Dean, J., "Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer", arXiv:1701.06538, 23 January 2017. arxiv.org/...1701.06538
- ^1 ^2 ^3 ^4 ^5 ^6Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, Ł., Polosukhin, I., "Attention Is All You Need", arXiv:1706.03762, 12 June 2017. arxiv.org/...1706.03762
- ^1 ^2 ^3M. Kruppa and S. Schechner, *The Wall Street Journal*, March 2023 (wsj.com/...hatbot-bard-chatgpt-rival-bing-a4c2d2ad), summarized in Interesting Engineering. interestingengineering.com/...pt-like-ai-years-ago
- ^1 ^2 ^3 ^4 ^5 ^6I. Mehta, "Character.AI CEO Noam Shazeer returns to Google", *TechCrunch*, 2 August 2024. techcrunch.com/...o-noam-shazeer-returns-to-google
- ^1 ^2 ^3Google and Character.AI joint announcement, reported in *TechCrunch*, 2 August 2024. techcrunch.com/...o-noam-shazeer-returns-to-google
- ^1 ^2"Google Confirms $2.7 Billion Deal to Hire Character Co-Founders", *The Information*. theinformation.com/...o-hire-character-co-founders
- ^1 ^2 ^3"Google's $2.7B AI deal with Noam Shazeer's Character.AI draws DOJ attention", Calcalist (Ctech). calcalistech.com/...sy06wllflg
- ^1 ^2 ^3"Noam Shazeer: The 100 Most Influential People in AI 2023", *Time*. time.com/...noam-shazeer
- ^1 ^2 ^3"National Academy of Engineering Elects 130 Members and 28 International Members" (Class of 2026), National Academy of Engineering. nae.edu/...NAENewClass2026
- ^1 ^2E. Woo, "Memo: Noam Shazeer, the ex-CEO of Character.AI who rejoined Google this month, will be Gemini's co-technical lead, working alongside Jeff Dean and Oriol Vinyals", *The Information*, summarized on Techmeme, 22 August 2024. techmeme.com/...p33
- ^1 ^2"Individual results, IMO 1994", International Mathematical Olympiad. imo-official.org/...1994
- "Noam Shazeer", Google Wiki (Fandom), summarizing Duke Putnam record. google.fandom.com/...Noam_Shazeer
- ^1 ^2"Noam Shazeer: After 20 years at Google, he walked away, then came back for $2.7 billion", *Gulf News*. gulfnews.com/...ack-for-27-billion-1.1734670875849
- ^1 ^2 ^3 ^4"Attention Is All You Need", Wikipedia (author credits and contribution footnote). en.wikipedia.org/...Attention_Is_All_You_Need
- ^1 ^2 ^3Shazeer, N., Cheng, Y., Parmar, N., Tran, D., Vaswani, A., Koanantakool, P., Hawkins, P., Lee, H., Hong, M., Young, C., Sepassi, R., Hechtman, B., "Mesh-TensorFlow: Deep Learning for Supercomputers", arXiv:1811.02084, NeurIPS 2018. arxiv.org/...1811.02084
- ^1 ^2 ^3Shazeer, N., Stern, M., "Adafactor: Adaptive Learning Rates with Sublinear Memory Cost", arXiv:1804.04235, ICML 2018. arxiv.org/...1804.04235
- ^1 ^2 ^3Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., Liu, P. J., "Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer", arXiv:1910.10683, JMLR 2020. arxiv.org/...1910.10683
- ^1 ^2 ^3 ^4Shazeer, N., "Fast Transformer Decoding: One Write-Head Is All You Need", arXiv:1911.02150, 6 November 2019. arxiv.org/...1911.02150
- ^1 ^2 ^3 ^4Shazeer, N., "GLU Variants Improve Transformer", arXiv:2002.05202, 12 February 2020. arxiv.org/...2002.05202
- ^1 ^2 ^3 ^4Fedus, W., Zoph, B., Shazeer, N., "Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity", arXiv:2101.03961; *Journal of Machine Learning Research* 23 (2022). arxiv.org/...2101.03961
- ^1 ^2 ^3Chowdhery, A. et al., "PaLM: Scaling Language Modeling with Pathways", arXiv:2204.02311, 5 April 2022. arxiv.org/...2204.02311
- ^1 ^2Google AI Blog, "LaMDA: our breakthrough conversation technology". blog.google/...lamda
- ^1 ^2 ^3 ^4 ^5"Character.ai", Wikipedia. en.wikipedia.org/...Character.ai
- ^"Personalized Superintelligence Platform Character.AI Secures $150M in Series A Funding Led by Andreessen Horowitz", BusinessWire, 23 March 2023. businesswire.com/...ing-Led-by-Andreessen-Horowitz
- ^J. Vanian, "Ex-Google employees' A.I. chatbot startup valued at $1 billion after Andreessen Horowitz funding", *CNBC*, 23 March 2023. cnbc.com/...lion-after-150-million-round-from-a16z
- ^"Google Reportedly Spent $2.7 Billion to Rehire Character.AI Founder", PYMNTS. pymnts.com/...llion-to-rehire-character-ai-founder
- "Gemini 2.5: Pushing the Frontier with Advanced Reasoning, Multimodality, Long-Context", Google DeepMind technical report. storage.googleapis.com/...gemini_v2_5_report.pdf
- ^1 ^2B. Slawski, "Google's Second Most Important Algorithm? Before Google's Panda, there was Phil", SEO by the Sea, summarizing Levy, S., *In the Plex: How Google Thinks, Works, and Shapes Our Lives* (Simon & Schuster, 2011). seobythesea.com/...re-googles-panda-there-was-phil
- ^1 ^2 ^3 ^4 ^5 ^6D. Patel, "Jeff Dean & Noam Shazeer: 25 years at Google: from PageRank to AGI", *Dwarkesh Podcast*, 12 February 2025. dwarkesh.com/...jeff-dean-and-noam-shazeer
- ^1 ^2 ^3 ^4 ^5 ^6"Google Gemini co-lead Noam Shazeer leaves for OpenAI", *CNBC*, 18 June 2026. cnbc.com/...co-lead-noam-shazeer-leaves-for-openai
- ^1 ^2"Two years after a $2.7 billion return to Google, AI pioneer Noam Shazeer is leaving for OpenAI", Calcalist (CTech), 18 June 2026. calcalistech.com/...r1je3bzzze
- ^S. Jindal, "OpenAI poaches Transformer pioneer Noam Shazeer from Google", *Analytics India Magazine*, 18 June 2026. analyticsindiamag.com/...-noam-shazeer-from-google
- ^1 ^2 ^3"Star Google Researcher Joins OpenAI in Coup for ChatGPT Creator", *Bloomberg* (via Bloomberg Law), 18 June 2026. news.bloomberglaw.com/...penai-in-coup-for-startup
- ^Adiwardana, D. et al., "Towards a Human-like Open-Domain Chatbot", arXiv:2001.09977, 27 January 2020. arxiv.org/...2001.09977
- ^Thoppilan, R., De Freitas, D., Hall, J., Shazeer, N. et al., "LaMDA: Language Models for Dialog Applications", arXiv:2201.08239, 20 January 2022. arxiv.org/...2201.08239
- ^1 ^2"Winners of the 1994 Putnam Competition" (55th William Lowell Putnam Mathematical Competition results). people.csail.mit.edu/...putnam1994
- ^1 ^2"William Lowell Putnam Mathematical Competition" (team results and Putnam Fellows), Wikipedia. en.wikipedia.org/...utnam_Mathematical_Competition
- ^"Character.AI files for bankruptcy weeks after Disney hired its former CEO", *Gizmodo*, 13 October 2026. gizmodo.com/...ney-hired-its-former-ceo-2000825281
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
11 revisions by 1 contributor · v11 · 4,278 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (130 claims, 46 sources fetched); 5 material + 29 minor fixed
Cite this page: AI Wiki. "Noam Shazeer." aiwiki.ai, updated 22 Jun 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/noam_shazeer