

DeepSeek-Coder
DeepSeek-Coder is a family of open-weight code large language models built for code generation, completion, and infilling, developed by the Chinese AI lab DeepSeek (DeepSeek-AI). The first generation, released on 2 November 2023, shipped dense models at 1.3B, 5.7B, 6.7B, and 33B parameters that were trained from scratch on roughly 2 trillion tokens (about 87% source code) with a 16K context window, repository-level training, and a fill-in-the-middle objective.[1][6] The 2024 successor, DeepSeek-Coder-V2, is a Mixture-of-Experts model released at 16B and 236B that expands programming-language support to 338 languages, extends the context window to 128K, and reaches performance comparable to GPT-4 Turbo on coding benchmarks, scoring 90.2% pass@1 on HumanEval.[2][3] Across its public benchmarks, DeepSeek-Coder repeatedly produced the strongest open-weight numbers of its time on HumanEval, MBPP, and LiveCodeBench, in several cases approaching or matching the proprietary frontier (GPT-4 Turbo, Claude 3 Opus, Gemini 1.5 Pro).[2][3] The weights are distributed under a permissive custom DeepSeek License that allows commercial use, with the accompanying code under the MIT License.[4][5]
The original paper frames the project plainly: DeepSeek-Coder is "trained from scratch on 2 trillion tokens" and is "pre-trained on a high-quality project-level code corpus and employ[s] a fill-in-the-blank task with a 16K window," a recipe the authors say lets the family "achieve state-of-the-art performance among open-source code models across multiple benchmarks" and even "surpass existing closed-source models like Codex and GPT-3.5."[1]
Infobox
| Field | Value |
|---|---|
| Developer | DeepSeek-AI (and Peking University collaborators) |
| First release | 2 November 2023 (V1)[6] |
| Major successor | DeepSeek-Coder-V2, 17 June 2024[7] |
| V1 sizes | 1.3B, 5.7B, 6.7B, 33B (Base and Instruct)[1][5] |
| V2 sizes | 16B Lite (2.4B active), 236B (21B active)[2][3] |
| V1 pretraining | 2T tokens, 87% code, 13% natural language[1] |
| V2 additional pretraining | 6T tokens on top of DeepSeek-V2 checkpoint[2] |
| Programming languages | 87 (V1), 338 (V2)[1][2] |
| Context window | 16K (V1), 128K (V2)[1][2] |
| Architecture | Dense decoder Transformer (V1); DeepSeekMoE with MLA (V2)[1][2] |
| Primary paper (V1) | arXiv:2401.14196, 25 January 2024[1] |
| Primary paper (V2) | arXiv:2406.11931, 17 June 2024[2] |
| Code license | MIT[4] |
| Model license | DeepSeek License (commercial use permitted)[5] |
What is DeepSeek-Coder?
DeepSeek-Coder is a family of open-weight code language models developed by DeepSeek (DeepSeek-AI), the Hangzhou-based laboratory affiliated with the hedge fund High-Flyer. The family spans three generations: the original DeepSeek-Coder V1 (1.3B, 6.7B, and 33B dense models trained from scratch on two trillion tokens), DeepSeek-Coder-V2 (a Mixture-of-Experts model released in two sizes, 16B Lite and 236B, supporting 338 programming languages and 128K context), and the subsequent absorption of code capability into the unified flagship checkpoints DeepSeek-V2.5 and DeepSeek V3, followed by general models through DeepSeek V4 (2026) with no separate Coder release as of November 2026.[1][2][3][10] It occupies the open-weight code niche alongside Code Llama, StarCoder, and Codestral: a downloadable base for code completion, repository-level infilling, programmer chat, and downstream fine-tuning into coding agents.[1][2]
When was DeepSeek-Coder released, and what is its release history?
DeepSeek-AI released its first code-specialised models in November 2023, a few weeks before its first general chat models, DeepSeek LLM 7B and 67B. The initial DeepSeek-Coder family was made public on 2 November 2023, predating the accompanying arXiv preprint by nearly three months.[6][8] The technical report "DeepSeek-Coder: When the Large Language Model Meets Programming, The Rise of Code Intelligence" was submitted to arXiv on 25 January 2024 (revised on 26 January 2024) by Daya Guo, Qihao Zhu, Dejian Yang and collaborators from DeepSeek-AI and the Key Lab of HCST at Peking University.[1]
DeepSeek positioned the first release as an attempt to close the gap between open-source code models, then anchored by Meta's Code Llama and BigCode's StarCoder, and proprietary systems such as OpenAI's Codex and GPT-3.5.[1] The paper reported that the 33B instruction-tuned variant outperformed GPT-3.5-Turbo on HumanEval and matched it on MBPP, and that the 6.7B base model already exceeded CodeLlama-34B on multilingual HumanEval.[1][6]
DeepSeek-Coder-V2, with the subtitle "Breaking the Barrier of Closed-Source Models in Code Intelligence", was released and posted to arXiv on 17 June 2024.[2][7] Unlike V1, which was trained from scratch, V2 began from an intermediate checkpoint of the broader DeepSeek-V2 base model and added six trillion additional tokens of code- and math-rich data. The release also re-platformed the family onto a Mixture-of-Experts backbone using DeepSeekMoE and Multi-head Latent Attention (MLA) introduced in DeepSeek-V2.[2][9]
A subsequent checkpoint, DeepSeek-Coder-V2-Instruct-0724, replaced the original V2 on the DeepSeek API platform in late July 2024, and the official deepseek-coder endpoint was thereafter routed to the unified DeepSeek-V2.5 model released on 5 September 2024.[10] V2.5 explicitly merged DeepSeek-V2-0628 (chat) with DeepSeek-Coder-V2-0724 (code), and the subsequent flagship DeepSeek V3 (released 26 December 2024) absorbed code capabilities into a single 671B-parameter / 37B-active MoE checkpoint that no longer ships as a separate "Coder" branch.[10][11]
How was DeepSeek-Coder trained?
DeepSeek-Coder V1 pretraining
The V1 corpus totalled roughly 2 trillion tokens. The composition was 87% source code, 10% English code-related natural language (GitHub Markdown and StackExchange), and 3% Chinese natural language.[1] After filtering, the raw code dataset contained approximately 798 GB and 603 million files spanning 87 programming languages.[6]
The data pipeline applied repository-level deduplication. Rather than removing duplicate files independently, files within a GitHub repository were concatenated and near-deduplication was run over whole-project samples, preserving cross-file dependency structure that DeepSeek's authors found important for project-level reasoning.[1][6] Files were then ordered using a topological sort over their import dependencies before sequence packing, producing project-coherent training documents.
DeepSeek-Coder V1 was trained with a 16K context window. Pretraining used the standard causal language modelling loss together with a Fill-in-the-Middle (FIM) objective at the document level, applied at a 50% rate in Prefix-Suffix-Middle (PSM) mode.[1] The FIM ratio of 0.5 was chosen as a compromise between vanilla left-to-right loss and high-FIM regimes that improve infilling but slightly hurt completion quality.[1]
Instruction tuning produced the -Instruct variants. The instruction set used Alpaca-style formatting on roughly 2 billion tokens of curated demonstrations, including code explanation, code completion, and software engineering tasks.[1][5]
DeepSeek-Coder-V2 architecture and training
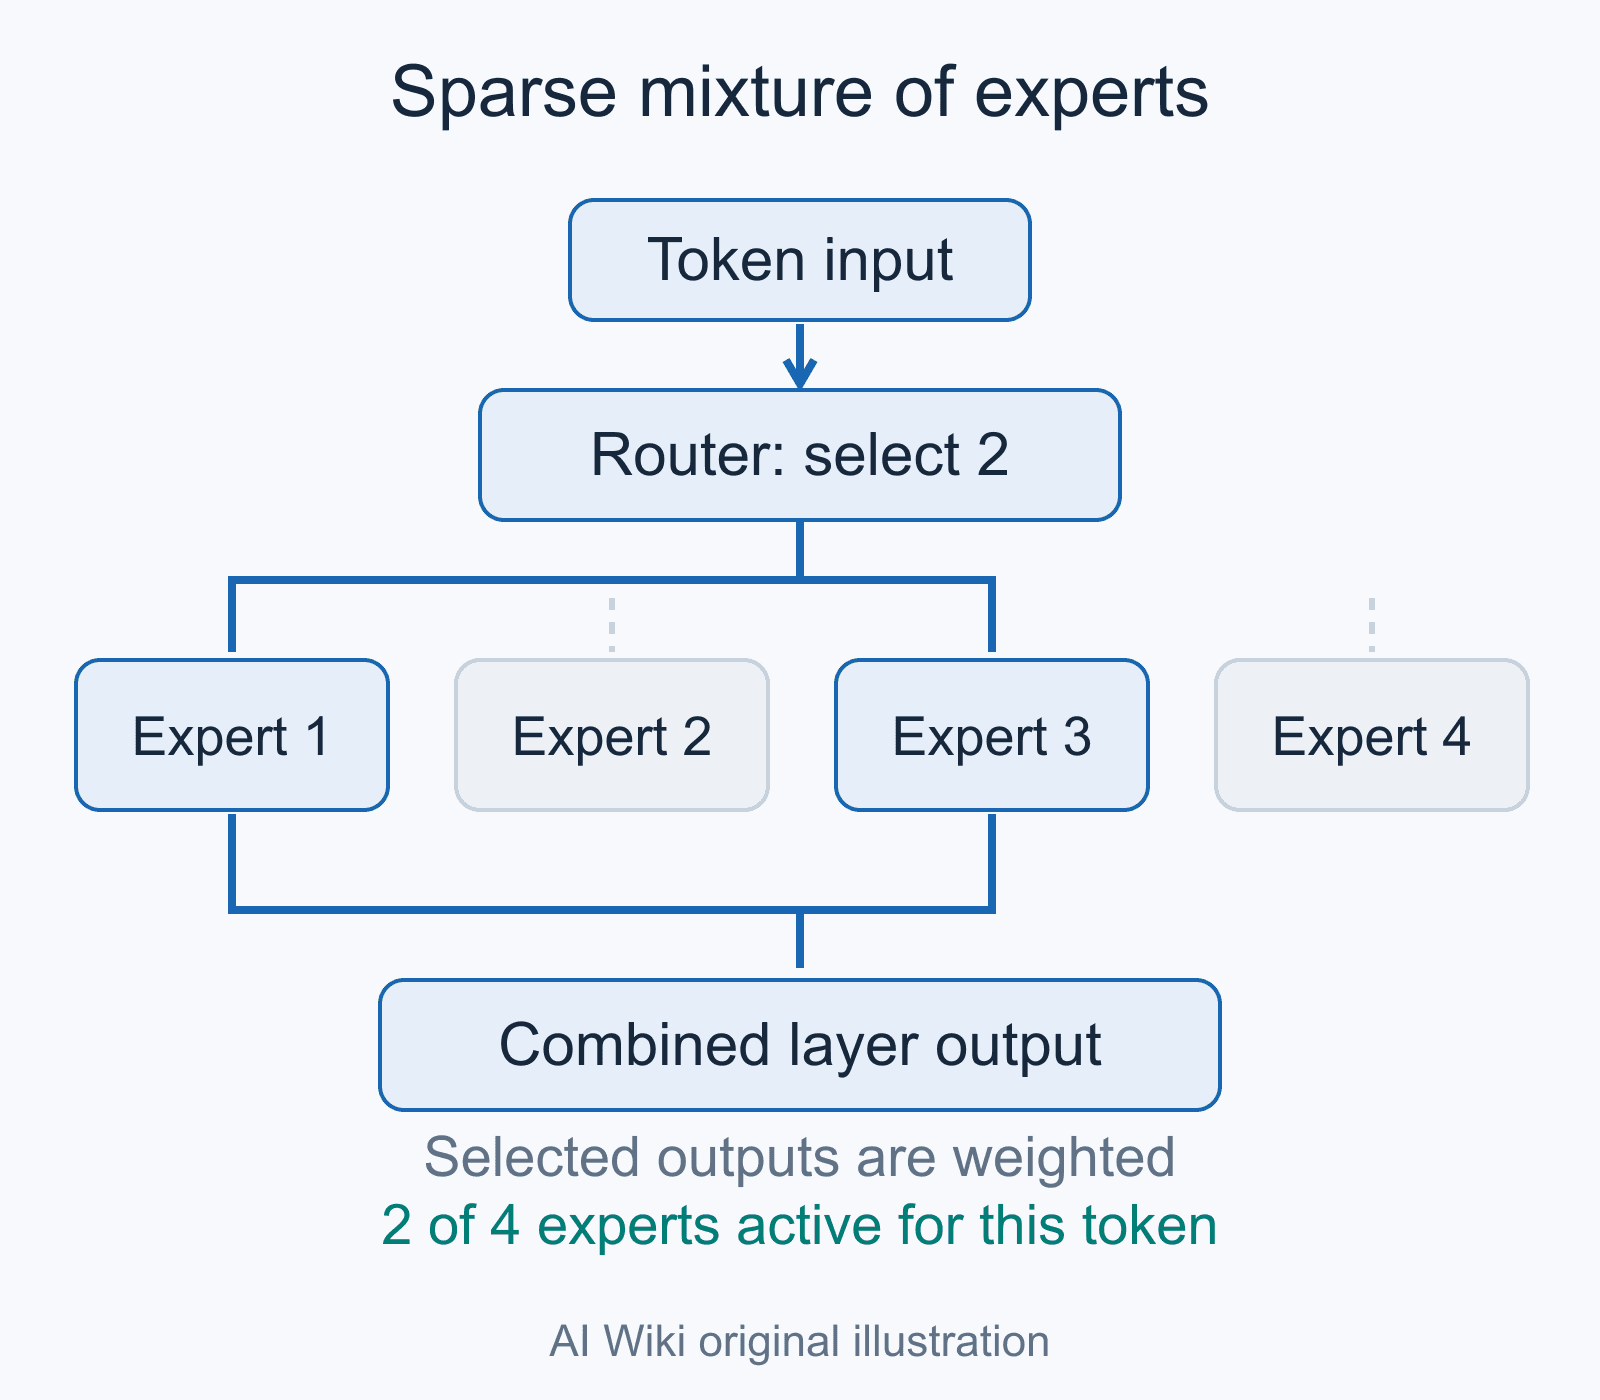
V2 inherited the DeepSeekMoE architecture from DeepSeek-V2, replacing the dense transformer of V1 with a Mixture-of-Experts decoder.[2][9] Two sizes were released:
| Variant | Total parameters | Active parameters per token | Context |
|---|---|---|---|
| DeepSeek-Coder-V2-Lite | 16B | 2.4B | 128K |
| DeepSeek-Coder-V2 | 236B | 21B | 128K |
Both variants used Multi-head Latent Attention (MLA) for KV-cache compression and a fine-grained expert layout with shared and routed experts.[2][9] Continued pretraining added 6 trillion tokens to the DeepSeek-V2 base, with the new corpus weighted toward code and mathematics; the documented mix was 60% code, 10% mathematics, and 30% natural language tokens.[2] Programming-language coverage expanded from the original 86 to 338 languages, and the context window was extended from 16K to 128K with YaRN, a Rotary position embedding (RoPE) extension method.[2] As the V2 abstract puts it, the model "expands its support for programming languages from 86 to 338, while extending the context length from 16K to 128K."[2]
Alignment combined supervised fine-tuning with reinforcement learning. The reinforcement-learning stage used GRPO (Group Relative Policy Optimization), the critic-free policy-gradient variant introduced earlier in DeepSeek's mathematical reasoning work; for code, the authors trained a reward model on compiler and test-case feedback and used its signal in place of raw pass/fail results, which they found noisier.[2][12]
Comparison of V1 and V2
| Property | V1 (Jan 2024) | V2 (Jun 2024) |
|---|---|---|
| Architecture | Dense Transformer | DeepSeekMoE with MLA |
| Sizes | 1.3B, 6.7B, 33B | 16B (2.4B active), 236B (21B active) |
| Pretraining tokens | 2T from scratch | DeepSeek-V2 base + 6T |
| Languages | 86-87 | 338 |
| Context | 16K | 128K |
| FIM | PSM (50% rate) | PSM (50% rate) for 16B Lite; not used for 236B |
| RL stage | None reported | GRPO |
| Paper | arXiv:2401.14196 | arXiv:2406.11931 |
All figures from the respective technical reports.[1][2]
What is DeepSeek-Coder-V2?
DeepSeek-Coder-V2 is the open-source Mixture-of-Experts successor to the original DeepSeek-Coder, released on 17 June 2024. Its abstract states the headline claim directly: "We present DeepSeek-Coder-V2, an open-source Mixture-of-Experts (MoE) code language model that achieves performance comparable to GPT4-Turbo in code-specific tasks."[2] It was "further pre-trained from an intermediate checkpoint of DeepSeek-V2 with additional 6 trillion tokens," and in standard benchmarks "achieves superior performance compared to closed-source models such as GPT4-Turbo, Claude 3 Opus, and Gemini 1.5 Pro in coding and math benchmarks."[2] V2 ships in two sizes, a 16B Lite model with 2.4B active parameters and a 236B flagship with 21B active parameters, both with a 128K context window and support for 338 programming languages.[2][3]
How does DeepSeek-Coder perform on benchmarks?
DeepSeek-Coder V1
The V1 paper reported pass@1 scores for the Base and Instruct variants on standard code benchmarks. Selected numbers:[1][6]
| Model | HumanEval (Py) | MBPP | DS-1000 |
|---|---|---|---|
| DeepSeek-Coder-Base-1.3B | 34.8 | 46.2 | (not reported) |
| DeepSeek-Coder-Base-6.7B | 49.4 | 60.6 | (not reported) |
| DeepSeek-Coder-Base-33B | 56.1 | 66.0 | 40.2 |
| DeepSeek-Coder-Instruct-1.3B | 65.2 | 49.4 | (not reported) |
| DeepSeek-Coder-Instruct-6.7B | 78.6 | 65.4 | (not reported) |
| DeepSeek-Coder-Instruct-33B | 79.3 | 70.0 | (not reported) |
The 33B base model exceeded Code Llama 34B by 7.9 points on HumanEval (Python), 9.3 on multilingual HumanEval, 10.8 on MBPP and 5.9 on DS-1000 in the paper's tabulations.[1][6] Crucially, the 6.7B base model already matched or surpassed CodeLlama-34B on HumanEval, foreshadowing the parameter-efficiency claims the lab would extend in V2.[1]
DeepSeek-Coder-V2
The V2 release re-introduced the 236B MoE model and the 16B Lite model. Selected pass@1 numbers from the paper and the GitHub README:[2][3]
| Benchmark | DeepSeek-Coder-V2-Instruct (236B) | GPT-4o-0513 (proprietary) |
|---|---|---|
| HumanEval | 90.2 | 91.0 |
| MBPP+ | 76.2 | 73.5 |
| LiveCodeBench | 43.4 | 43.4 |
| MATH | 75.7 | 76.6 |
| SWE-bench (as evaluated in the paper) | 12.7 | 26.7 |
The paper reports that DeepSeek-Coder-V2 was the first open-source model to exceed 10 percent on SWE-bench, though its 12.7 percent remained well below GPT-4o's 26.7 percent.[2] On a like-for-like basis the 236B Instruct model's 90.2 HumanEval pass@1 lands essentially level with GPT-4 Turbo, the comparison DeepSeek emphasised in the abstract.[2][3] The V2.5 merge then nudged HumanEval to roughly 89% and the LiveCodeBench score from 39.7 to 41.8 on subsequent evaluation windows.[10]
BigCodeBench was evaluated separately by community leaderboards; DeepSeek-Coder-V2-Instruct was among the top open models at its launch, which placed it in the second tier behind GPT-4o.[23]
What variants and Hugging Face artifacts exist?
The official Hugging Face hub under the deepseek-ai/ namespace hosts the full V1 ladder (deepseek-coder-1.3b-base, -1.3b-instruct, -5.7bmqa-base, -6.7b-base, -6.7b-instruct, -33b-base, -33b-instruct) and the V2 family (DeepSeek-Coder-V2-Lite-Base, -Lite-Instruct, DeepSeek-Coder-V2-Base, DeepSeek-Coder-V2-Instruct, plus the dated -0724 checkpoint).[5][7][13] The 5.7B "MQA" variant is a base model that uses multi-query attention and was published alongside the other V1 sizes.[5][6]
Downstream, the V1 6.7B and 33B Instruct variants accumulated hundreds of tagged derivative fine-tunes, adapters, quantizations (GGUF, AWQ, GPTQ, EXL2) and merges on Hugging Face.[5][13]
Is DeepSeek-Coder open source, and how is it licensed?
The DeepSeek-Coder repositories ship under a dual-license model: the source code (training, evaluation, and inference scripts) under the MIT License, and the model weights under a custom DeepSeek License Agreement (Version 1.0, 23 October 2023).[4][14] The DeepSeek License grants a perpetual, worldwide, royalty-free copyright license including the right to host the model behind an API, distribute derivative weights, and charge fees, subject to use-based restrictions covering military use, harm to minors, harmful disinformation, harassment, illegal discrimination, and a handful of analogous categories drawn from the OpenRAIL family of model licenses.[14] Compared to Meta's Llama community license, the DeepSeek License imposes no monthly active user threshold, but redistributors must pass on its use-based restrictions as an enforceable provision; the preamble says it took inspiration from permissive open source licenses, though the use-based restrictions distinguish it from OSI-approved open source licensing in the strict sense.[14][15]
DeepSeek-Coder-V2 retained the same dual-license structure, with an identical LICENSE-MODEL text.[3][4]
What is DeepSeek-Coder used for, and why does it matter?
DeepSeek-Coder occupies the same niche as Code Llama, StarCoder, Codestral and Qwen3-Coder: an open-weight base for code completion, repository-level infilling, programmer chat, and downstream fine-tuning into coding agents.[1][2][16] The combination of FIM training, a 16K (later 128K) context, and a permissive commercial license made V1 a popular base for company-internal copilots and self-hosted code assistants in 2024, particularly among teams unwilling to send proprietary source to OpenAI or Anthropic.[1][5] The V2-Lite 16B Mixture-of-Experts (with 2.4B active) became a frequently quantised target for desktop deployment, since its active-parameter footprint fits within consumer GPUs while its 128K context supports whole-file edits.[2][3]
Beyond direct use, DeepSeek-Coder served as a research benchmark in its own right. Papers proposing new code agents, fill-in-the-middle objectives, or repository-level reasoning routinely cite DeepSeek-Coder as the open baseline, and the V2 architecture's combination of MoE plus MLA influenced subsequent open releases.[2][9]
The V2 release was the proximate motivation for DeepSeek-AI's later positioning as a credible peer of US frontier labs. When DeepSeek-R1 reasoning models were released in 2025, the lab built on the GRPO algorithm first published in the DeepSeekMath paper and also used to align DeepSeek-Coder-V2.[2][12][17]
What are the limitations of DeepSeek-Coder?
Later work identified several limitations. Coverage of niche or low-resource languages was thinner than that of StarCoder, whose 619-language Stack v2 corpus included many languages absent from DeepSeek's 87-language list.[16] On low-resource languages such as D, Julia, Lua and Perl, StarCoder2-15B matched or surpassed DeepSeek-Coder-33B in independent evaluations.[16]
V2's SWE-bench result (12.7%) edged Claude 3 Opus (11.7%) but trailed GPT-4-Turbo (18.3%) and GPT-4o (26.7%) by a wide margin, indicating that pure code-completion strength did not translate into agentic, multi-step issue-resolution performance.[2] The model also occasionally regressed on natural-language tasks compared with the underlying DeepSeek-V2 chat checkpoint, motivating the subsequent V2.5 merge.[10]
On benchmark interpretation, observers have noted that HumanEval scores above ~90% are saturated and no longer distinguish frontier models; LiveCodeBench (with its rolling fresh problems) and SWE-bench are now the more informative coding signals.[18][19]
A separate practical limitation is the size of the full 236B V2 model. With 21B parameters active per token but 236B in aggregate, hosting requires roughly eight 80GB GPUs in bf16, which is considerably larger than dense 70B models, Codestral 22B or Qwen2.5-Coder-32B.[2][3][20]
How does DeepSeek-Coder compare with contemporaries?
| Model | Released | Params | Open weights | License allows commercial | HumanEval pass@1 (reported) |
|---|---|---|---|---|---|
| Code Llama 34B Instruct | Aug 2023 | 34B dense | Yes | Yes (Llama 2 community) | ~48.2 (base 34B)[1] |
| StarCoder 2 15B | Feb 2024 | 15B dense | Yes | Yes (BigCode OpenRAIL-M) | ~46.3[16] |
| DeepSeek-Coder 33B Instruct | Nov 2023 | 33B dense | Yes | Yes (DeepSeek License) | 79.3[1] |
| DeepSeek-Coder-V2 236B Instruct | Jun 2024 | 236B / 21B active | Yes | Yes (DeepSeek License) | 90.2[2] |
| Codestral 22B | May 2024 | 22B dense | Yes | No (Mistral Non-Production) | ~81.1 (Mistral release notes)[20] |
| Qwen2.5-Coder 32B Instruct | Nov 2024 | 32B dense | Yes | Yes (Apache 2.0) | 92.7[21] |
| GPT-4 / GPT-4-Turbo | 2023-2024 | proprietary | No | N/A | ~85-90 across versions[2] |
| Claude 3 Opus | Mar 2024 | proprietary | No | N/A | 84.9 (reported by V2 paper)[2] |
Three observations follow. First, DeepSeek-Coder-V2 was the first MoE coder to clearly out-score every contemporaneous dense open model on HumanEval and MBPP+ at release, although Qwen2.5-Coder-32B (November 2024) and later Qwen3-Coder variants subsequently closed or reversed that gap on several benchmarks, particularly with smaller models trained on more code tokens.[2][21] Second, Codestral's "non-production" license made DeepSeek-Coder the obvious commercial-friendly choice for self-hosted production deployments during mid-2024.[20] Third, on absolute pass@1 numbers, the V2 family was the first open model series to bring GPT-4-class HumanEval results to weights anyone could download.[2][7]
Related work
DeepSeek-Coder sits inside a broader DeepSeek lineage: the general-purpose DeepSeek V3 and DeepSeek V3.1 LLMs, the DeepSeek-R1 reasoning models built on top of DeepSeek-V3, and specialised siblings like DeepSeek Janus (multimodal generation), DeepSeek-VL2 (vision-language), and DeepSeek-OCR.[11][17] The lineage shares a common architectural toolkit (DeepSeekMoE, MLA, GRPO) and a common evaluation philosophy that emphasises open weights, transparent data composition, and aggressive cost-efficiency.[2][9][12]
Adjacent open code-LLM efforts include StarCoder and StarCoder2 from the BigCode collaboration, which trained on The Stack (BigCode dataset), the broader Code Llama family, Codestral and Codestral Mamba from Mistral, the AlphaCode systems from Google DeepMind, and the Qwen3-Coder line from Alibaba.[16][20][22] Many of these systems share design ideas with DeepSeek-Coder, including repository-level corpora, fill-in-the-middle objectives, and Python-centric benchmark suites such as HumanEval, MBPP, LiveCodeBench, and BigCodeBench.[16][21]
Continue reading
- DeepSeekDeepSeek is a Chinese artificial intelligence company based in Hangzhou. It was founded in 2023 by Liang Wenfeng, who had previously co-founded the quantitative investment firm High-Flyer.Mentioned 107 times above
- HumanEvalHumanEval is a benchmark for measuring whether a code-generating large language model can complete short Python functions so that they pass unit tests. It contains 164 hand-written tasks.Mentioned 16 times above
- Mixture of Experts (MoE)A mixture of experts (MoE) is a machine-learning architecture that contains multiple component functions called experts and a gating or routing mechanism that determines how their outputs contribute to a…Mentioned 7 times above
- CodestralCodestral is a family of code-specialized large language models developed by Mistral AI, beginning with Codestral 22B, released on May 29, 2024Mentioned 7 times above
- MBPPMBPP (Mostly Basic Python Problems) is a code generation benchmark of 974 crowd-sourced Python programming tasks designed to be solvable by entry-level programmers, introduced by Jacob Austin, Augustus Odena…Mentioned 7 times above
- Code LlamaCode Llama is a family of open-weight large language models specialized for code generation and understanding, released by Meta AI on August 24, 2023.Mentioned 6 times above
More from See also
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26Guo, Zhu, Yang, Xie, Dong, Zhang, Chen, Bi, Wu, Li, Luo, Xiong, Liang, "DeepSeek-Coder: When the Large Language Model Meets Programming, The Rise of Code Intelligence", arXiv, 2024-01-25. arxiv.org/...2401.14196. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32 ^33 ^34 ^35 ^36 ^37DeepSeek-AI et al., "DeepSeek-Coder-V2: Breaking the Barrier of Closed-Source Models in Code Intelligence", arXiv, 2024-06-17. arxiv.org/...2406.11931. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10deepseek-ai, "DeepSeek-Coder-V2 GitHub repository README", GitHub, 2024-06-17. github.com/...DeepSeek-Coder-V2. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4deepseek-ai, "LICENSE-CODE (MIT License)", DeepSeek-Coder GitHub repository, 2023-11-02. github.com/...LICENSE-CODE. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8deepseek-ai, "deepseek-coder-33b-instruct model card", Hugging Face, 2023-11. huggingface.co/...deepseek-coder-33b-instruct. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9deepseek-ai, "DeepSeek-Coder GitHub repository README (Let the Code Write Itself)", GitHub, 2023-11-02. github.com/...DeepSeek-Coder. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4deepseek-ai, "DeepSeek-Coder-V2-Instruct model card", Hugging Face, 2024-06-17. huggingface.co/...DeepSeek-Coder-V2-Instruct. Accessed 2026-05-21.
- ^DeepSeek-AI, "DeepSeek Coder project page (deepseekcoder.github.io)", GitHub Pages, 2023-11. deepseekcoder.github.io. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5DeepSeek-AI, "DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model", arXiv, 2024-05-07. arxiv.org/...2405.04434. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5DeepSeek, "DeepSeek-V2.5: A New Open-Source Model Combining General and Coding Capabilities", DeepSeek API Documentation news, 2024-09-05. api-docs.deepseek.com/...news0905. Accessed 2026-05-21.
- ^1 ^2DeepSeek-AI, "DeepSeek-V3 Technical Report", arXiv, 2024-12-26. arxiv.org/...2412.19437. Accessed 2026-05-21.
- ^1 ^2 ^3Shao, Wang, Zhu, Xu, Song, Zhang, Wu, Li, Guo, "DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models", arXiv, 2024-02-05. arxiv.org/...2402.03300. Accessed 2026-05-21.
- ^1 ^2deepseek-ai, "deepseek-coder-6.7b-base model card", Hugging Face, 2023-11. huggingface.co/...deepseek-coder-6.7b-base. Accessed 2026-05-21.
- ^1 ^2 ^3deepseek-ai, "LICENSE-MODEL (DeepSeek License Agreement v1.0)", DeepSeek-Coder GitHub repository, 2023-10-23. github.com/...LICENSE-MODEL. Accessed 2026-05-21.
- ^Meta, "Llama 2 Community License Agreement", Meta AI, 2023-07-18. ai.meta.com/...license. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4 ^5 ^6BigCode Project, "StarCoder2 and The Stack v2: The Next Generation", arXiv, 2024-02-29. arxiv.org/...2402.19173. Accessed 2026-05-21.
- ^1 ^2DeepSeek-AI, "DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning", arXiv, 2025-01-22. arxiv.org/...2501.12948. Accessed 2026-05-21.
- ^Jain, Han, Gu, Li, Yan, Zhang, Wang, Solar-Lezama, Sen, Stoica, "LiveCodeBench: Holistic and Contamination Free Evaluation of Large Language Models for Code", arXiv, 2024-03-12. arxiv.org/...2403.07974. Accessed 2026-05-21.
- ^Jimenez, Yang, Wettig, Yao, Pei, Press, Narasimhan, "SWE-bench: Can Language Models Resolve Real-World GitHub Issues?", arXiv, 2023-10-10. arxiv.org/...2310.06770. Accessed 2026-05-21.
- ^1 ^2 ^3 ^4Mistral AI, "Codestral: Hello, World!", Mistral AI Blog, 2024-05-29. mistral.ai/...codestral. Accessed 2026-05-21.
- ^1 ^2 ^3Hui, Yang et al., "Qwen2.5-Coder Technical Report", arXiv, 2024-09-18. arxiv.org/...2409.12186. Accessed 2026-05-21.
- ^Li, Choudhury, Berabi, Cui, Gabriel, Saxena, Sun, Loubet, Yin, Mishra, Allamanis, "StarCoder: may the source be with you!", arXiv, 2023-05-09. arxiv.org/...2305.06161. Accessed 2026-05-21.
- ^Zhuo et al., "BigCodeBench: The Next Generation of HumanEval", Hugging Face Blog, 2024-06-18. huggingface.co/...leaderboard-bigcodebench. Accessed 2026-11-05.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
8 revisions by 1 contributor · v8 · 3,287 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (120 claims, 24 sources fetched); 7 material + 19 minor fixed
Cite this page: AI Wiki. "DeepSeek-Coder." aiwiki.ai, updated 28 Oct 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/deepseek_coder