

AlphaGo Zero
AlphaGo Zero is a Go-playing computer program developed by DeepMind that reached a superhuman level entirely through self-play reinforcement learning, starting from random play with no human game data. It was introduced in the paper "Mastering the game of Go without human knowledge," which DeepMind announced on 18 October 2017 and which was published in the journal Nature (volume 550, pages 354-359) on 19 October 2017.[1][2] Unlike the earlier versions of AlphaGo, which were trained in part on records of games played by human experts, AlphaGo Zero began from random play and learned solely from the rules of Go and the outcomes of games it played against itself, using a single neural network (combining policy and value) guided by Monte Carlo tree search. DeepMind reported that after about three days of training it defeated AlphaGo Lee, the version that had beaten world champion Lee Sedol, by 100 games to 0.[1][2][3] The same self-play approach was generalized weeks later into AlphaZero, which mastered chess, shogi, and Go from a single algorithm.[7]
The Nature paper summarized the result in its abstract: "Starting tabula rasa, our new program AlphaGo Zero achieved superhuman performance, winning 100-0 against the previously published, champion-defeating AlphaGo."[2]
What is AlphaGo Zero?
AlphaGo Zero is the version of DeepMind's AlphaGo program that learned to play Go without any human knowledge beyond the rules of the game. Where the original AlphaGo bootstrapped from a database of human expert games, AlphaGo Zero started from a blank slate (tabula rasa) and improved purely by playing against itself. It used one deep neural network with two outputs, a move-probability (policy) output and a position-evaluation (value) output, paired with Monte Carlo tree search to choose moves. The headline outcome was a 100-0 record against AlphaGo Lee, the configuration that defeated Lee Sedol 4-1 in March 2016.[1][2][3]
The paper lists 17 authors from DeepMind. David Silver, Julian Schrittwieser, and Karen Simonyan are marked as equal contributors, and Demis Hassabis is the last author.[2][6] MIT Technology Review described Silver as "the lead researcher" and reported Hassabis as saying the project involved around 15 people.[3]
Background
The first version of AlphaGo defeated the European champion Fan Hui in October 2015 and then beat Lee Sedol, the winner of 18 international titles, by four games to one in March 2016.[2][4] That system was trained partly by supervised learning on about 30 million moves from human expert play, followed by reinforcement learning from self-play, and it relied on two separate neural networks (a policy network and a value network) together with handcrafted input features and fast random "rollout" simulations.[2][4][5] A later, stronger iteration known as AlphaGo Master won 60 straight online games against top professionals in January 2017 and beat the world number one, Ke Jie, three games to none at the Future of Go Summit in Wuzhen, China, in May 2017, after which DeepMind said that event would be its final match event with AlphaGo.[1][2][14]
AlphaGo Zero was DeepMind's attempt to remove human knowledge from the loop almost entirely. The motivating question, as the team framed it, was whether a program could reach or exceed the strongest versions of AlphaGo using reinforcement learning alone, starting from a blank slate.[1][2][5] In May 2017 DeepMind had said it planned to publish "one final academic paper later this year" detailing the improvements it had made to AlphaGo's algorithms.[14]
How did AlphaGo Zero learn without human data?
AlphaGo Zero was trained tabula rasa, a Latin phrase meaning "blank slate." At the start of training its network weights were random, and it received no examples of human play. As DeepMind described it, "AlphaGo Zero skips this step and learns to play simply by playing games against itself, starting from completely random play."[1] Learning proceeded purely through self-play reinforcement learning: the program played games against itself, used the results to update a single neural network, and then played stronger games with the improved network.[1][2][6]
The procedure works by using the network's predictions to guide a tree search, which in turn produces better moves than the raw network alone. The paper describes the search as "a powerful policy improvement operator." The search results then serve as training targets: the network is trained to match the search's move probabilities and to predict the eventual winner of each game, with a loss that adds a mean-squared error on the value, a cross-entropy on the move probabilities, and L2 weight regularization. Because the search usually selects much stronger moves than the raw network, each cycle yields a stronger player, which generates higher-quality games for the next cycle.[2][6]
Self-play training pipeline
The paper's Methods section describes three components that ran asynchronously in parallel: an optimizer that kept updating the network from recent self-play data, an evaluator that tested each new network, and a self-play worker that generated games with the best network so far.[6]
| Component | What the paper reports |
|---|---|
| Optimizer | Trained on the Google Cloud with TensorFlow, 64 GPU workers and 19 CPU parameter servers; mini-batches of 2,048 positions (32 per worker) sampled from the most recent 500,000 self-play games; a new checkpoint every 1,000 training steps |
| Evaluator | Each checkpoint played 400 games against the current best network, using 1,600 search simulations per move; it replaced the best network only if it won by a margin of more than 55% |
| Self-play | The best network played 25,000 games per iteration, using 1,600 simulations per move (about 0.4 seconds per search); moves in the first 30 moves of each game were sampled in proportion to visit counts for diversity, Dirichlet noise was added at the root for exploration, and clearly lost games were resigned, with the threshold set to keep false positives below 5% |
Source for the table: the paper's Methods section.[6]
What knowledge was built in?
The paper lists the domain knowledge AlphaGo Zero did use. It was given the complete rules of Go and the set of legal moves in each position, and it used Tromp-Taylor scoring during search and self-play (tournament and evaluation games were scored under Chinese rules). Its network treated the board as a 19x19 image, and training exploited the fact that Go's rules do not change under rotation and reflection. The authors wrote that "AlphaGo Zero does not use any form of domain knowledge beyond the points listed above." It had no rollout policy or extra search heuristics, and it did not even exclude moves that fill in its own eyes, a standard heuristic in earlier Go programs.[6]
Training runs and milestones
DeepMind trained two separate instances of AlphaGo Zero. The first, with a 20-block network, ran for about three days. Over that run it generated 4.9 million games of self-play and updated its parameters from 700,000 mini-batches of 2,048 positions. The paper reports that it "outperformed AlphaGo Lee after just 36 hours," whereas AlphaGo Lee had been trained over several months. After 72 hours, DeepMind played it against the exact version of AlphaGo Lee that had beaten Lee Sedol, under the same 2-hour time controls used in Seoul, and AlphaGo Zero won 100 games to 0.[2][6]
The second instance used a larger 40-block network in a training run of about 40 days, generating 29 million self-play games and 3.1 million mini-batch updates.[2][6] DeepMind's announcement plotted this run's learning curve and marked three milestones on it: at 3 days it passed AlphaGo Lee, at 21 days it "reaches the level of AlphaGo Master," and at 40 days it "surpasses all other versions of AlphaGo."[1] The 21-day label comes from that chart. The paper's Figure 6a plots the same 40-day learning curve against AlphaGo Master and AlphaGo Lee, but its text gives no 21-day milestone and reports numbers only for the final 40-day network.[1][2][6]
| Run | Training time | Milestone | Source |
|---|---|---|---|
| 20 blocks | ~36 hours | Outperforms AlphaGo Lee on DeepMind's Elo scale | Nature paper[2] |
| 20 blocks | ~72 hours (4.9M self-play games) | Beats the exact AlphaGo Lee program 100-0 under Seoul match conditions | Nature paper[2] |
| 40 blocks | ~21 days | Reaches the level of AlphaGo Master | DeepMind blog chart[1] |
| 40 blocks | ~40 days (29M self-play games) | Elo 5,185; beats AlphaGo Master 89-11 | Nature paper[2] |
For comparison, the team also trained the same network architecture by supervised learning on human games from the KGS Go server. The supervised network started out stronger and predicted human professional moves more accurately, but the self-play player defeated it within the first 24 hours of training, which the authors read as a sign that "AlphaGo Zero may be learning a strategy that is qualitatively different to human play."[2][6]
What Go knowledge did AlphaGo Zero discover?
The paper traces how AlphaGo Zero's play changed during training. In fast self-play games shown in the paper, at 3 hours it focused "greedily on capturing stones, much like a human beginner"; at 19 hours it showed the fundamentals of life-and-death, influence and territory; and by 70 hours its games were "beautifully balanced," with multiple battles and a complicated ko fight.[6] It picked up concepts including fuseki (opening), tesuji (tactics), life-and-death, ko, yose (endgame), capturing races, sente, shape, influence and territory. Shicho (ladders), one of the first things human beginners learn, were understood only much later in training.[2][6]
The program also discovered standard corner sequences (joseki). At 10 hours its favorite corner move was a weak one; at 47 hours the 3-3 invasion, a joseki also common in human professional play, was its most frequently played sequence; later it discovered and preferred a new variation. The authors concluded that AlphaGo Zero was able to "rediscover much of this Go knowledge, as well as novel strategies that provide new insights into the oldest of games."[6] Hassabis put it to MIT Technology Review this way: "A few days in, it rediscovers known best plays, and in the final days goes beyond those plays to find something even better."[3]
What is the architecture of AlphaGo Zero?
AlphaGo Zero used a single deep neural network rather than the two networks used by earlier versions. As DeepMind put it, "It uses one neural network rather than two. Earlier versions of AlphaGo used a 'policy network' to select the next move to play and a 'value network' to predict the winner of the game from each position."[1] AlphaGo Zero combined these into one network with two output heads, a move-probability head and a position-evaluation head, sharing the same body. The body was a residual (ResNet-style) convolutional tower, built in versions with 20 and 40 residual blocks, and it took as input only the raw board position and the history of stones rather than handcrafted features.[1][2][6]
| Element | Specification in the paper |
|---|---|
| Input | 19x19x17 stack of binary planes: 8 for the current player's stones over the last 8 positions, 8 for the opponent's stones, and 1 for the color to play |
| Residual tower | One convolutional block plus 19 or 39 residual blocks (20 or 40 in total); each block has two 3x3 convolutions of 256 filters with batch normalization, ReLU, and a skip connection |
| Policy head | 1x1 convolution (2 filters), then a fully connected layer giving 362 logits (361 board points plus pass) |
| Value head | 1x1 convolution (1 filter), a 256-unit hidden layer, and a tanh output in the range -1 to 1 |
Source for the table: the paper's Methods section.[6]
The paper also separated the effect of the architecture from the effect of the algorithm. Trained on the same fixed set of AlphaGo Zero self-play games, a residual network improved playing strength by over 600 Elo compared with the 12-layer convolutional network used in AlphaGo Lee, and combining policy and value into one network added around another 600 Elo, even though it slightly lowered move-prediction accuracy.[2][6]
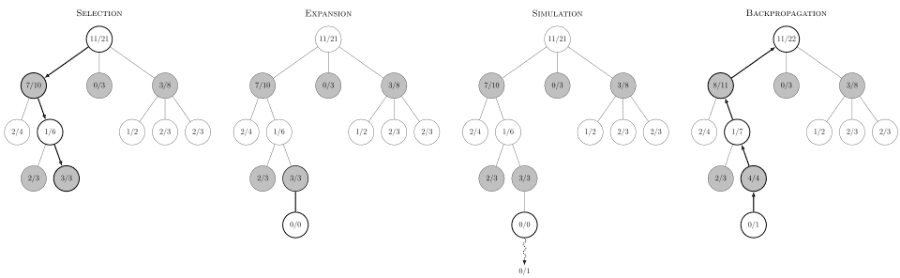
That network was paired with Monte Carlo tree search. During play and self-play, the search used the network to evaluate positions and to bias its exploration toward promising moves, then returned an improved set of move probabilities. A notable simplification compared with earlier versions was that AlphaGo Zero did not use rollouts, the fast, randomized playouts that previous Go programs (including the first AlphaGo) had relied on to estimate the value of a position. Instead it depended entirely on the network's own evaluations.[1][2][6] Martin Mueller, a University of Alberta professor who had worked on Go programs, told MIT Technology Review: "The architecture is simpler, yet more powerful, than previous versions."[3]
Hardware
The often-quoted "4 TPUs" figure refers to the machine that played the games. In the match against AlphaGo Lee, AlphaGo Zero used a single machine with four tensor processing units (TPUs), while AlphaGo Lee was distributed over many machines and used 48 TPUs; in the final evaluation, AlphaGo Fan had used 176 GPUs.[2][6] Training was a different setup: the network was optimized on the Google Cloud with 64 GPU workers and 19 CPU parameter servers, and the paper does not state the hardware used to generate the millions of self-play games.[6] The later AlphaZero preprint repeated the point in a footnote: "The original AlphaGo Zero paper used GPUs to train the neural networks."[7]
How strong was AlphaGo Zero?
DeepMind reported a series of head-to-head results and Elo ratings showing that AlphaGo Zero overtook every earlier version. The most widely cited figure is the 100-0 sweep against AlphaGo Lee by the 3-day, 20-block network. The 40-day, 40-block network then beat AlphaGo Master by 89 games to 11 in a 100-game match with 2-hour time controls.[1][2][3]
| Version | Training data | Hardware (as evaluated) | Elo (Nature paper) | Notable result |
|---|---|---|---|---|
| AlphaGo Fan (2015) | Human games + self-play | 176 GPUs, distributed | 3,144 | Beat Fan Hui 5-0 |
| AlphaGo Lee (2016) | Human games + self-play | 48 TPUs, distributed | 3,739 | Beat Lee Sedol 4-1 |
| AlphaGo Master (2017) | Human games + self-play | Single machine, 4 TPUs | 4,858 | 60-0 online vs top professionals; beat Ke Jie 3-0 |
| AlphaGo Zero, raw network only (40 days) | Self-play only (tabula rasa) | Not stated | 3,055 | Plays the network's top move with no search |
| AlphaGo Zero (3 days, 20 blocks) | Self-play only (tabula rasa) | Single machine, 4 TPUs | Not given | 100-0 vs AlphaGo Lee |
| AlphaGo Zero (40 days, 40 blocks) | Self-play only (tabula rasa) | Single machine, 4 TPUs | 5,185 | 89-11 vs AlphaGo Master |
Sources for the table: the Nature paper and DeepMind's announcement.[1][2][4][6]
The Elo figures come from a tournament in which every program had 5 seconds of thinking time per move, with ratings estimated by the BayesElo program. The ratings of AlphaGo Fan and earlier Go programs were anchored to values published in 2016, and the results of the Fan Hui and Lee Sedol matches were included "to ground the scale to human references, as otherwise the Elo ratings of AlphaGo are unrealistically high due to self-play bias."[6] On this scale a 200-point gap corresponds to a 75% probability of winning.[6]
Why does AlphaGo Zero matter?
AlphaGo Zero was widely covered as evidence that a system could reach superhuman performance in a complex domain through reinforcement learning alone, without bootstrapping from human expertise. "By not using human data or human expertise, we've actually removed the constraints of human knowledge," Silver told MIT Technology Review.[3] DeepMind's announcement suggested that if similar techniques could be applied to other structured problems, "such as protein folding, reducing energy consumption or searching for revolutionary new materials," the results could benefit society.[1]
Commentators noted the limits of the claim. Pedro Domingos of the University of Washington pointed out that the program still needed to play many millions of games to master Go, far more than a human expert, and said: "I wouldn't read too much into it as a sign of what computers can learn without human knowledge."[3] An analysis republished by the University of Queensland's Queensland Brain Institute observed that Go is "a tightly constrained game of perfect information," and that training AlphaGo Zero required accurate simulation of millions of games, whereas for many practical problems such simulation is computationally unfeasible or the rules are less clear.[5]
The result also simplified the recipe established by the original AlphaGo. By folding two networks into one, dropping handcrafted features, and removing rollouts, AlphaGo Zero showed that a cleaner design could outperform a more complex predecessor. That recipe became the basis for open reimplementations outside DeepMind (see below).[2][11][12][13]
How is AlphaGo Zero different from AlphaGo and AlphaZero?
AlphaGo Zero is closely related to, but distinct from, both the original AlphaGo and AlphaZero. The original AlphaGo learned in part from human expert games and used two networks plus rollouts; AlphaGo Zero removed human data, folded the two networks into one, and dropped rollouts, while remaining specialized for Go.[1][2] AlphaGo Master sat in between: according to the paper it used the same network architecture, reinforcement learning algorithm and search as AlphaGo Zero, but kept AlphaGo Lee's handcrafted features and rollouts and was initialized by supervised learning from human data.[6]
On 5 December 2017, DeepMind released a preprint describing AlphaZero, a single algorithm based on the same self-play and search principles that was applied without game-specific modification to chess, shogi, and Go. The preprint reported that AlphaZero reached a superhuman level in each of those games within 24 hours of training and defeated a world-champion program in each: the chess engine Stockfish, the shogi engine Elmo, and the three-day version of AlphaGo Zero, which it beat 60 games to 40 at one minute per move.[7] The peer-reviewed version, published in Science in December 2018, reported longer runs (about 13 days of training in Go), found that AlphaZero first outperformed AlphaGo Lee after 30 hours, and gave its result against the three-day AlphaGo Zero as 61% of games won.[8][10]
| Program | Year | Human data? | Networks | Domain |
|---|---|---|---|---|
| AlphaGo (Fan/Lee) | 2015-2016 | Yes | Two (policy + value), with rollouts | Go |
| AlphaGo Master | 2017 | Yes (initialization) | One (combined), with rollouts and handcrafted features | Go |
| AlphaGo Zero | 2017 | No (tabula rasa) | One (combined policy + value), no rollouts | Go |
| AlphaZero | 2017-2018 | No (tabula rasa) | One (combined policy + value) | Chess, shogi, Go |
| MuZero | 2019-2020 | No | Learned model plus policy and value | Atari, chess, shogi, Go |
The lineage continued with MuZero, first posted as a preprint in November 2019 and published in Nature in December 2020, which extended the approach to settings where the rules of the environment are not given in advance. MuZero learned a model that predicts the reward, policy and value, and it matched AlphaZero's superhuman performance in Go, chess and shogi without being told the rules.[9] Each step in the series removed another piece of built-in knowledge: human games in AlphaGo Zero, game-specific design in AlphaZero, and the rules themselves in MuZero.[2][7][9]
Open reimplementations
Several groups outside DeepMind rebuilt AlphaGo Zero's approach in the open.
| Project | Developer | Description |
|---|---|---|
| Leela Zero | Gian-Carlo Pascutto and contributors | Created on GitHub in October 2017 as "a fairly faithful reimplementation of the system described in the Alpha Go Zero paper," released under GPLv3; its network was trained by a public distributed effort because, its README notes, recomputing the AlphaGo Zero weights would take about 1,700 years on commodity hardware[13] |
| ELF OpenGo | Facebook AI Research (Yuandong Tian et al.) | An open-source reimplementation of AlphaZero for Go, presented at ICML 2019; its authors call it "the first open-source Go AI to convincingly demonstrate superhuman performance," with a 20:0 record against top professionals[12] |
| KataGo | David Wu | Introduced several changes to the AlphaZero process and architecture, reporting a 50-fold reduction in computation compared with similar methods; it surpassed ELF OpenGo's final model after 19 days on fewer than 30 GPUs, whereas ELF had used thousands of GPUs over two weeks[11] |
KataGo's paper calls ELF OpenGo and Leela Zero "replications" of AlphaZero and says that KataGo, like them, "only learns from neural-net-guided Monte Carlo tree search self-play."[11]
ELI5
Imagine a robot that wants to get really good at a board game but is never allowed to watch a single human play. It only knows the rules. So it plays the game against itself, over and over, millions of times. At first it just makes random moves, but every time it finishes a game it learns a little about which moves tend to win. After about three days of practicing against itself, it became so strong that it beat the best game-playing robot from before, which had studied tons of human games, by a perfect score of 100 to 0. That is AlphaGo Zero: it taught itself, from scratch, with no human help.
Continue reading
- AlphaGoAlphaGo is a computer program developed by DeepMind that plays the board game Go, and it was the first program to defeat a human professional Go player on a full 19x19 board without a handicap.Mentioned 93 times above
- Google DeepMindGoogle DeepMind is an artificial intelligence research and model-development organization at Google.Mentioned 22 times above
- AlphaZeroAlphaZero is a general-purpose reinforcement learning algorithm developed by DeepMind that taught itself to play chess, shogi (Japanese chess), and Go at a superhuman level from scratch, using only the rules…Mentioned 13 times above
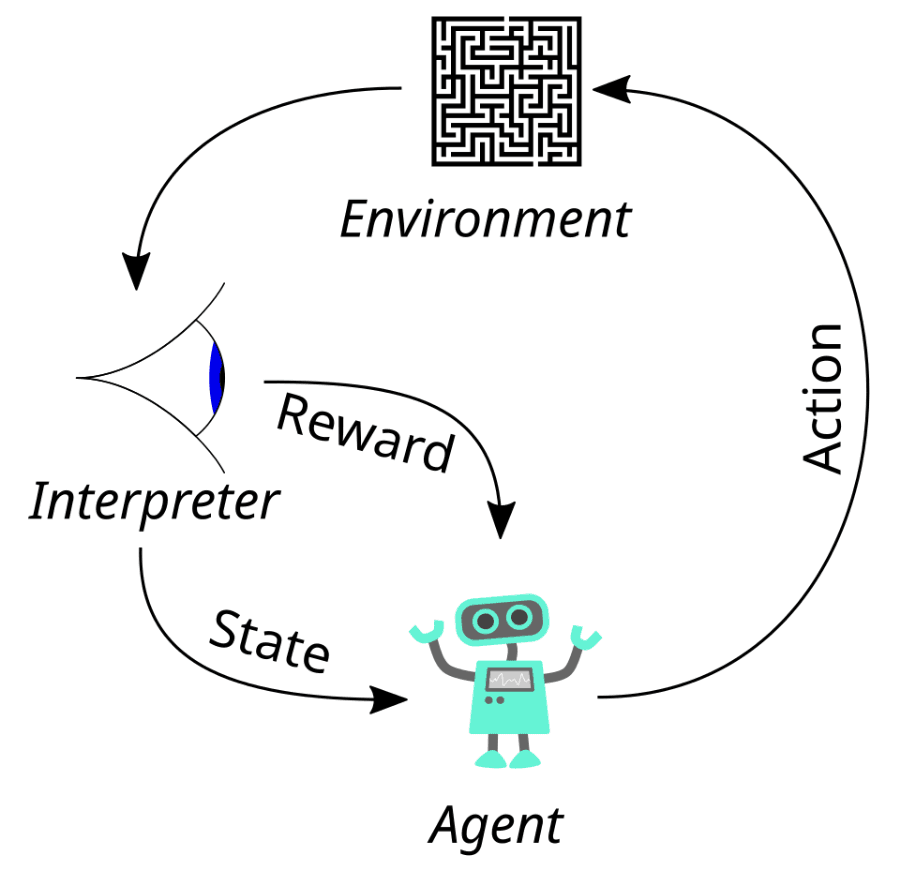
- Reinforcement learningReinforcement learning (RL) is a branch of machine learning in which an agent learns to make decisions by taking actions in an environment to maximize a cumulative reward signal, discovering good behavior…Mentioned 6 times above
- MuZeroMuZero is a model-based reinforcement learning algorithm developed by DeepMind that reached superhuman play in Go, chess, and shogi and set a new state of the art on the 57-game Atari benchmark without being…Mentioned 4 times above
- Monte Carlo Tree SearchMonte Carlo Tree Search (MCTS) is a heuristic search algorithm for sequential decision-making that finds strong actions by running many simulated playthroughs of a problem and aggregating their outcomes into a…Mentioned 4 times above
More from See also
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17Silver, D., and Hassabis, D. "AlphaGo Zero: Starting from scratch." Google DeepMind blog, October 18, 2017. deepmind.google/...hago-zero-starting-from-scratch
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28Silver, D., et al. "Mastering the game of Go without human knowledge." *Nature* 550, 354-359 (2017). nature.com/...nature24270
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Knight, W. "AlphaGo Zero Shows Machines Can Become Superhuman Without Any Help." *MIT Technology Review*, October 18, 2017. technologyreview.com/...uperhuman-without-any-help
- ^1 ^2 ^3Silver, D., et al. "Mastering the game of Go with deep neural networks and tree search." *Nature* 529, 484-489 (2016). nature.com/...nature16961
- ^1 ^2 ^3"Google AlphaGo Zero masters the game in three days." Queensland Brain Institute, University of Queensland, 23 October 2017 (originally published on The Conversation). qbi.uq.edu.au/...hago-zero-masters-game-three-days
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23Silver, D., et al. "Mastering the game of Go without human knowledge" (author manuscript with Methods), UCL Discovery. discovery.ucl.ac.uk/10045895
- ^1 ^2 ^3 ^4Silver, D., et al. "Mastering Chess and Shogi by Self-Play with a General Reinforcement Learning Algorithm." arXiv:1712.01815 (December 5, 2017). arxiv.org/...1712.01815
- ^Silver, D., Hubert, T., Schrittwieser, J., and Hassabis, D. "AlphaZero: Shedding new light on chess, shogi, and Go." Google DeepMind blog, December 6, 2018. deepmind.google/...new-light-on-chess-shogi-and-go
- ^1 ^2Schrittwieser, J., et al. "Mastering Atari, Go, chess and shogi by planning with a learned model." *Nature* 588, 604-609 (2020). nature.com/...s41586-020-03051-4
- ^Silver, D., et al. "A general reinforcement learning algorithm that masters chess, shogi, and Go through self-play." *Science* 362(6419), 1140-1144 (2018). science.org/...science.aar6404
- ^1 ^2 ^3Wu, D. J. "Accelerating Self-Play Learning in Go." arXiv:1902.10565 (2019). arxiv.org/...1902.10565
- ^1 ^2Tian, Y., et al. "ELF OpenGo: An Analysis and Open Reimplementation of AlphaZero." ICML 2019; arXiv:1902.04522. arxiv.org/...1902.04522
- ^1 ^2Leela Zero project. "Leela Zero" (README and source code), GitHub. github.com/...leela-zero
- ^1 ^2Hassabis, D., and Silver, D. "AlphaGo's next move." Google DeepMind blog, May 27, 2017. deepmind.google/...alphagos-next-move
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
7 revisions · v7 · 3,896 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Fact-checked on 2026-10-30 against the 2017 Nature paper and its Methods, DeepMind's announcement and learning-curve chart, contemporaneous reporting, and the papers and repositories of the open reimplementations, with an independent second review.
Cite this page: AI Wiki. "AlphaGo Zero." aiwiki.ai, updated 30 Oct 2026, fact-checked 30 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/alphago_zero