

Mobile ALOHA
Mobile ALOHA is an open-source, low-cost system for collecting bimanual mobile manipulation data and learning household tasks from it, developed at Stanford University by Zipeng Fu, Tony Z. Zhao, and Chelsea Finn and released on 4 January 2024.[1] It mounts two robot arms on a wheeled base and adds a whole-body teleoperation interface, so a human can puppeteer both arms while walking the robot around a room. The complete platform costs roughly $32,000 USD in parts, and with about 50 human demonstrations per task plus co-training on a static ALOHA dataset it can autonomously saute shrimp, call an elevator, open a wall cabinet, and rinse a pan.[1]
Mobile ALOHA was published alongside the arXiv preprint Mobile ALOHA: Learning Bimanual Mobile Manipulation with Low-Cost Whole-Body Teleoperation. It extends the original ALOHA (A Low-cost Open-source HArdware system for bimanual teleoperation) rig with an AgileX Tracer differential-drive base, a waist tether that lets the operator backdrive the base's wheels while both hands puppeteer the leader arms, and a behavior-cloning recipe in which the learned policy uses the ACT (Action Chunking with Transformers) architecture co-trained on a mixture of newly collected mobile data and the static ALOHA dataset released the previous year.[1][2] The paper states the cost directly: "We build Mobile ALOHA with a $32k budget, comparable to a single industrial cobot such as the Franka Emika Panda."[1] That budget covers all four robot arms, the mobile base, batteries, cameras, and an Nvidia RTX 3070 Ti laptop for onboard compute.[1]
The project was widely amplified on social media in January 2024 because of striking video clips that showed the robot performing household chores such as sauteing shrimp, calling an elevator, watering plants, opening a wall cabinet, and rinsing a pan. Some of these clips were autonomous policy rollouts from the paper, while others (in particular several cooking demonstrations widely shared on X/Twitter) were human teleoperated data-collection sessions, a distinction IEEE Spectrum highlighted later that month.[3] The viral wave nonetheless helped popularize low-cost mobile bimanual imitation learning as a research direction, and Trossen Robotics later sold a commercial Aloha Mobile kit, since discontinued.[4]
What is Mobile ALOHA?
Mobile ALOHA is two things at once: a piece of low-cost hardware for collecting whole-body bimanual manipulation data, and a learning recipe that turns a few dozen of those demonstrations into an autonomous policy. The paper's abstract frames the gap it addresses plainly: "most results focus on table-top manipulation, lacking the mobility and dexterity necessary for generally useful tasks."[1] Mobile ALOHA answers that by augmenting the static ALOHA bimanual teleoperation rig "with a mobile base, and a whole-body teleoperation interface," then performing supervised behavior cloning on the collected data.[1]
The headline result, stated in the abstract, is that "with 50 demonstrations for each task, co-training can increase success rates by up to 90%, allowing Mobile ALOHA to autonomously complete complex mobile manipulation tasks such as sauteing and serving a piece of shrimp, opening a two-door wall cabinet to store heavy cooking pots, calling and entering an elevator, and lightly rinsing a used pan using a kitchen faucet."[1] The combination of an accessible price point (around $32,000 versus the roughly $200,000 of prior mobile bimanual research robots) and a simple, reproducible learning method is what made the system influential in robot learning.[1]
Origin and authorship
Mobile ALOHA was developed in the Stanford Interactive Perception and Robot Learning Lab (IRIS), led by assistant professor Chelsea Finn, in collaboration with the broader Stanford AI Lab and the Stanford Robotics Center. The project's two student co-leads, Zipeng Fu and Tony Z. Zhao, had previously contributed to neighboring lines of work: Zhao authored the original ALOHA system and the ACT algorithm in 2023 (Learning Fine-Grained Bimanual Manipulation with Low-Cost Hardware, arXiv:2304.13705), and Fu had worked on legged locomotion and whole-body control. Their goal was to combine the dexterity advantages of the ALOHA teleoperation interface with the reach and household relevance of a mobile platform, without falling into the cost trap of prior mobile manipulator research, which had typically required PR2 or TIAGo-class robots costing on the order of $200,000.[1]
The team released the arXiv preprint, an extensive project page, two GitHub repositories (one for hardware and teleoperation, one for the ACT++ training code), a Google Drive containing several hundred teleoperated episodes, and high-resolution videos of both teleoperation and autonomous rollouts on 4 January 2024. The project drew wide social-media attention and press coverage, including MIT Technology Review on 15 January 2024 and Stanford Report in April 2024.[9][8]
What hardware does Mobile ALOHA use?
Mobile ALOHA keeps the four-arm leader-follower architecture of ALOHA but mounts all four arms, facing forward, on a wheeled chassis instead of a fixed tabletop. The operator is tethered to the base at the waist and moves it by backdriving its wheels while puppeteering the two leader arms; the tether and leader arms can be detached for autonomous runs.[1]
Robot arms
The system uses four Trossen Robotics arms in total: two ViperX 300 followers mounted on the mobile base and two smaller WidowX leaders that the operator holds.[1][6] Each ViperX 300 has six degrees of freedom with a gripper (treated as a seventh actuated joint), uses Dynamixel XM/XH series servos, has a reach of roughly 750 mm and a working payload of about 750 g.[6] The follower arms are mounted at a fixed height, giving a vertical reach of 65 cm to 200 cm above the ground and 100 cm beyond the base; the paper lists that fixed height as a limitation, since it makes lower cabinets, ovens, and dishwashers hard to reach.[1]
Mobile base
The mobile base is the AgileX Tracer AGV, a low-profile differential-drive platform marketed for warehouse logistics. The paper gives the complete robot's footprint as 90 cm by 135 cm and the Tracer's top speed as 1.6 m/s (similar to average human walking speed), with a maximum payload of 100 kg and CAN bus communication with the onboard laptop; the Tracer cost $7,000 in the United States.[1] The paper notes that the Tracer's low height of approximately 17 mm permits placing a heavy lithium battery near the floor, which acts as ballast and significantly improves tip-over stability when the arms apply forces overhead.
Onboard power and compute
A custom-built 1.26 kWh lithium-ion battery weighing approximately 14 kg supplies power to all four arms, the mobile base, cameras, and laptop. The paper describes the teleoperation system as capable of multiple hours of consecutive use. All compute for data collection and inference runs on a consumer-grade laptop with an Intel i7-12800H CPU and an Nvidia RTX 3070 Ti laptop GPU (8 GB VRAM).[1]
Cameras and sensors
Mobile ALOHA carries three Logitech C922x USB RGB webcams: one wrist-mounted on each follower arm and one third-person "top" camera, which faces forward and is mounted between the arms. The cameras record at 480 by 640 resolution at 50 Hz. The robot itself has no LIDAR, depth sensors, force/torque sensors, or tactile skin; localization is purely visual through the three RGB streams, and proprioception comes from the Dynamixel servo encoders and the Tracer's wheel odometry.[1]
Bill of materials
The paper reports the total budget and the price of the mobile base but no itemized bill of materials; the arm prices below come from the original ALOHA paper (2023 prices).
| Component | Description | Approximate cost (USD) |
|---|---|---|
| 2 x ViperX 300 + 2 x WidowX arms | 6-DOF arms with grippers (2 ViperX followers, 2 WidowX leaders) | about $17,800 ($5,600 per ViperX, $3,300 per WidowX)[6] |
| AgileX Tracer mobile base | Differential drive AGV | $7,000[1] |
| Battery, laptop, 3 x Logitech C922x cameras, frame and mounts | Onboard power, compute, sensing, and teleoperation frame | not itemized in the paper |
| Total | approximately $32,000[1] |
The paper compares this budget to the price of a single industrial cobot such as the Franka Emika Panda, against more than $200,000 for off-the-shelf bimanual mobile manipulators such as the PR2 and TIAGo.[1]
How does the whole-body teleoperation interface work?
The teleoperation interface is a direct extension of the leader-follower "puppeteering" scheme introduced in the original ALOHA. The operator stands behind the robot, harnessed to the mobile base at the waist with a rigid tether that is long enough to allow comfortable stepping but short enough that the operator's translation is mechanically coupled to the base. As the paper describes it, "the user is then physically tethered to the system and backdrives the wheels to enable base movement. This allows for independent movement of the base while the user has both hands controlling ALOHA."[1] As the operator walks the rig around the workspace, the wheel encoders of the Tracer record linear and angular velocity, which are stored as part of the demonstration. Simultaneously, the operator grips the two leader arms, and the joint angles of these arms are streamed at 50 Hz to the two follower arms, which mirror the motion in real time. A 3D-printed handle-and-scissor mechanism on each leader arm gives continuous control of the follower gripper.[6]
This design has two notable properties relative to alternatives such as virtual reality controllers, motion capture suits, or haptic exoskeletons. First, it requires no calibration of the operator's body kinematics, no battery-powered controllers, and no external tracking system, which makes data collection portable to arbitrary kitchens, hallways, and offices. Second, because the smaller WidowX leader arms share the ViperX followers' joint layout and are mapped to them joint for joint, the operator's commanded joint trajectory is automatically feasible on the follower, eliminating the kinematic re-targeting problems that affect VR teleoperation of robots with different morphology.
The paper reports a user study with eight participants in which task completion time decreased by 39 to 52 percent within the first five trials of practice, suggesting the interface has a relatively short learning curve. The paper describes the teleoperation system as capable of multiple hours of consecutive use, for example cooking a three-course meal, cleaning a public bathroom, or doing laundry.[1]
How does Mobile ALOHA learn tasks?
The policy that runs autonomously on the robot is trained with Action Chunking with Transformers (ACT), the same algorithm used by the original ALOHA, lightly extended to predict the base velocity along with the joint positions. The training recipe also incorporates a co-training step with the static ALOHA dataset, which is the paper's principal algorithmic finding. The whole pipeline is supervised imitation learning (behavior cloning): there is no reward function, no reinforcement learning, and no simulation in the loop for the real-world tasks.
ACT (Action Chunking with Transformers)
ACT was introduced by Tony Z. Zhao and colleagues in April 2023 in the paper Learning Fine-Grained Bimanual Manipulation with Low-Cost Hardware (arXiv:2304.13705).[6] At a high level, ACT is a conditional variational autoencoder over short chunks of future actions rather than over individual actions. During training, a transformer encoder compresses the current joint positions and the target action sequence into a latent style variable z; this encoder is discarded at test time, when z is set to zero. The decoder, which is the policy, takes z, the camera images, and the joint positions and predicts the next k actions (the chunk). In the original ACT the policy is queried at every timestep, and the overlapping chunk predictions are combined with an exponentially weighted temporal ensemble to produce smooth motion.[6]
Action chunking dramatically reduces compounding error in behavior cloning by amortizing each policy decision over many timesteps, and it allows the policy to commit to multi-step plans (such as the full reach-grasp-lift sequence of a pan handle) without being derailed by short-term noise in the observation stream.
For Mobile ALOHA, the action space is extended from the 14-dimensional joint vector of the original ALOHA (7 DOF per arm, including gripper) to a 16-dimensional vector that adds linear and angular base velocity. The default chunk size is 45 timesteps at 50 Hz (roughly 0.9 seconds of look-ahead), the encoder has 4 transformer layers, the decoder has 7 transformer layers, the hidden dimension is 512, and the learning rate is 2e-5 with the Adam optimizer.[1]
The paper also benchmarks Diffusion Policy (Chi et al., 2023) and VINN (visual nearest neighbor) as alternatives. Diffusion Policy uses a chunk size of 64 with a DDIM scheduler (50 training steps, 10 inference steps) and a learning rate of 1e-4. VINN uses a chunk size of 100 and a weighted nearest-neighbor lookup over state and visual features. In the paper's two-task comparison (Wipe Wine and Push Chairs), ACT performs best; Diffusion Policy matches it on Push Chairs (100 percent with co-training) but reaches 65 percent on Wipe Wine.[1]
Co-training with static ALOHA data
The paper's signature methodological contribution is co-training with a much larger pre-existing static manipulation dataset, specifically the 825-episode, 12-task corpus of static ALOHA data from earlier ALOHA papers, obtained through the RT-X (Open X-Embodiment) release. For each gradient step, with equal probability the training procedure samples either a Mobile ALOHA episode for the target task or a static ALOHA episode from the broader corpus. Because the static episodes do not include base motion, the action vector is zero-padded along the two base velocity dimensions for those samples, which makes the dataset shapes compatible with the same 16-dimensional ACT output head.[1]
The intuition is that the static dataset, despite covering different tasks, is rich in scene diversity and in fine-grained bimanual manipulation primitives. Sharing the encoder and decoder across both datasets prevents the small per-task mobile dataset (often only 20 to 50 episodes) from overfitting, and exposes the policy to a wider distribution of grippers, lighting, and table configurations than a single mobile task would cover.
The paper quantifies the effect precisely: "With co-training, we are able to achieve over 80% success on these tasks with only 50 human demonstrations per task, with an average of 34% absolute improvement compared to no co-training."[1] The peak gain is larger still: the abstract reports that co-training can increase success rates "by up to 90%," and the Call Elevator task improves from 0 percent to 95 percent. The boost is robust to the static-to-mobile sampling ratio anywhere between 30 percent and 70 percent. The authors highlight this as the first published demonstration that static manipulation data can transfer beneficially to a mobile manipulation policy without any explicit domain adaptation.[1]
What tasks can Mobile ALOHA do, and how well?
The paper reports autonomous evaluations on a suite of seven tasks, each with 50 (or in two cases 20) teleoperated demonstrations as the training set. The following table summarizes the autonomous success rates with and without co-training, taken from Table 1 of the paper.
| Task | Demonstrations | ACT with co-training | ACT without co-training |
|---|---|---|---|
| Wipe Wine (clean a wine spill on a table) | 50 | 95% | 50% |
| Call Elevator (press button and enter cabin) | 50 | 95% | 0% |
| Use Cabinet (open two-door cabinet, store pot) | 50 | 85% | 85% |
| High Five (greet a person) | 20 | 85% | 85% |
| Rinse Pan (rinse used pan under faucet) | 50 | 80% | 0% |
| Push Chairs (push in several chairs) | 50 | 80% | 0% |
| Cook Shrimp (saute shrimp in pan) | 20 | 40% | 20% |
Table 1 of the paper reports both conditions for all seven tasks: co-training raises whole-task success on five of them and leaves Use Cabinet and High Five unchanged. The gap is largest for Call Elevator: the policy trained only on its 50 task demonstrations cannot reliably localize the elevator button and never succeeds, while the co-trained policy succeeds in nineteen of twenty trials. The Cook Shrimp task, the one that produced most of the viral video coverage, is also the most difficult: it involves an entire multi-stage cooking workflow (add oil, add the shrimp, flip it with a spatula, and serve it in a bowl) and achieves only 40 percent success over five trials even with co-training, a fact that the paper is explicit about but that did not always survive the social-media compression.[1][3]
The paper also reports data-efficiency results: a co-trained policy with 35 mobile demonstrations achieves 70 percent on Wipe Wine, which exceeds the 50 percent achieved by a non-co-trained policy with 50 mobile demonstrations. The authors interpret this as evidence that the principal value of co-training is sample efficiency, not just a final-performance boost.[1]
Were the viral cooking videos real?
In early January 2024, clips from the project spread widely on social media. Many of them, including the robot cooking a three-course Cantonese meal, showed human-teleoperated sessions rather than autonomous policies, and the project's YouTube description called Mobile ALOHA "a low-cost and whole-body teleoperation system for data collection".[3][9]
The robotics community quickly noted that several of the most-shared cooking clips were teleoperated data-collection sessions, not autonomous policy rollouts. The Mobile ALOHA project page itself separates an "Autonomous Skills" section from a "Teleoperation" section, and the paper is unambiguous that cooking shrimp autonomously is only a 40 percent success-rate behavior, but that context was stripped when the clips were reposted. IEEE Spectrum's Evan Ackerman published a piece titled That Awesome Robot Demo Could Have a Human in the Loop on 23 January 2024 that used Mobile ALOHA (alongside a Tesla Optimus shirt-folding video) as a case study in the broader problem of teleoperation versus autonomy in viral robot videos, arguing that descriptive captions and autonomy banners should be burned into the video frame rather than placed only in metadata.[3]
The autonomous cooking result in the paper (Cook Shrimp, 40 percent success over five trials) was a much simpler task than the teleoperated multi-dish clips.[1]
How does Mobile ALOHA compare to ALOHA, UMI, and DexCap?
Mobile ALOHA sits in a fast-moving cluster of low-cost data-collection systems released in 2023 and 2024. The following table compares several common reference points, restricted to facts that are directly verifiable from the cited primary sources.
| System | Year | Hardware approach | Approx. cost (USD) | Mobile? | Bimanual? |
|---|---|---|---|---|---|
| ALOHA | 2023 | 2 ViperX + 2 WidowX, fixed table | $20k | no | yes |
| ALOHA 2 | 2024 | Improved 2 ViperX + 2 WidowX | not stated | no | yes |
| Mobile ALOHA | 2024 | 2 ViperX + 2 WidowX on AgileX Tracer | $32k | yes | yes |
| UMI | 2024 | Handheld grippers + GoPro, no robot in data collection | under $500 per gripper | n/a | yes |
| DexCap | 2024 | Rokoko mocap gloves + chest-mounted cameras | not published | n/a | yes |
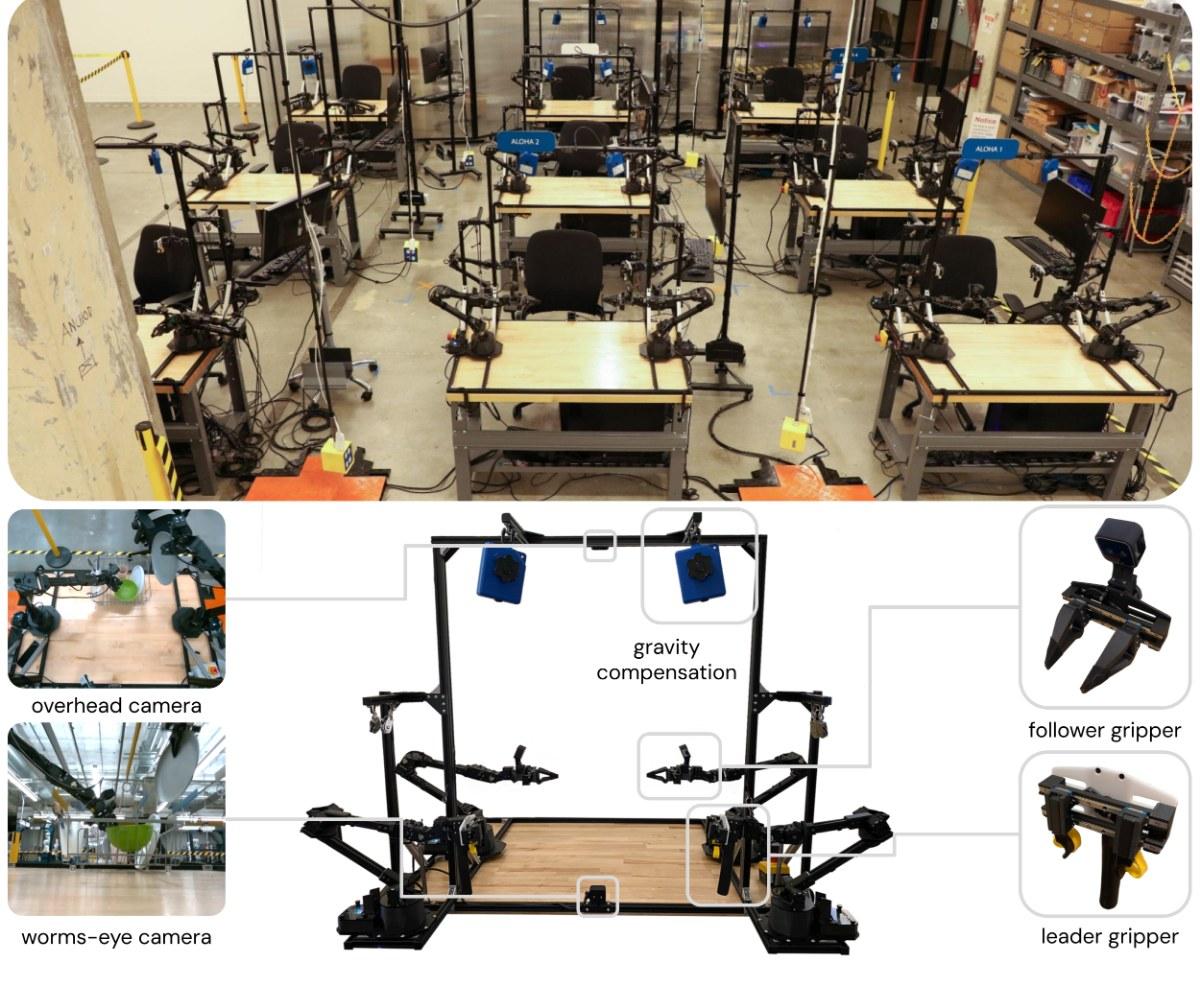
ALOHA, the predecessor system, established the leader-follower bimanual puppeteering interface and the ACT algorithm. It is fixed to a tabletop and has no mobility. ALOHA 2, released by a Google DeepMind team in February 2024 (arXiv:2405.02292), kept the tabletop form factor but introduced improved grippers, gravity compensation on the leader arms, and was open-sourced together with a MuJoCo Menagerie simulation model.[12] Mobile ALOHA reuses ALOHA's manipulation hardware almost unchanged but adds the mobile base and the waist tether for driving it.[1]
UMI (Universal Manipulation Interface), introduced by Cheng Chi and colleagues at Columbia, Stanford, and Toyota Research Institute in February 2024 (arXiv:2402.10329), is a deliberately different approach: it dispenses with the robot during data collection entirely. The operator holds a 3D-printed soft gripper rig with a GoPro camera on the back, and demonstrations are recorded as in-the-wild human video, then post-processed into deployable policies by aligning the gripper with a downstream manipulator. UMI excels at portability (it can be carried into any environment) and is much cheaper to collect data with, but it loses the proprioceptive richness of a robot demonstration and is a handheld manipulation interface rather than a mobile robot platform.[13]
DexCap, introduced by Chen Wang and colleagues at Stanford in March 2024, takes yet another route by using Rokoko motion-capture gloves with SLAM-based wrist tracking and chest-mounted cameras to capture high-degree-of-freedom finger trajectories for dexterous manipulation. DexCap is oriented toward hand-level dexterity (such as in-hand manipulation of small objects), where the ALOHA-class parallel-jaw grippers are inadequate. It does not address mobility.[14]
In terms of capability per dollar, Mobile ALOHA remains, as of mid-2026, the canonical low-cost reference for mobile bimanual research; UMI is the canonical reference for in-the-wild data collection without a robot; ALOHA 2 is the canonical reference for static bimanual manipulation; and DexCap occupies the dexterous-hand niche.
Is Mobile ALOHA open source?
Yes. The Mobile ALOHA team open-sourced all major artifacts under permissive licenses simultaneously with the paper:
- Hardware repository (https://github.com/MarkFzp/mobile-aloha) holds the teleoperation and data-collection code, the ROS 1 noetic launch files for the four arms and three cameras, udev rules for persistent device naming, and CANBUS configuration for the Tracer; 3D-printing files are part of the separate hardware assembly tutorial. Tested on Ubuntu 18.04 and 20.04. The repository had crossed 4,400 stars on GitHub by mid-2025.[2]
- ACT++ training repository (https://github.com/MarkFzp/act-plus-plus) holds the imitation learning code, including ACT, Diffusion Policy, and VINN implementations, the co-training data loader that supports zero-padding the static ALOHA actions to 16 dimensions, and two MuJoCo simulation environments (Transfer Cube and Bimanual Insertion) for sanity checks.[15]
- Dataset is hosted on Google Drive and consists of the per-task teleoperated demonstrations used in the paper, totalling several hundred episodes recorded as HDF5 files containing synchronized camera frames, joint states, and base velocities.
The hardware bill of materials is published as part of the paper's supplementary tutorial, including specific part numbers, vendor links, and assembly instructions.
How much does Mobile ALOHA cost, and can you buy one?
The research build costs approximately $32,000 USD in parts, as the paper states verbatim: "We build Mobile ALOHA with a $32k budget, comparable to a single industrial cobot such as the Franka Emika Panda."[1] For teams that prefer not to assemble the rig themselves, the robotics company Trossen Robotics, which manufactures the ViperX 300 and WidowX arms that ALOHA and Mobile ALOHA use, sold a commercial line of Aloha kits covering the static and mobile variants, since folded into its Trossen AI lineup (the Aloha Mobile kit is listed as discontinued as of November 2026). The Aloha line had three configurations:
- Aloha Solo, a portable single-arm leader-follower kit with Intel RealSense cameras and a tripod mount, launched November 2024 at a base price of $8,999.95.[16]
- Aloha Stationary, a tabletop bimanual kit corresponding to the original ALOHA / ALOHA 2 form factor.
- Aloha Mobile, the productized mobile kit, built on Trossen's own SLATE mobile base with ViperX follower and WidowX leader arms; it has since been discontinued.[4]
Trossen's current mobile kit, the Mobile AI, uses two leader-follower pairs of its WidowX AI arms and three Intel RealSense D405 cameras on a wheeled frame, priced at $33,695.95 without a laptop or $40,025.80 with one as of November 2026; Trossen says its bundled computers are optimized for ACT and ACT++ models.[17]
What impact has Mobile ALOHA had?
Mobile ALOHA's influence on robotics research between January 2024 and mid-2026 has been considerable, both as a piece of accessible hardware and as a methodological exemplar.
Imitation learning and behavior cloning. Mobile ALOHA helped re-validate behavior cloning as a viable approach for complex mobile bimanual tasks at a time when many groups were focused on reinforcement learning or sim-to-real transfer. The co-training recipe (mixing a small task-specific dataset with a large generic dataset, with zero-padding for action-space mismatch) has parallels in later vision-language-action models that train on mixtures of data from many robots; Physical Intelligence's pi0 (October 2024), for example, combined open-source robot datasets with its own data from eight robot configurations, including bimanual and mobile Trossen robots.[18]
Hardware popularization. By demonstrating a $32,000 mobile bimanual platform that could perform recognizable household tasks, Mobile ALOHA established a price point that pushed subsequent academic and industrial labs to keep their hardware in the low five figures rather than the low six. Many subsequent VLA papers, including OpenVLA-OFT, RDT-1B, and several entries in the LeRobot ecosystem, evaluate on ALOHA-style bimanual hardware.
Influence on data collection practice. Physical Intelligence's pi0 training data includes bimanual and mobile Trossen robots alongside UR5e, Franka, ARX, and Fibocom platforms, and its open-source openpi release includes checkpoints for ALOHA.[18][19]
Citations and academic uptake. The paper has accumulated several hundred citations (438 indexed on Semantic Scholar as of mid-2026, of which 22 are flagged as highly influential), placing it among the most-cited robot learning papers of 2024.[20] It is now a standard reference in survey papers on bimanual manipulation, imitation learning, and low-cost robotics.
Limitations and follow-on work. The authors acknowledge several limitations: the 90 cm by 135 cm footprint is too wide for some doorways and corridors, the fixed arm-mounting height excludes floor-level tasks, the policy is single-task with no autonomous improvement loop, and all demonstrations were collected by two expert operators, leaving learning from suboptimal, heterogeneous data to future work.[1]
Continue reading
- ALOHA (robot system)ALOHA (A Low-cost Open-source Hardware System for Bimanual Teleoperation) is an open-source robotic platform for collecting bimanual manipulation demonstrations and training imitation learning policies, built…Mentioned 73 times above
- Imitation LearningImitation learning is a family of methods for learning sequential behavior from demonstrations.Mentioned 5 times above
- ALOHA 2ALOHA 2 is an open-source, low-cost bimanual teleoperation hardware platform released in February 2024 by an Google DeepMind led team working with the original ALOHA authors at Stanford University.Mentioned 4 times above
- Robot learningRobot learning studies how robots acquire or improve behavior from data and experience.Mentioned 3 times above
- Physical IntelligencePhysical Intelligence (also known as Pi or π) is an American artificial intelligence robotics company that builds general-purpose foundation models and learning algorithms designed to control any robot for any…Mentioned twice above
- LeRobotLeRobot is an open-source, PyTorch-native library for end-to-end real-world robot learning developed by Hugging Face and a global community of contributors, often described as the "Transformers for robotics"…Listed in See also
More from See also
More to read
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14 ^15 ^16 ^17 ^18 ^19 ^20 ^21 ^22 ^23 ^24 ^25 ^26 ^27 ^28 ^29 ^30 ^31 ^32Fu, Zipeng; Zhao, Tony Z.; Finn, Chelsea. *Mobile ALOHA: Learning Bimanual Mobile Manipulation with Low-Cost Whole-Body Teleoperation*. arXiv:2401.02117, 4 January 2024. arxiv.org/...2401.02117. Accessed 2026-06-27.
- ^1 ^2Mobile ALOHA hardware and teleoperation code repository. github.com/...mobile-aloha. Accessed 2026-06-27.
- ^1 ^2 ^3 ^4Ackerman, Evan. *That Awesome Robot Demo Could Have a Human in the Loop*. IEEE Spectrum, 23 January 2024. spectrum.ieee.org/robot-teleoperation-autonomy. Accessed 2026-06-27.
- ^1 ^2Trossen Robotics, *Aloha Mobile* product page. trossenrobotics.com/aloha-mobile. Accessed 2026-06-27.
- Trossen Robotics, *The Aloha Project* overview. trossenrobotics.com/the-aloha-project. Accessed 2026-06-27.
- ^1 ^2 ^3 ^4 ^5 ^6Zhao, Tony Z.; Kumar, Vikash; Levine, Sergey; Finn, Chelsea. *Learning Fine-Grained Bimanual Manipulation with Low-Cost Hardware*. arXiv:2304.13705, 23 April 2023. arxiv.org/...2304.13705. Accessed 2026-06-27.
- Mobile ALOHA project page. mobile-aloha.github.io. Accessed 2026-06-27.
- ^Stanford Report, *Meet the robot that can saute shrimp*, April 2024. news.stanford.edu/...t-robot-that-can-saute-shrimp. Accessed 2026-06-27.
- ^1 ^2MIT Technology Review, *Watch this robot cook shrimp and clean autonomously*, 15 January 2024. technologyreview.com/...imp-and-clean-autonomously. Accessed 2026-06-27.
- Trossen Robotics, *ViperX 300 Robot Arm* product specifications. trossenrobotics.com/viperx-300-robot-arm. Accessed 2026-06-27.
- AgileX Robotics, *Tracer mini differential AGV* product page. global.agilex.ai/...tracer-mini. Accessed 2026-06-27.
- ^ALOHA 2 Team. *ALOHA 2: An Enhanced Low-Cost Hardware for Bimanual Teleoperation*. arXiv:2405.02292, May 2024. arxiv.org/...2405.02292. Accessed 2026-06-27.
- ^Chi, Cheng; et al. *Universal Manipulation Interface: In-The-Wild Robot Teaching Without In-The-Wild Robots*. arXiv:2402.10329, February 2024. arxiv.org/...2402.10329. Accessed 2026-06-27.
- ^Wang, Chen; et al. *DexCap: Scalable and Portable Mocap Data Collection System for Dexterous Manipulation*. arXiv:2403.07788, March 2024. arxiv.org/...2403.07788. Accessed 2026-06-27.
- ^ACT++ training repository for Mobile ALOHA. github.com/...act-plus-plus. Accessed 2026-06-27.
- ^Yahoo Finance / AccessNewswire, *Trossen Robotics Launches Aloha Solo: Affordable and Portable Machine Learning Lab for Advanced Robotics Research*, November 2024. finance.yahoo.com/...launches-aloha-solo-100000059. Accessed 2026-06-27.
- ^Trossen Robotics, *Mobile AI* product bundle. trossenrobotics.com/mobile-ai. Accessed 2026-06-27.
- ^1 ^2Physical Intelligence, *Our First Generalist Policy (pi0)*. physicalintelligence.company/...pi0. Accessed 2026-06-27.
- ^The Robot Report, *Physical Intelligence open-sources Pi0 robotics foundation model*. therobotreport.com/...i0-robotics-foundation-model. Accessed 2026-06-27.
- ^Semantic Scholar, *Mobile ALOHA: Learning Bimanual Mobile Manipulation with Low-Cost Whole-Body Teleoperation* (citation record). semanticscholar.org/...c3cf90ab92f2a206b858fef3b19. Accessed 2026-06-27.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
6 revisions by 1 contributor · v6 · 4,553 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (130 claims, 24 sources fetched); 30 material + 20 minor fixed
Cite this page: AI Wiki. "Mobile ALOHA." aiwiki.ai, updated 20 May 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/mobile_aloha