

NVIDIA TensorRT-LLM
NVIDIA TensorRT-LLM is an open-source library developed by nvidia for high-performance inference of large language models on NVIDIA GPUs. It provides a Python API for defining LLM architectures, runs models through a PyTorch-based executor with custom C++ and CUDA kernels (earlier versions also compiled models into engines for NVIDIA's tensorrt runtime, a path removed in 2026), and bundles inference-time optimizations such as in-flight (continuous) batching, paged key-value cache, FP8 and FP4 quantization, tensor and pipeline parallelism, lora adapter serving, and multiple speculative decoding methods.[1][2] NVIDIA first announced the library on 8 September 2023 and released it publicly under the Apache License 2.0 on 19 October 2023 on GitHub.[3][4] It began as the LLM-specific layer above general TensorRT, integrates with nvidia triton inference server and nvidia dynamo for serving, and underpins NVIDIA's official MLPerf Inference submissions on Hopper, Hopper Refresh, and Blackwell systems.[5][6] In its launch announcement NVIDIA stated that the library's in-flight batching and kernel optimizations "minimally double the throughput on a benchmark of real-world LLM requests on NVIDIA H100 Tensor Core GPUs" relative to the prior software stack.[4]
When was TensorRT-LLM released?
NVIDIA disclosed TensorRT-LLM on 8 September 2023 in a technical blog co-titled with the nvidia h100 inference results, describing it as a comprehensive library for compiling and running LLMs on H100 GPUs. The blog reported that, when paired with H100, TensorRT-LLM delivered up to 8x higher throughput on GPT-J 6B and 4.6x higher throughput on Llama 2 70B compared to the prior generation nvidia a100.[4][7] Before the public release, NVIDIA said it had been working closely with companies including Anyscale, Cohere, Databricks (MosaicML), Meta, Mistral AI, Perplexity, and Together AI to optimize LLM inference with it.[4]
The public open-source release followed on 19 October 2023, when NVIDIA published the repository at github.com/NVIDIA/TensorRT-LLM under Apache 2.0 and posted a follow-up blog announcing public availability.[3][8] The October release included support for Meta Llama 1 and 2, ChatGLM, Falcon, MPT, Baichuan, StarCoder, GPT, bloom, OPT, and others, across Ampere, Ada Lovelace, and Hopper GPUs, plus a native Windows beta for RTX GPUs.[8] Version 0.6.1, released in December 2023, added mistral 7b, and version 0.7.1 later that month added mixtral 8x7B.[31][10]
Through 2024 the library tracked the rapid release cadence of new open-weight models and NVIDIA hardware. Version 0.10 added weight streaming and support for llama 3 and Qwen2; version 0.12 added Llama 3.1.[10] Version 0.17 (early 2025) introduced nvidia b200 Blackwell support and NVFP4 GEMM kernels for llama 3 1 and mixtral, while version 0.18 deprecated Windows support to focus on data-center workloads.[10] Version 0.19 added deepseek v3 and DeepSeek-R1, FP8 multi-head latent attention on Hopper and Blackwell, eagle decoding EAGLE-3, and Multi-Token Prediction; it also open-sourced the C++ runtime that had previously been distributed as binaries.[10]
In September 2025 NVIDIA shipped TensorRT-LLM 1.0, designating the PyTorch-based backend as the stable default and stabilizing the high-level LLM Python API. The release stated that "the PyTorch-based architecture is now stable and the default experience" and that "the LLM API is now stable" with protected APIs guaranteed across subsequent 1.x releases.[10] It also added Phi-4, Qwen3, Mistral 3.1 vision-language model, and EXAONE 4.0, plus a comprehensive lora implementation across model families.[10] Version 1.1 (December 2025) added the OpenAI gpt-oss family and Hunyuan models, a KV-cache connector API for disaggregated serving, B300/GB300 hardware support, and a container baseline of PyTorch 25.10 with ModelOpt 0.37; version 1.2 (March 2026, with a 1.2.1 patch in April) added beta DGX Spark support.[10][31] Release candidates for version 1.3 from July 2026 onward removed the TensorRT engine backend, leaving PyTorch as the sole execution backend; as of November 2026, 1.2.1 remained the latest stable release, with 1.4 release candidates also published.[39][31]
The PyTorch workflow first appeared as an experimental feature in version 0.17 (February 2025) and became the default in 1.0.[10] Unlike the original flow, which built a TensorRT network directly through TensorRT-LLM's Python API and compiled it into an engine, the PyTorch backend loads Hugging Face checkpoints directly and runs them through a Python PyExecutor loop with custom kernels, CUDA Graphs and an overlap scheduler, with no separate engine-build step.[11][12][39] Both paths were exposed through the same LLM API until the TensorRT engine backend was removed during 1.3 development in mid-2026.[39]
How does TensorRT-LLM work?
TensorRT-LLM exposes a Python frontend whose modules deliberately mirror PyTorch idioms. A functional module offers tensor primitives such as einsum, softmax, matmul, and view; a layers module bundles building blocks including attention, MLP, and full transformer blocks; and the models module collects reference implementations of LLM architectures.[12] Until version 1.0, the canonical workflow was to define a model in this Python API, then call a build step that lowered the network to a TensorRT engine, applied kernel fusion and graph-level optimizations, baked in plugins for attention and other custom operators, and serialized a versioned engine file for a specific GPU SKU and tensor-parallel layout.[12][11]
In the TensorRT engine path, plugins were the core mechanism by which TensorRT-LLM injected hand-tuned CUDA kernels into the network. The library bundles plugins for fused multi-head attention (the gpt_attention plugin and the XQA kernel for grouped-query attention), paged KV cache management, FP8 and FP4 GEMM kernels, and tensor-parallel all-reduce primitives, among others.[12][11] The plugin system also lets the optimizer treat sequence-dependent operations as opaque nodes, enabling the rest of the graph to be compiled by TensorRT while the LLM-specific kernels handle dynamic sequence lengths.[12]
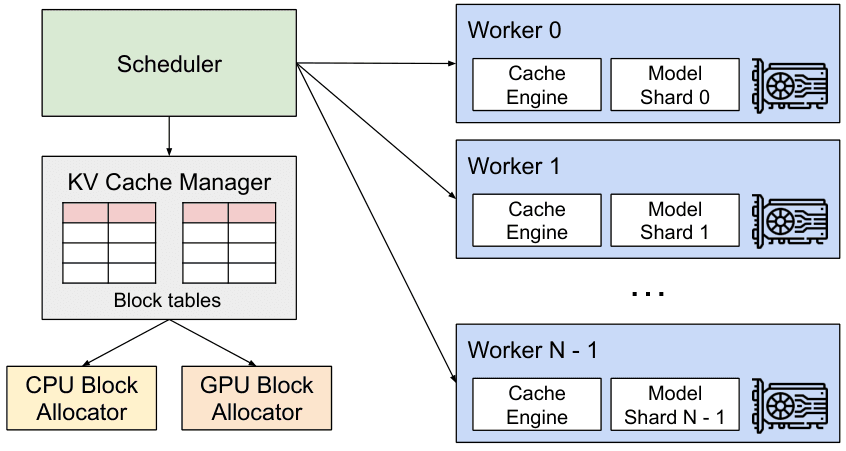
The runtime tier is implemented in C++ with Python bindings. The Executor (renamed PyExecutor in the PyTorch backend) manages incoming requests, with a Scheduler deciding which active requests step in each iteration and a KVCacheManager allocating and freeing paged KV cache blocks. Runtime optimizations layered on top of this loop include CUDA Graphs, an overlap scheduler that hides host-side request handling behind GPU work, speculative decoding, and chunked-context attention.[12][11] In the 1.0 PyTorch backend, models are defined as standard PyTorch modules and dispatched through the same executor, with the older TensorRT engine path retained for AOT-compiled engines through the 1.2 releases and removed during 1.3 development in 2026.[11][10][39]
How does TensorRT-LLM relate to TensorRT and Triton?
The library was created as the LLM-specific layer above general tensorrt, NVIDIA's deep learning inference SDK, and is designed to be served through external runtimes rather than as a standalone HTTP server in its base configuration. Three serving options are documented: the built-in trtllm-serve OpenAI-compatible server, the tensorrt_llm backend for nvidia triton inference server (which the project hosts in-tree under a triton_backend directory after a 2025 migration), and nvidia dynamo, NVIDIA's data-center inference framework announced at GTC 2025.[13][14][15] In the original design, TensorRT supplied the underlying graph compiler and runtime and TensorRT-LLM added the LLM-specific kernels and scheduling on top; since the 2026 removal of the TensorRT backend, TensorRT-LLM runs on PyTorch with its own kernels. Triton or Dynamo wraps the result in a production serving layer with HTTP and gRPC endpoints.[11][13][39]
Key features
In-flight (continuous) batching
In-flight batching, NVIDIA's term for continuous batching, evicts finished sequences from the running batch as soon as they emit their end-of-sequence token and immediately admits new requests in their place, rather than waiting for the whole batch to finish.[4][13] NVIDIA describes the mechanism plainly: "rather than waiting for the whole batch to finish before moving on to the next set of requests, the TensorRT-LLM runtime immediately evicts finished sequences from the batch and begins executing new requests while other requests are still in flight."[4] The technique was a headline feature of the September 2023 announcement and remains the default scheduling policy in the executor.[4][11] In-flight batching combines naturally with chunked context attention, in which long prompts are split into smaller chunks that interleave with decode steps from other requests, so that a single long prefill does not stall the GPU and starve concurrent decodes.[13][11]
Paged KV cache and KV cache reuse
Like paged attention in vllm, TensorRT-LLM stores the per-layer key-value cache in fixed-size blocks (128 tokens by default, any power of two, with blocks as small as 2 tokens supported for finer-grained reuse) so that allocation is O(blocks) instead of O(max sequence length). On top of paged storage, the library reuses cached blocks across requests with identical prefixes, offloads cold blocks to host memory, and applies prioritized eviction. NVIDIA's "early KV cache reuse" path can reduce time-to-first-token by up to 5x when a shared system prompt dominates the prefill, according to the company's measurements.[16][17]
Quantization
TensorRT-LLM's current PyTorch backend supports FP8 (per-tensor, block-scaled and row-wise) on Hopper and Blackwell, NVFP4 on Blackwell, FP8 and NVFP4 KV caches, and awq and gptq INT4 weight recipes; the earlier TensorRT engine path also offered INT8 and INT4 weight-only quantization and smoothquant (INT8 weights and activations).[18][11] Pre-quantized checkpoints for models such as Llama 3.1 8B Instruct are published on Hugging Face under the nvidia/ namespace and load directly into the LLM API.[18] FP8 on H100 roughly doubles peak throughput and halves activation memory versus FP16, while NVFP4 on B200 again roughly doubles peak throughput over FP8 on the same architecture, per NVIDIA's MLPerf-aligned benchmarks.[7][6]
Speculative decoding
The library implements draft-target speculative decoding plus four published algorithms: medusa, eagle decoding (EAGLE-1, EAGLE-2, and EAGLE-3), ReDrafter (a Recurrent Drafter model from Apple), and Lookahead decoding. NVIDIA reported draft-target throughput speedups of 2.63x to 3.55x on a single H200 running llama 3 3 70B at FP8 batch 1, with the largest gain (3.55x) from a Llama 3.2 1B draft model and the smallest (2.63x) from Llama 3.1 8B.[20] EAGLE-1 and EAGLE-2 logits prediction, draft acceptance, and draft generation execute inside the same TensorRT engine; EAGLE-3 runs as a modified linear-sequence variant.[19]
Multi-GPU and multi-node parallelism
TensorRT-LLM supports tensor parallelism (TP), pipeline parallelism (PP), context parallelism (CP), and expert parallelism (EP) for mixture-of-experts models. Multi-node deployments use MPI plus high-bandwidth interconnects (NVLink and InfiniBand), and version 0.21 added large-scale (wide) expert parallelism for DeepSeek-style MoEs.[10] An optional auto-parallelism planner, added in version 0.9 for the TensorRT engine-build workflow (and removed with that workflow in 2026), searched over TP and PP configurations for a given engine and hardware target to pick the layout with the best predicted throughput, so users do not have to hand-tune the parallelism shape for every model size.[10]
Multi-LoRA serving
A single base engine can serve multiple lora adapters concurrently, with the executor batching requests that target different adapters into the same forward pass. NVIDIA's August 2024 RTX AI Toolkit post reported that serving multiple LoRA adapters on one base model cost only about 3 percent in throughput and latency compared with the foundation model alone, measured on an RTX 4090 with Llama-3-8B.[21]
Disaggregated prefill and decode
By version 0.19 (May 2025), TensorRT-LLM supported disaggregated serving, in which the prefill (context) phase runs on one pool of GPUs and the decode (generation) phase runs on another, with KV cache shipped between them over MPI, UCX, or NIXL. NVIDIA reports up to 2x throughput gains for DeepSeek-R1 on GB200 GPUs and 1.7x to 6.11x gains for Qwen 3 under disaggregated configurations.[14][10]
Which models does TensorRT-LLM support?
TensorRT-LLM ships reference implementations and pre-tuned recipes for a broad list of decoder-only, encoder-decoder, mixture-of-experts, and multimodal architectures. The following table samples major language-model families and their advertised quantization options as of the 1.2 release.[22][11]
| Model family | Example variants | Quantization options |
|---|---|---|
| Meta Llama | llama, llama 2, llama 3, llama 3 1, llama 3 2, llama 3 3, llama 4 | FP16, BF16, FP8, NVFP4, INT8 SmoothQuant, INT4 AWQ, INT4 GPTQ |
| Mistral / mixtral | mistral 7b, Mixtral 8x7B, Mixtral 8x22B | FP16, FP8, NVFP4, INT4 AWQ |
| DeepSeek | deepseek v3, deepseek r1, DeepSeek-V3.1 | FP8 (with FP8 MLA), NVFP4 |
| Qwen | qwen, qwen 3, Qwen2.5-VL | FP16, FP8, NVFP4, INT4 AWQ |
| Microsoft Phi | phi, phi 3, phi 4 | FP16, FP8, INT4 AWQ |
| Google Gemma | Gemma, Gemma 2, Gemma 3 | FP16, FP8 |
| OpenAI gpt-oss | gpt oss | FP16, FP8, NVFP4 |
| Falcon | falcon, Falcon-180B | FP16, FP8, INT4 AWQ |
| GPT | GPT-2, GPT-J, GPT-NeoX | FP16, FP8, INT8 SmoothQuant |
| Encoder-decoder | T5, FLAN-T5, BART, mBART | FP16 |
| Multimodal | LLaVA-NeXT, Qwen2-VL, VILA, Llama 3.2 Vision | FP16, FP8 |
| Visual generation | FLUX, Wan 2.1, Wan 2.2 | FP16, FP8 |
The supported-models documentation lists more than fifty distinct architectures and is updated each release; some families in the table above, such as Falcon, GPT-J and GPT-NeoX, were supported through the legacy TensorRT engine path and do not appear in the PyTorch-backend list published after that path was removed.[22][39]
How fast is TensorRT-LLM?
NVIDIA has used TensorRT-LLM as the inference stack for every NVIDIA MLPerf Inference submission since v4.0 in March 2024, including the v4.1, v5.0, and v5.1 rounds.[5][6][23]
In MLPerf Inference v4.1 (28 August 2024), the first round with Blackwell silicon, NVIDIA's B200 submission used TensorRT-LLM to deliver 10,756 tokens per second in the Llama 2 70B server scenario and 11,264 tokens per second offline, reaching up to 4x the per-GPU throughput of nvidia h100 on the same benchmark.[5] Eight-GPU H200 systems hit 32,790 tokens per second on Llama 2 70B server and 57,177 tokens per second on Mixtral 8x7B server in the same round. NVIDIA also attributed up to 14% additional throughput on Llama 2 70B at H200 to TensorRT-LLM software improvements (XQA kernel work and additional layer fusions) between v4.0 and v4.1.[5]
In MLPerf Inference v5.0 (2 April 2025), B200 NVL8 systems running TensorRT-LLM were 3x faster than H200 NVL8 on the Llama 2 70B server scenario, 2.8x faster offline, and 3.1x faster on the new Llama 2 70B Interactive track. The GB200 NVL72 rack-scale submission posted up to 3.4x higher per-GPU performance than an eight-way H200 on Llama 3.1 405B and, scaled across 72 GPUs in a single NVLink domain, achieved up to 30x system-level throughput on the same benchmark. NVIDIA's v5.0 results relied on FP4 Tensor Cores plus the TensorRT Model Optimizer FP4 quantization pipeline running through TensorRT-LLM.[6]
NVIDIA's own H100 versus A100 measurements with TensorRT-LLM reported 10,907 output tokens per second at batch 64 on GPT-J 6B (3.0x A100), with first-token latency of 102 ms (4.7x faster than A100), and minimum first-token latency of 7.1 ms at batch 1.[7] On a DGX H100 with eight GPUs running Llama 2 70B, TensorRT-LLM produced a single inference in 1.7 seconds at batch 1 and exceeded five inferences per second under a 2.5-second response-time budget.[34] NVIDIA also reported GPT-J 6B gains of 2.4x offline and 2.9x server on H100 between the v3.1 and v4.0 MLPerf Inference rounds (September 2023 to March 2024), credited to TensorRT-LLM software rather than new silicon, and a further gain of up to 1.5x on H100 Llama 2 70B over the following year.[35][6]
Third-party benchmarks paint a more nuanced picture. The vLLM team published a head-to-head on 5 September 2024 between vLLM v0.6.0 and TensorRT-LLM r24.07 on Llama 3 8B and 70B on H100, using three workloads (ShareGPT, decode-heavy synthetic, and prefill-heavy synthetic), and reported that vLLM had the highest throughput on the ShareGPT and decode-heavy workloads on H100 (only marginally ahead of TensorRT-LLM for 70B) but lower throughput on the prefill-heavy workload, while TensorRT-LLM had the highest throughput for Llama 3 8B on a single A100.[24] A 2026 Spheron benchmark of Llama 3.3 70B at FP8 on one H100 found TensorRT-LLM ahead of vLLM on throughput at every concurrency level (8 percent at one request, 13 percent at 50) and on median time to first token (105 ms versus 120 ms), but with a cold start of about 28 minutes for engine compilation versus about a minute for vLLM.[25]
How does TensorRT-LLM differ from vLLM, SGLang, and llama.cpp?
vllm, originally developed at UC Berkeley's Sky Computing Lab and now maintained by a large community of contributors, supports NVIDIA, AMD and Intel GPUs and CPUs, plus hardware plugins for accelerators such as Google TPUs, and uses paged attention plus continuous batching as its core scheduling primitives.[37] It exposes an OpenAI-compatible HTTP server out of the box and is generally faster to bring up on a new model than TensorRT-LLM.[26]
sglang, introduced in a paper first posted in December 2023 by researchers from Stanford and UC Berkeley (LMSYS),[38] focuses on prefix-tree KV caching (RadixAttention), structured generation, and constrained decoding for agentic and chain-of-thought workloads. It targets NVIDIA GPUs primarily and added NVFP4 on Blackwell in 2025, narrowing the kernel-quality gap with TensorRT-LLM at the cost of supporting fewer model variants.[25]
llama cpp is a CPU-and-consumer-GPU-focused C++ runtime maintained by Georgi Gerganov; it uses the GGUF file format and supports Apple Silicon, Vulkan, and CUDA backends and its server supports continuous batching, but it is not designed for large-batch, multi-GPU data-center serving.[40]
huggingface tgi (Text Generation Inference) and lmdeploy from InternLM occupy adjacent niches. Hugging Face has put TGI into maintenance mode and now recommends engines such as vLLM and SGLang.[36] LMDeploy was among the engines in the vLLM team's September 2024 benchmark against TensorRT-LLM.[24]
Comparison guides such as Northflank's recommend TensorRT-LLM for maximum performance in NVIDIA-centric deployments and vLLM for flexibility and fast integration with Hugging Face models.[26]
Integration
Triton and Dynamo
The tensorrt_llm backend for nvidia triton inference server exposes TensorRT-LLM engines over Triton's HTTP and gRPC interfaces, supporting in-flight batching, paged attention, multiple decoding modes, multi-GPU tensor parallelism in either leader or orchestrator mode, and the same speculative-decoding methods available in the standalone executor.[13] The source for the backend was relocated into the TensorRT-LLM repository under triton_backend/ during 2025 so that releases ship in lockstep.[13]
At GTC 2025, NVIDIA introduced nvidia dynamo, a distributed inference framework that builds on Triton for serving large generative AI and reasoning models across multiple nodes. Dynamo schedules requests across disaggregated prefill and decode pools, performs LLM-aware request routing to maximize KV-cache reuse, and uses NIXL for fast inter-GPU data movement. It is interoperable with TensorRT-LLM, vLLM, SGLang, and raw PyTorch back ends, and NVIDIA said it increased requests served by up to 30x when running DeepSeek-R1 on GB200 NVL72 and more than doubled throughput for Llama 70B on Hopper. NVIDIA's Triton Inference Server was renamed "NVIDIA Dynamo Triton" within the Dynamo Platform on 18 March 2025.[15]
NIM microservices
nvidia nim is NVIDIA's packaged microservice format for self-hosted inference. Each NIM container bundles a pre-optimized inference engine (TensorRT-LLM for most large language models, with vLLM and SGLang as alternatives for specific models), the model weights, an OpenAI-compatible API, and Kubernetes manifests. NIM can also auto-build a TensorRT-LLM engine for a fine-tuned checkpoint and a target GPU at first launch, removing the need for users to run the compile step themselves.[28][29]
RTX and consumer hardware
A native Windows beta for nvidia RTX GPUs shipped alongside the public release in October 2023.[8] In November 2023 NVIDIA announced an update extending support to RTX GPUs with 8 GB of VRAM and adding an OpenAI Chat API wrapper, and it later published optimized community models including Llama 2 and Mistral 7B for RTX systems.[9][30] Windows support was deprecated in TensorRT-LLM 0.18.0 (early 2025) in favor of consolidating around the Linux data-center stack, although NVIDIA's separate "TensorRT for RTX" library continues to target Windows 11 client workloads.[10][30] The reference RAG application nvidia ChatRTX was built on TensorRT-LLM and is open-sourced as a developer sample.[9]
NeMo and other NVIDIA frameworks
TensorRT-LLM is the inference back end for models trained or fine-tuned with NVIDIA NeMo Framework: a NeMo checkpoint can be exported to a TensorRT-LLM engine through the nemo.export utility, which then loads into a Triton or Dynamo deployment without leaving the NVIDIA tool chain.[33] On embedded targets, NVIDIA also ships a Jetson-oriented build that integrates TensorRT-LLM optimizations (in-flight batching plus INT4 AWQ); NVIDIA's Jetson AGX Orin MLPerf v4.1 submission used this path to deliver a reported 6.2x throughput improvement on GPT-J compared with the prior round.[5][9]
Is TensorRT-LLM open source?
The TensorRT-LLM source repository at github.com/NVIDIA/TensorRT-LLM has been published under the Apache License 2.0 since its 19 October 2023 open-source release.[3][31] As of May 2026 the repository reports 13,700 stars, 6,838 commits on the main branch, 587 open issues, and 699 open pull requests, with code distributed roughly 55% Python, 36% C++, and 8% CUDA.[1] Release artifacts are published to PyPI as the tensorrt-llm package and to NGC as the tensorrt-llm/release container.[32] Until version 0.19, the C++ runtime was distributed as compiled binaries inside the source tree; that release "open sourced" the C++ runtime so that all of the inference loop is now available as source code.[10]
Continue reading
- TensorRTTensorRT is NVIDIA's software development kit (SDK) for high-performance deep learning inference on NVIDIA GPUs.Mentioned 75 times above
- vLLMvLLM is an open-source inference and serving engine for large language models. It is software for running already trained models, either through a Python interface for offline work or through a network server…Mentioned 13 times above
- EAGLE (speculative decoding)EAGLE (Extrapolation Algorithm for Greater Language-model Efficiency) is a lossless speculative decoding method that speeds up large language model (LLM) inference by 2x to 6.5x by doing autoregression at the…Mentioned 9 times above
- KV CacheKV cache, short for key-value cache, is transient model state used during Transformer generation.Mentioned 7 times above
- AWQ (Activation-aware Weight Quantization)Activation-aware Weight Quantization (AWQ) is a post-training quantization method for large language models that compresses weights to 4-bit (and optionally 3-bit) integers while keeping near-FP16 task…Mentioned 7 times above
- MLPerfMLPerf is the AI industry's standard suite of benchmarks for measuring how fast machine learning systems train and run models, developed and maintained by MLCommonsMentioned 7 times above
More from See also
References
- ^1 ^2NVIDIA, "TensorRT-LLM (GitHub repository)", NVIDIA, 2026-04-20. github.com/...TensorRT-LLM. Accessed 2026-05-26.
- ^NVIDIA, "Welcome to TensorRT LLM's Documentation", NVIDIA, 2026-04-20. nvidia.github.io/TensorRT-LLM. Accessed 2026-05-26.
- ^1 ^2 ^3NVIDIA, "TensorRT-LLM LICENSE (Apache License 2.0)", NVIDIA, 2023-10-17. github.com/...LICENSE. Accessed 2026-05-26.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7Neal Vaidya, Nick Comly, Joe DeLaere, Ankit Patel, Fred Oh, "NVIDIA TensorRT-LLM Supercharges Large Language Model Inference on NVIDIA H100 GPUs", NVIDIA Developer Blog, 2023-09-08. developer.nvidia.com/...erence-on-nvidia-h100-gpus. Accessed 2026-05-26.
- ^1 ^2 ^3 ^4 ^5Dave Salvator, "NVIDIA Blackwell Platform Sets New LLM Inference Records in MLPerf Inference v4.1", NVIDIA Developer Blog, 2024-08-28. developer.nvidia.com/...s-in-mlperf-inference-v4-1. Accessed 2026-05-26.
- ^1 ^2 ^3 ^4 ^5Dave Salvator, "NVIDIA Blackwell Delivers Massive Performance Leaps in MLPerf Inference v5.0", NVIDIA Developer Blog, 2025-04-02. developer.nvidia.com/...s-in-mlperf-inference-v5-0. Accessed 2026-05-26.
- ^1 ^2 ^3NVIDIA, "H100 has 4.6x A100 Performance in TensorRT-LLM, achieving 10,000 tok/s at 100ms to first token", NVIDIA TensorRT-LLM Documentation, 2023-11-13. nvidia.github.io/...H100vsA100. Accessed 2026-05-26.
- ^1 ^2 ^3NVIDIA, "Optimizing Inference on Large Language Models with NVIDIA TensorRT-LLM, Now Publicly Available", NVIDIA Developer Blog, 2023-10-19. developer.nvidia.com/...llm-now-publicly-available. Accessed 2026-05-26.
- ^1 ^2 ^3NVIDIA Blogs, "Igniting the Future: TensorRT-LLM Release Accelerates AI Inference Performance, Adds Support for New Models Running on RTX-Powered Windows 11 PCs", NVIDIA Blog, 2023-11-15. blogs.nvidia.com/...e-rtx-ai-tensorrt-llm-chat-api. Accessed 2026-05-26.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13 ^14NVIDIA, "Release Notes (TensorRT-LLM)", NVIDIA Documentation, 2026-04-20. nvidia.github.io/...release-notes. Accessed 2026-05-26.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10NVIDIA, "Architecture Overview (TensorRT-LLM)", NVIDIA Documentation, 2026-04-20. nvidia.github.io/...overview. Accessed 2026-05-26.
- ^1 ^2 ^3 ^4 ^5 ^6NVIDIA, "Model Definition (TensorRT-LLM core concepts)", NVIDIA Documentation, 2026-04-20. nvidia.github.io/...core-concepts. Accessed 2026-05-26.
- ^1 ^2 ^3 ^4 ^5 ^6NVIDIA, "TensorRT-LLM Backend (Triton Inference Server)", NVIDIA Triton Documentation, 2026-02-15. docs.nvidia.com/...README. Accessed 2026-05-26.
- ^1 ^2NVIDIA, "Disaggregated Serving in TensorRT-LLM (tech blog 5)", NVIDIA TensorRT-LLM Documentation, 2025-06-15. nvidia.github.io/...egated_Serving_in_TensorRT-LLM. Accessed 2026-05-26.
- ^1 ^2NVIDIA, "Introducing NVIDIA Dynamo, A Low-Latency Distributed Inference Framework for Scaling Reasoning AI Models", NVIDIA Developer Blog, 2025-03-18. developer.nvidia.com/...caling-reasoning-ai-models. Accessed 2026-05-26.
- ^NVIDIA, "5x Faster Time to First Token with NVIDIA TensorRT-LLM KV Cache Early Reuse", NVIDIA Developer Blog, 2024-11-08. developer.nvidia.com/...t-llm-kv-cache-early-reuse. Accessed 2026-05-26.
- ^NVIDIA, "KV cache reuse (TensorRT-LLM)", NVIDIA Documentation, 2026-04-20. nvidia.github.io/...kv-cache-reuse. Accessed 2026-05-26.
- ^1 ^2NVIDIA, "Quantization (TensorRT-LLM)", NVIDIA Documentation, 2026-04-20. nvidia.github.io/...quantization. Accessed 2026-05-26.
- ^NVIDIA, "Speculative Sampling (TensorRT-LLM)", NVIDIA Documentation, 2026-04-20. nvidia.github.io/...speculative-decoding. Accessed 2026-05-26.
- ^NVIDIA, "Boost Llama 3.3 70B Inference Throughput 3x with NVIDIA TensorRT-LLM Speculative Decoding", NVIDIA Developer Blog, 2024-12-17. developer.nvidia.com/...t-llm-speculative-decoding. Accessed 2026-05-26.
- ^NVIDIA, "Deploy Diverse AI Apps with Multi-LoRA Support on RTX AI PCs and Workstations", NVIDIA Developer Blog, 2024-08-28. developer.nvidia.com/...tx-ai-pcs-and-workstations. Accessed 2026-05-26.
- ^1 ^2NVIDIA, "Supported Models (TensorRT-LLM)", NVIDIA Documentation, 2026-04-20. nvidia.github.io/...supported-models. Accessed 2026-05-26.
- ^MLCommons, "MLPerf Inference: Datacenter Benchmark Results", MLCommons, 2025-09-09. mlcommons.org/...inference-datacenter. Accessed 2026-05-26.
- ^1 ^2vLLM team, "vLLM v0.6.0: 2.7x Throughput Improvement and 5x Latency Reduction", vLLM Blog, 2024-09-05. blog.vllm.ai/...perf-update. Accessed 2026-05-26.
- ^1 ^2Spheron, "vLLM vs TensorRT-LLM vs SGLang: H100 Benchmarks (2026)", Spheron Blog, 2026-02-12. spheron.network/...nsorrt-llm-vs-sglang-benchmarks. Accessed 2026-05-26.
- ^1 ^2Northflank, "vLLM vs TensorRT-LLM: Key differences, performance, and how to run them", Northflank Blog, 2025-11-10. northflank.com/...tensorrt-llm-and-how-to-run-them. Accessed 2026-05-26.
- MarkTechPost, "vLLM vs TensorRT-LLM vs HF TGI vs LMDeploy: A Deep Technical Comparison for Production LLM Inference", MarkTechPost, 2025-11-19. marktechpost.com/...n-for-production-llm-inference. Accessed 2026-05-26.
- ^NVIDIA, "NVIDIA NIM Microservices for Accelerated AI Inference", NVIDIA, 2025-09-15. nvidia.com/...nim-microservices. Accessed 2026-05-26.
- ^NVIDIA, "Deploying Fine-Tuned AI Models with NVIDIA NIM", NVIDIA Developer Blog, 2024-11-21. developer.nvidia.com/...-ai-models-with-nvidia-nim. Accessed 2026-05-26.
- ^1 ^2NVIDIA, "Supercharging LLM Applications on Windows PCs with NVIDIA RTX Systems", NVIDIA Developer Blog, 2023-11-15. developer.nvidia.com/...cs-with-nvidia-rtx-systems. Accessed 2026-05-26.
- ^1 ^2 ^3 ^4NVIDIA, "TensorRT-LLM Releases (GitHub)", NVIDIA, 2026-04-20. github.com/...releases. Accessed 2026-05-26.
- ^NVIDIA, "tensorrt-llm (PyPI)", PyPI, 2026-04-20. pypi.org/...tensorrt-llm. Accessed 2026-05-26.
- ^NVIDIA, "Deploy NeMo Framework Models (NeMo Framework User Guide)", NVIDIA Documentation, 2024-12-10. docs.nvidia.com/...deployment. Accessed 2026-05-26.
- ^Dave Salvator, Ashraf Eassa, "Achieving Top Inference Performance with the NVIDIA H100 Tensor Core GPU and NVIDIA TensorRT-LLM", NVIDIA Developer Blog, 2023-12-14. developer.nvidia.com/...pu-and-nvidia-tensorrt-llm. Accessed 2026-11-02.
- ^Ashraf Eassa et al., "NVIDIA H200 Tensor Core GPUs and NVIDIA TensorRT-LLM Set MLPerf LLM Inference Records", NVIDIA Developer Blog, 2024-03-27. developer.nvidia.com/...perf-llm-inference-records. Accessed 2026-11-02.
- ^Hugging Face, "text-generation-inference (GitHub README)", Hugging Face. github.com/...text-generation-inference. Accessed 2026-11-02.
- ^vLLM project, "vLLM (GitHub README)", vLLM. github.com/...vllm. Accessed 2026-11-02.
- ^Lianmin Zheng et al., "SGLang: Efficient Execution of Structured Language Model Programs", arXiv:2312.07104, 2023-12-12. arxiv.org/...2312.07104. Accessed 2026-11-02.
- ^1 ^2 ^3 ^4 ^5 ^6NVIDIA, "Migration Guide: TensorRT Backend Removed", NVIDIA TensorRT-LLM Documentation. nvidia.github.io/...tensorrt-backend-removal. Accessed 2026-11-02.
- ^ggml-org, "llama.cpp server README", GitHub. github.com/...README.md. Accessed 2026-11-02.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
8 revisions · v8 · 4,219 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (150 claims, 44 sources fetched); 15 material + 23 minor fixed
Cite this page: AI Wiki. "NVIDIA TensorRT-LLM." aiwiki.ai, updated 1 Nov 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/tensorrt_llm