

AIME (American Invitational Mathematics Examination)
The American Invitational Mathematics Examination (AIME) is a 15-question, 3-hour mathematics competition for high school students in the United States and Canada, administered by the Mathematical Association of America (MAA) since 1983. Each answer is an integer from 000 to 999, which makes the contest cleanly auto-gradable, and beginning in 2024 the AIME became one of the most widely cited benchmarks for evaluating mathematical reasoning in large language models. Frontier reasoning models now routinely score above 90% on AIME 2024 and AIME 2025 and reach 100% with Python tool access, so the benchmark is widely regarded as saturated at the frontier.[1][3][4]
In the human pipeline, the AIME serves as the intermediate round in the USAMO qualification process, sitting between the entry-level AMC 10/AMC 12 examinations and the proof-based USA Mathematical Olympiad (USAMO).[1][2] As an AI benchmark it is used across the new generation of reasoning systems, including OpenAI o1, OpenAI o3, DeepSeek-R1, Gemini 2.5 Pro, Grok 3, Grok 4, and the Claude Opus 4.5 and Claude Sonnet 4.6 series. Its integer-only answer format, multi-step reasoning requirements, and clean automatic grading made it a natural fit for AI evaluation, although by 2025 it had largely saturated at the frontier and prompted the introduction of harder successor benchmarks.[3][4]
What is the AIME and when was it created?
The AIME was first administered in 1983, replacing an earlier pipeline that ran directly from the American High School Mathematics Examination (AHSME) to the USAMO. The MAA introduced the AIME as a middle round to better distinguish among top AHSME scorers and to provide a less abrupt transition between multiple-choice contests and the proof-based USAMO. The AHSME itself was rebranded as the AMC 12 in 2000, with the AMC 10 added the same year to broaden participation.[1][2]
From 1983 until 1999, only a single annual AIME was held in late March or early April. From 2000 through 2026, the MAA also offered a second sitting, the AIME II, as an alternate test for students who could not take the AIME I due to scheduling conflicts, illness, or international time zones. Students may sit only one of the two; attempting both results in disqualification.[1][2]
Format and rules
The AIME consists of 15 free-response problems with a 3-hour total time limit, and each answer is an integer from 000 to 999 inclusive. Through 2026 it was a single paper session with answers entered on an optical-mark-recognition (OMR) bubble sheet; from 2027 it is a computer-based exam at Pearson testing centers, given in two 90-minute parts of 8 and 7 questions.[2] This format eliminates guessing on multiple-choice options while retaining ease of automated grading.[1][2]
Scoring is exactly one point per correct answer with no penalty for incorrect answers and no partial credit. The maximum score is therefore 15 out of 15. Calculators and other computing aids are prohibited. Pencils, erasers, rulers and compasses were historically permitted, but under the 2027 testing-center format students may bring no materials and are given laminated graph-paper booklets and pens.[1][2]
Problems are arranged in roughly increasing order of difficulty. Topics covered include algebra, combinatorics, number theory, probability, geometry, and trigonometry, but no calculus. Solutions usually require multi-step deductions, careful case analysis, or clever transformations, with the integer answer often appearing as the result of a non-trivial computation rather than a memorized formula.[1]
AIME I and AIME II
Through 2026, both versions of the AIME were administered annually (from 2027 there is a single February 5-6 window and no AIME II):[2]
- AIME I, the primary test, is typically held on a Tuesday or Thursday in early February. AIME I 2025 was given on Thursday, February 6, 2025.[5]
- AIME II, the alternate, is held roughly a week later. AIME II 2025 was given on Wednesday, February 12, 2025.[5]
Under the two-sitting system the MAA stated that "Students may only take the AIME once" and that any student who took both the AIME I and II would be disqualified.[2]
How do students qualify for the AIME?
Invitation to the AIME is automatic for top scorers on the AMC 10 and AMC 12 contests. Through the 2026 contest, MAA policy extended AIME invitations to "at least the top 5% of all scorers" on the AMC 12 and "at least the top 2.5% of all scorers" on the AMC 10, and recent cycles in practice invited roughly the top 13-15% of AMC 12 and 6-8% of AMC 10 takers. For 2027 the MAA switched to fixed thresholds: a score of at least 100 on the AMC 10 or at least 85 on the AMC 12.[1][2] A third pathway exists through the USA Mathematical Talent Search (USAMTS), which awards AIME invitations to students achieving a sufficiently high cumulative score (at least 68 of 75 under the rule in place since 2025) across its three rounds.[2]
Path to the IMO
The AIME is the second step in a five-stage selection pipeline used by the MAA to choose the U.S. team for the International Mathematical Olympiad (IMO):
- AMC 10 or AMC 12: open multiple-choice contests with roughly 300,000 combined participants annually.
- AIME: invitational round for top AMC scorers.
- USAMO / USAJMO: proof-based national olympiad. Through the 2026 cycle, qualification was determined by a weighted index:
- Mathematical Olympiad Program (MOP): three-week residential summer training program for the top USAMO/USAJMO scorers, historically held at Carnegie Mellon University and formerly known as the Mathematical Olympiad Summer Program (MOSP).
- Team Selection Tests (TST): since 2011, a TSTST held at MOP picks the students who sit the Team Selection Tests the following school year, and that cycle of exams, which includes the USAMO, determines the six members of the U.S. IMO team.[6]
The MAA invites more than 400 students to the USAMO and USAJMO each year; top scorers are invited to MOP, and six are ultimately selected for the IMO team.[2][6]
How is AIME used as an AI benchmark?
Why does AIME suit AI evaluation?
The AIME became one of the most prominent benchmarks for evaluating mathematical reasoning in large language models because its design happens to satisfy many practical requirements for automatic scoring:
- Integer-only answers. Each problem has a unique integer answer from 0 to 999, allowing exact-match grading without complex symbolic-equivalence checks. This contrasts with the MATH dataset, where answers can be algebraic expressions.
- Non-trivial reasoning. Unlike multiple-choice tests, the AIME cannot be solved by elimination or lucky guesses. Problems typically require several pages of work for a strong human solver.
- Standardized difficulty. The MAA has administered the contest yearly for over four decades, producing a long history of problems with calibrated difficulty.
- Public availability. Problems and solutions for AIME 1983 through the most recent year are catalogued on the Art of Problem Solving (AoPS) wiki and elsewhere, making the benchmark trivially accessible for evaluation pipelines.[8]
The standard convention in AI evaluations is to use AIME I and AIME II from a given year (a total of 30 problems) and report accuracy as the percentage of problems solved. Common protocols include pass@1 (single sample), cons@64 or majority@64 (majority vote across 64 samples), and tool-augmented variants in which the model may call a Python interpreter.[3][9]
What scores have AI models reported on AIME?
The following AIME scores have been reported by AI laboratories in official announcements, system cards, or technical reports. Protocols vary substantially between labs and even between models from the same lab, so direct comparisons should be treated with caution. As a single-figure summary of the difficulty curve, OpenAI's non-reasoning GPT-4o solved roughly 12% (1.8/15) of AIME 2024 problems, whereas less than a year later xAI reported Grok 4 Heavy reaching 100% on AIME 2025 with Python tool access.[3][21]
OpenAI o-series
In its September 2024 "Learning to reason with LLMs" announcement, OpenAI reported that on AIME 2024, GPT-4o solved "on average 12% (1.8/15) of problems," while o1 averaged "74% (11.1/15) with a single sample per problem, 83% (12.5/15) with consensus among 64 samples, and 93% (13.9/15) when re-ranking 1000 samples with a learned scoring function." OpenAI noted that 13.9/15 "places it among the top 500 students nationally and above the cutoff for the USA Mathematical Olympiad."[3]
OpenAI's December 20, 2024 announcement of o3 reported a score of 96.7% on AIME 2024, with the model "missing just one question," compared with o1's 83.3% (the cons@64 result).[10]
OpenAI's January 31, 2025 o3-mini launch post reported that o3-mini (high) reached 83.6% on AIME 2024, said that with medium reasoning effort o3-mini "matches the performance of o1" on evaluations including AIME, and said that with high effort it outperforms both o1-mini and o1. OpenAI's April 2025 o3 and o4-mini announcement later listed o3-mini at 87.3%.[11][12]
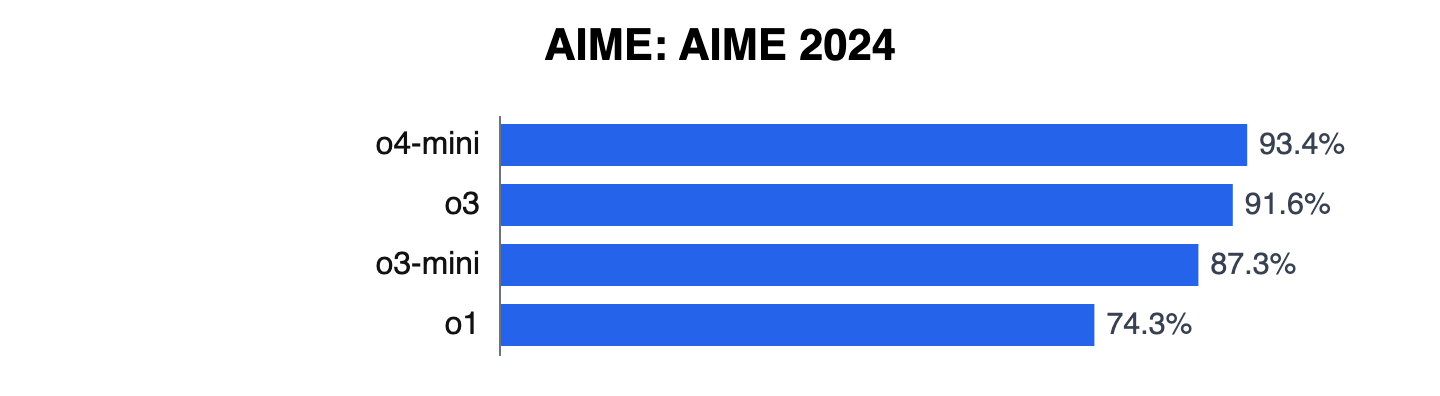
OpenAI's April 16, 2025 announcement of o3 and o4-mini reported the following pass@1 scores (no tools):
| Model | AIME 2024 | AIME 2025 |
|---|---|---|
| o1 | 74.3% | 79.2% |
| o3-mini | 87.3% | 86.5% |
| o3 | 91.6% | 88.9% |
| o4-mini | 93.4% | 92.7% |
With access to a Python interpreter, o4-mini reached 99.5% pass@1 and 100% consensus@8 on AIME 2025, and o3 reached 98.4% pass@1 and 100% consensus@8 on the same exam.[12]
DeepSeek
The DeepSeek-R1 technical report (January 2025) reported that DeepSeek-R1 "achieves a score of 79.8% Pass@1 on AIME 2024, slightly surpassing OpenAI-o1-1217," along with the following AIME 2024 scores:[9]
| Model | pass@1 | cons@64 |
|---|---|---|
| DeepSeek-R1 | 79.8% | N/A |
| DeepSeek-R1-Zero | 71.0% | 86.7% |
| DeepSeek-R1-Distill-Qwen-7B | 55.5% | 83.3% |
| DeepSeek-R1-Distill-Qwen-14B | 69.7% | 80.0% |
| DeepSeek-R1-Distill-Qwen-32B | 72.6% | 83.3% |
| DeepSeek-R1-Distill-Llama-70B | 70.0% | 86.7% |
All evaluations used a sampling temperature of 0.6, a top-p value of 0.95, and a maximum generation length of 32,768 tokens.[9]
xAI Grok
xAI's February 17, 2025 release of Grok 3 reported that with the highest level of test-time compute (cons@64), Grok 3 (Think) achieved 93.3% on AIME 2025, which had been administered just days before the announcement on February 6 and 12. The smaller Grok 3 mini reached 95.8% on AIME 2024 in cons@64 mode.[13]
Grok 4, unveiled on July 9, 2025, was reported by xAI to score 100% on AIME 2025 in its Heavy configuration with Python tools (98.8% for base Grok 4 with tools) and 91.7% for base Grok 4 without tools; Epoch AI argued that the Python-tool setting should not have been used for a contest meant to be solved by hand.[14][21]
Google DeepMind Gemini
Gemini 2.5 Pro was reported by Google DeepMind to score approximately 92.0% on AIME 2024 and 86.7% on AIME 2025 in single-attempt evaluations, placing it among the top single-shot performers on the AIME 2025 leaderboard at the time of release in early 2025.[15]
Anthropic Claude
For the Claude 4 family, Claude Opus 4 was reported by Anthropic to score around 75.5% on AIME, rising to approximately 90.0% in high-compute settings. Claude Sonnet 4.5 was reported to reach roughly 87% without tools on AIME 2025 and 100% with Python tool access. Claude Opus 4.5, released in November 2025, was reported to achieve 92.77% without tools and 100% with Python tools on AIME 2025; Anthropic's system card cautioned that it has "some concerns that contamination may have inflated this score."[16][17]
Other models
- GPT-4o (non-reasoning baseline, AIME 2024): ~12% (1.8/15), per OpenAI's o1 announcement.[3]
- QwQ-32B-Preview (Alibaba, November 28, 2024): reported by Alibaba to score 50.0% on AIME, surpassing o1-preview and GPT-4o, while OpenAI's o1-mini scored 56.7%.[18]
- Qwen3 (April 2025): the technical report describes the Qwen3 series as surpassing both QwQ in thinking mode and Qwen2.5 in non-thinking mode on AIME and other math benchmarks.[19]
Why is AIME considered saturated, and what replaced it?
By mid-2025, frontier models were routinely scoring above 90% on AIME 2024 and AIME 2025 in their default configurations and 100% with Python tool access, prompting widespread discussion that the benchmark had effectively saturated.[4][20] Several methodological concerns were also raised:
- Data contamination. AIME problems and solutions are widely available on the AoPS wiki and dozens of solution repositories. Independent analyses suggest that widely available AIME 2024 problems may have appeared in pretraining corpora for some models, inflating reported scores relative to genuinely held-out contests. Researchers have responded by adopting timeline-locked evaluation protocols in which models are tested only on problems released after the model's pretraining cutoff.[4]
- Inconsistent protocols. Reported scores variously use pass@1, cons@k (for k = 8, 16, 32, 64), pass@k, sampling temperature, and Python tool access. A model claiming "99% on AIME" with Python tools is not directly comparable to one claiming "75% pass@1" without tools.
- Sample-size variance. The AIME has only 15 problems per paper and 30 per year. Small differences in absolute score (e.g., 86.7% vs 90.0%) correspond to a single problem and can fluctuate substantially across sampling runs.
- Limited difficulty range. AIME problems are calibrated for talented high school students. Researchers have noted that performance on the AIME is no longer predictive of performance on genuinely hard mathematics tasks such as research-level problems or the proof-based USAMO and IMO.
In response, the AI evaluation community has shifted attention to harder mathematics benchmarks, including:
- USAMO and IMO problems, which require full written proofs rather than integer answers.
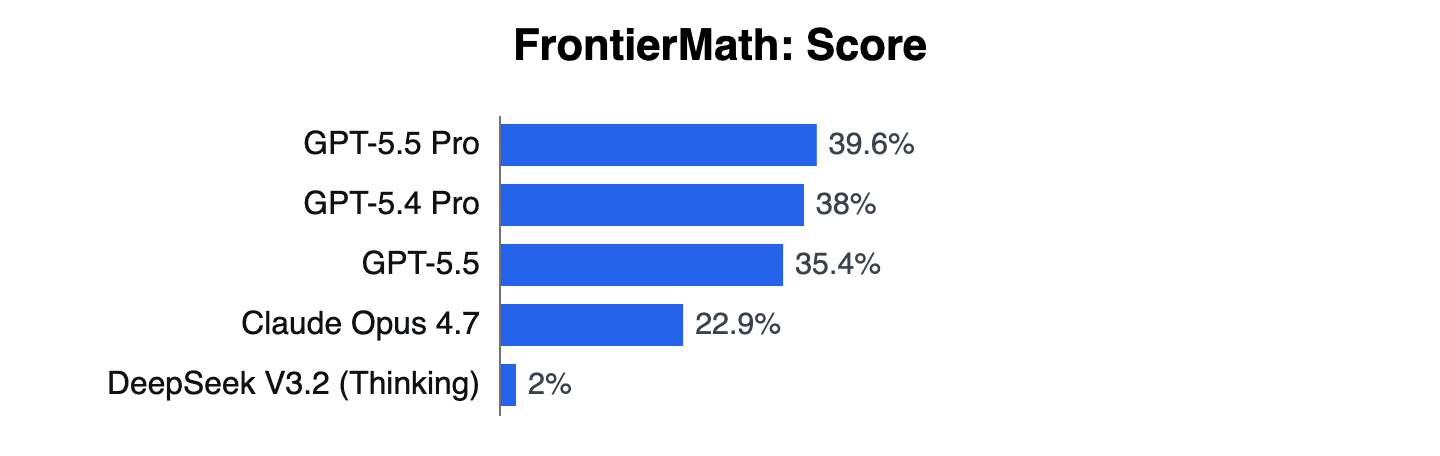
- FrontierMath, a benchmark of unpublished research-level mathematics problems designed by working mathematicians.
- MathArena and other live, timeline-locked evaluation suites that test models on each year's AIME, HMMT, and IMO papers immediately after release to minimize contamination risk.
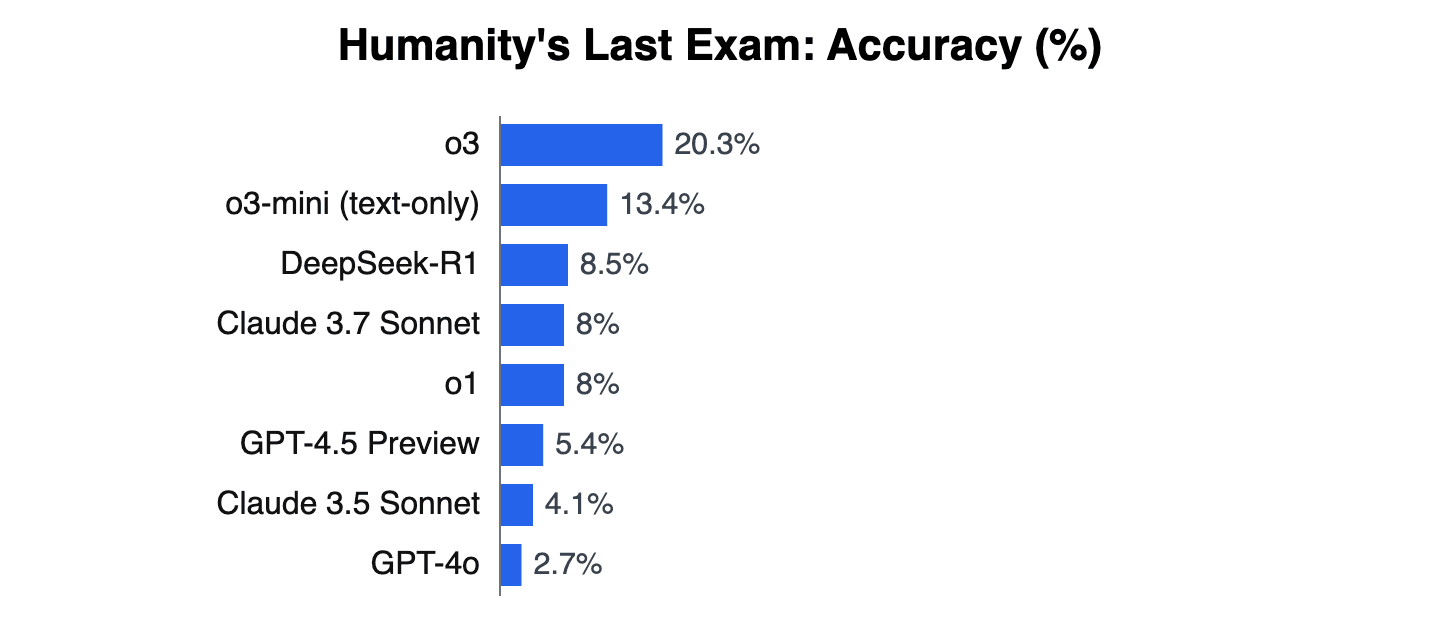
- Humanity's Last Exam, a broader expert-curated benchmark that includes advanced mathematics among other disciplines.
For specific year-by-year results, see AIME 2024 and AIME 2025.
Significance for human competition
Despite saturation as an AI benchmark, the AIME remains an important fixture of secondary mathematics education in the United States. Several thousand students qualify each year, and the exam continues to serve as the principal gateway to the USAMO and, ultimately, the IMO. The combination of historical longevity, well-calibrated difficulty, and a clean integer answer format that originally made the AIME attractive to AI researchers continues to make it a respected human competition independent of its role in evaluating language models.
Continue reading
- Benchmark (AI)In artificial intelligence and machine learning, a benchmark is a specified evaluation used to compare systems under common conditions.Mentioned 13 times above
- MATHMATH is a benchmark of 12,500 competition mathematics problems used to evaluate the mathematical problem-solving ability of machine learning systems, particularly large language models.Mentioned twice above
- Reasoning modelsReasoning models are large language models that are post-trained or configured to spend additional inference-time computation on intermediate steps before returning an answer.Listed in See also
- FrontierMathFrontierMath is an advanced mathematical reasoning benchmark created by Epoch AI in collaboration with over 60 expert mathematicians, including Fields Medalists Terence Tao, Timothy Gowers, and Richard…Listed in See also
- Humanity's Last ExamHumanity's Last Exam (HLE) is a multi-modal AI benchmark of 2,500 public expert-level academic questions (plus a private held-out set) spanning more than 100 disciplinesListed in See also
- GPQAGPQA (Graduate-Level Google-Proof Q&A) is a benchmark of expert-written, four-option multiple-choice questions in biology, physics, and chemistry.Listed in See also
More from See also
More to read
Topics:AI BenchmarksMathematics
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Wikipedia, "American Invitational Mathematics Examination." en.wikipedia.org/...tional_Mathematics_Examination
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12Mathematical Association of America, "MAA Invitational Competitions." maa.org/maa-invitational-competitions
- ^1 ^2 ^3 ^4 ^5 ^6OpenAI, "Learning to reason with LLMs," September 12, 2024. openai.com/...learning-to-reason-with-llms
- ^1 ^2 ^3 ^4IntuitionLabs, "AIME 2025 Benchmark: An Analysis of AI Math Reasoning." intuitionlabs.ai/...aime-2025-ai-benchmark-explained
- ^1 ^2Mathematical Association of America, "2024-25 AIME Thresholds Are Available." maa.org/...aime-thresholds-are-available
- ^1 ^2Wikipedia, "Mathematical Olympiad Program." en.wikipedia.org/...Mathematical_Olympiad_Program
- Art of Problem Solving Wiki, "Mathematical Olympiad Summer Program." artofproblemsolving.com/...Olympiad_Summer_Program
- ^Art of Problem Solving Wiki, "AIME Problems and Solutions." artofproblemsolving.com/..._Problems_and_Solutions
- ^1 ^2 ^3DeepSeek-AI, "DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning," arXiv:2501.12948, January 2025. arxiv.org/...2501.12948v1
- ^OpenAI, o3 announcement, December 20, 2024 (via TechCrunch and InfoQ coverage). techcrunch.com/...openai-announces-new-o3-model ; infoq.com/...openai-announces-o3
- ^OpenAI, "OpenAI o3-mini" announcement and system card, January 2025. openai.com/...openai-o3-mini
- ^1 ^2OpenAI, "Introducing OpenAI o3 and o4-mini," April 16, 2025. openai.com/...introducing-o3-and-o4-mini
- ^xAI, "Grok 3 Beta: The Age of Reasoning Agents," February 17, 2025. x.ai/...grok-3
- ^xAI, Grok 4 launch coverage, July 9, 2025. epoch.ai/...grok-4-math
- ^Google, "Gemini 2.5: Our newest Gemini model with thinking," March 25, 2025. blog.google/...i-model-thinking-updates-march-2025
- ^Anthropic, "Claude Opus 4.5 System Card," November 2025. assets.anthropic.com/...e-Opus-4-5-System-Card.pdf
- ^Anthropic, "Introducing Claude Sonnet 4.5." anthropic.com/...claude-sonnet-4-5
- ^Qwen Team, "QwQ: Reflect Deeply on the Boundaries of the Unknown," November 28, 2024. qwenlm.github.io/...qwq-32b-preview
- ^Qwen Team, "Qwen3 Technical Report," May 2025. arxiv.org/...2505.09388
- ^Artificial Analysis, "AIME 2025 Benchmark Leaderboard." artificialanalysis.ai/...aime-2025
- ^1 ^2xAI, "Grok 4," July 9, 2025. x.ai/...grok-4
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
10 revisions · v10 · 2,720 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (95 claims, 24 sources fetched); 11 material + 11 minor fixed
Cite this page: AI Wiki. "AIME (American Invitational Mathematics Examination)." aiwiki.ai, updated 28 Oct 2026, fact-checked 2 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/aime