

MATH-500
MATH-500 is a 500-problem benchmark for evaluating the mathematical reasoning of large language models, formed by holding out 500 problems from the test split of the MATH benchmark of Dan Hendrycks et al. (2021).[1][8] It was introduced in May 2023 by Hunter Lightman and colleagues at OpenAI in the paper "Let's Verify Step by Step", the same work that released the PRM800K dataset and established process reward models (PRMs) as a viable training signal for mathematical reasoning.[1][2] Because of its small size and clean held-out status, MATH-500 has become the de facto standard short-form math evaluation for reasoning-class language models including OpenAI o1, OpenAI o3, DeepSeek-R1, Gemini 2.5 Pro, and GPT-5.[3][4][5]
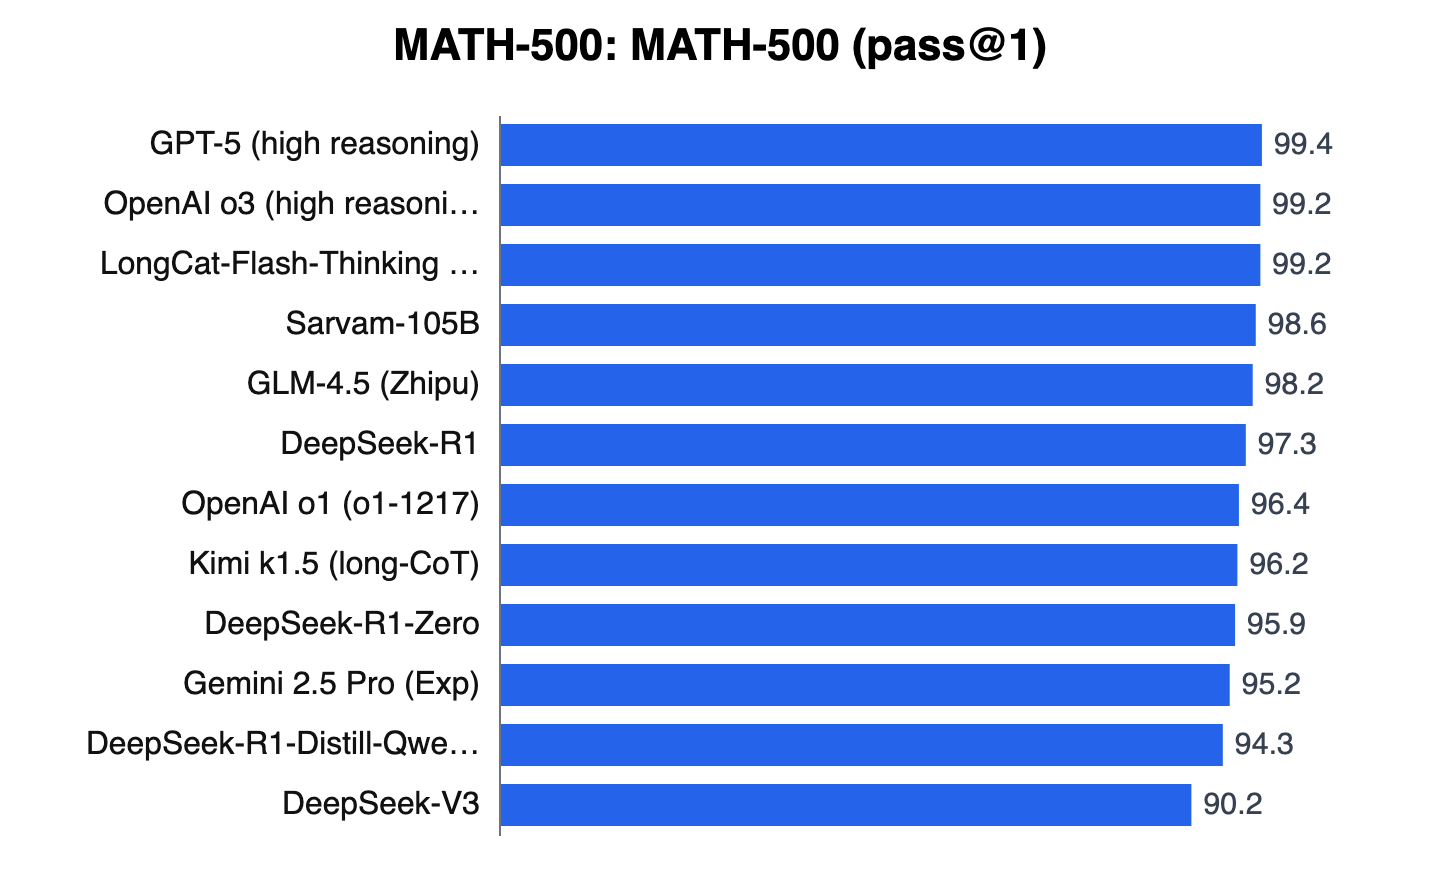
The 500 problems were drawn uniformly at random from the 5,000-problem MATH test set (not stratified by subject or difficulty) and were intended to be "representative of the test set as a whole."[2][4] Although the authors never coined the name in their paper (they simply describe the "remaining 500 held-out problems"), the artifact was adopted by the community (and especially by the Hugging Face dataset card HuggingFaceH4/MATH-500) under the label MATH-500.[3][4] The remaining 4,500 test problems were folded into the training pool used to collect step-level human labels for PRM800K, a redistribution that the authors emphasised was necessary to avoid overfitting in their reward-model training process.[1][4] Today, frontier models routinely score above 95% on MATH-500, which has led Vals AI to archive the benchmark and Artificial Analysis to list it as a legacy evaluation, so it now serves more as a sanity check than as a way to separate frontier models.[5][17]
What is the parent MATH benchmark?
The MATH dataset, introduced in Measuring Mathematical Problem Solving With the MATH Dataset, contains 12,500 competition mathematics problems split into 7,500 training and 5,000 test examples.[8][9] Each problem was drawn from US high-school mathematics competitions including the AMC 10, AMC 12, AIME, and similar olympiad-style events, and each is accompanied by a full step-by-step solution written in a mixture of natural language and LaTeX. The final numerical or symbolic answer is conventionally enclosed in a \boxed{...} macro, which downstream evaluation harnesses still use as the answer-extraction target.[8][10]
The dataset is partitioned along two orthogonal axes:
- Seven subjects: Prealgebra, Algebra, Number Theory, Counting & Probability, Geometry, Intermediate Algebra, and Precalculus.[8][10]
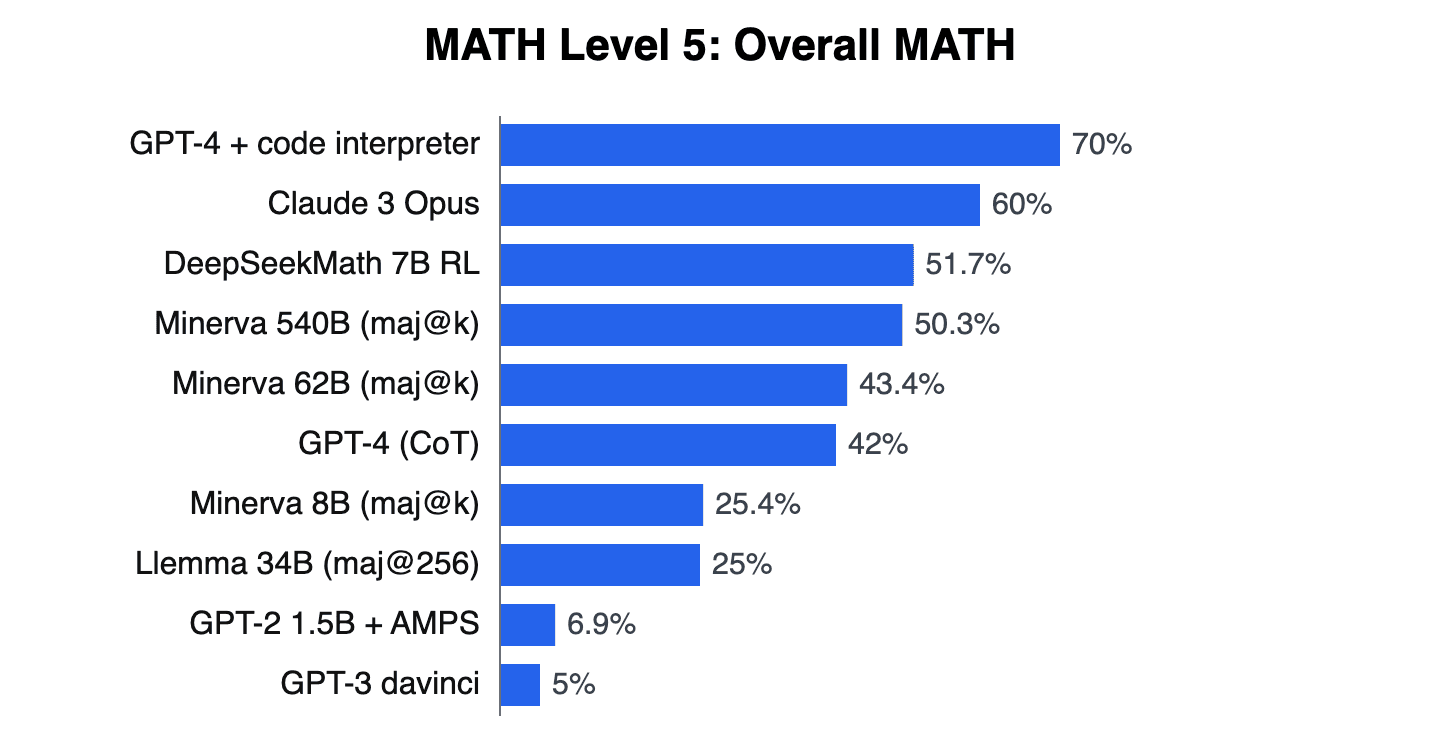
- Five difficulty levels (1 = easiest, 5 = hardest), assigned following the Art of Problem Solving (AoPS) scheme.[8][10] The paper's example is that the first few problems of an AMC 8 exam are often level 1, while AIME problems are level 5 (see MATH Level 5).[8]
The MATH paper was authored by Dan Hendrycks, Collin Burns, Saurav Kadavath, Akul Arora, Steven Basart, Eric Tang, Dawn Song, and Jacob Steinhardt, posted to arXiv on 5 March 2021, and accepted to the NeurIPS 2021 Datasets and Benchmarks track.[8][9] The dataset is released under the MIT license.[10][11]
At launch, frontier models performed catastrophically: the best model reported in the paper (a fine-tuned GPT-2 1.5B) achieved only 6.9% accuracy on the full test set, and few-shot GPT-3 175B reached 5.2%, leading the authors to warn that "simply increasing budgets and model parameter counts will be impractical for achieving strong mathematical reasoning if scaling trends continue."[9] That prediction proved overly pessimistic, partly thanks to the very PRM and reasoning-model techniques that the MATH-500 subset would later help validate.
How was the MATH-500 subset constructed?
The Lightman et al. paper
In Let's Verify Step by Step (arXiv:2305.20050, 31 May 2023), OpenAI researchers Hunter Lightman, Vineet Kosaraju, Yura Burda, Harri Edwards, Bowen Baker, Teddy Lee, Jan Leike, John Schulman, Ilya Sutskever, and Karl Cobbe set out to compare outcome supervision (rewarding only final answers) with process supervision (rewarding individual reasoning steps).[1][12] To train their process reward models, they needed many candidate solutions per problem. They expanded their effective training pool by merging the original MATH train split (7,500 problems) with 4,500 problems drawn from the MATH test split, leaving only 500 problems unseen during PRM training.[2][4]
The README of OpenAI's companion repository, openai/prm800k, states the construction directly: "We selected these 500 test problems uniformly at random, and we believe they are representative of the test set as a whole."[2] It also explains the motivation: "In order to avoid the risk of over-fitting on the 7,500 MATH training problems, we expanded the training set to include 4,500 MATH test split problems."[2] The directory prm800k/math_splits/ contains two Git-LFS files: train.jsonl (the expanded 12,000-problem training set, i.e. 7,500 + 4,500) and test.jsonl (the 500 held-out problems).[2][4] The paper itself uses phrases such as "a representative subset of the MATH test set" rather than the catchier MATH-500 name.[1]
From local artifact to standard benchmark
The Lightman et al. paper's contribution to mathematical reasoning was substantial: their best PRM achieved 78.2% on this held-out subset using best-of-1860 reranking, decisively outperforming outcome-supervised baselines and majority voting.[1][12] But it was the subset itself (not the PRM) that survived as community infrastructure. The conversion was largely operational:
- OpenAI's release. The 500-problem
test.jsonlwas posted to the publicopenai/prm800kGitHub repository alongside the paper.[2] - Hugging Face mirror. In November 2024 the Hugging Face H4 team, the same group behind Zephyr and the Open LLM Leaderboard, repackaged the file as the
HuggingFaceH4/MATH-500dataset, with the 500 records exposed as a singletestsplit with fieldsproblem,solution,answer,subject,level, andunique_id. The dataset card explicitly credits the OpenAI paper as the source.[3] - Adoption in reasoning-model papers. When OpenAI's o1 reasoning model appeared in September 2024, OpenAI's
simple-evalslibrary footnoted that "for newer models (anything on or after o1) we evaluate on MATH-500, which is a newer, IID version of MATH."[7] DeepSeek's R1 paper, Kimi's k1.5 paper, the Qwen and GLM technical reports, and most subsequent reasoning-model launches reported MATH-500 numbers as a top-line metric.[13][14]
Two facts about this trajectory frequently surprise observers. First, the name MATH-500 does not appear in the original Lightman et al. paper at all; it was crystallised by the Hugging Face dataset card and downstream blog posts. Second, the subset is not stratified by difficulty or subject: a quick check of the released test.jsonl shows the expected uniform-sampling distribution across levels 1-5 and across the seven subjects, with the modest sample-size variance one would expect from a 500/5000 random draw.[2][3]
What format and difficulty levels does MATH-500 use?
Each MATH-500 example is a JSON record with the following fields, as documented on the HuggingFaceH4/MATH-500 dataset card:[3]
| Field | Type | Description |
|---|---|---|
problem | string (20-1,730 chars) | Statement of the problem in mixed natural language and LaTeX |
solution | string (45-3,360 chars) | Reference step-by-step solution |
answer | string (1-53 chars) | Final answer in \boxed{...}-extractable form |
subject | string | One of seven subjects (see below) |
level | int | Difficulty level 1-5 (5 = hardest) |
unique_id | string (20-40 chars) | Stable identifier mapping back to the underlying MATH file |
The seven subjects are Prealgebra, Algebra, Intermediate Algebra, Counting & Probability, Number Theory, Geometry, and Precalculus.[3][8] The five difficulty levels follow the original MATH conventions; problems carrying Level 5 are roughly comparable in difficulty to USA(J)MO qualifier-level questions and are the basis of the MATH Lvl 5 sub-benchmark used in Hugging Face's Open LLM Leaderboard v2.
The compact size (500 records, around 450 KB total) is one of the benchmark's most attractive features. A typical chain-of-thought evaluation run takes only minutes on modest hardware, and the dataset is small enough that high-cost reasoning models can be evaluated at full token budget without prohibitive expense.[3]
How is MATH-500 different from the full MATH benchmark?
MATH-500 is widely conflated with the parent MATH dataset, partly because both are colloquially called "MATH" in marketing slides and even in some academic papers. The differences matter:
- Test-set size. MATH-500 contains 500 problems; the full MATH test split contains 5,000. The 500 are a random 10% draw, with the other 4,500 absorbed into Lightman et al.'s expanded training set.[2][4]
- Training-set status. Because 4,500 of the original MATH test problems were re-used for PRM800K training, models trained on PRM800K or distillations thereof can no longer be cleanly evaluated on the original MATH test split. MATH-500 is the only "clean" residual.[1][2]
- Use in evaluation harnesses. Eleuther's
lm-evaluation-harnessexposes bothhendrycks_math(the full 5,000-problem test set) and ahendrycks_math500task that loads the Hugging Face MATH-500 mirror, allowing researchers to choose which they want.[15] - Headline scoring conventions. OpenAI's
simple-evalsreports a singleMATHcolumn for every model, but for o1 and later that column is actually MATH-500.[7] DeepSeek, Kimi, Qwen, and Anthropic typically use the MATH-500 label explicitly.[13][14]
This convention has caused confusion. For instance, OpenAI's Learning to Reason with LLMs page (September 2024) reports o1 at 94.8% on "MATH", but a footnote says the evaluation used the same 500-problem test split as Lightman et al.; the released o1 is listed at 96.4% in simple-evals, whose MATH column switches to MATH-500 for o1 and later models.[7][30] DeepSeek-R1's headline "97.3% on MATH" is also on MATH-500 (pass@1), as their paper makes explicit in Table 4.[13]
Why did MATH-500 become standard for reasoning evaluation?
Several factors combined to elevate this otherwise unremarkable random-sample dataset into a reasoning-era benchmark:
- Cost-efficient evaluation of test-time-compute models. Reasoning models such as o1, o3, R1, and Gemini-2.5-Pro can spend tens or hundreds of thousands of tokens per problem. A 500-problem test set is the smallest one can run while still producing a statistically meaningful number (about ±2.6 percentage points 95% CI at the 90% accuracy level). The full 5,000-problem MATH set is roughly 10x more expensive to run at high reasoning depth.[16][17]
- No leakage into the original MATH train split. Because Lightman et al. moved 4,500 problems out of the MATH test set, any model trained on the standard MATH train split is, by construction, "untouched" by MATH-500. This made it a natural held-out evaluation for the burgeoning crop of math-specific finetuned models.[1][4]
- Easy-to-parse answer format. All answers are wrapped in
\boxed{...}, and the PRM800K repository provides a grader (grader.py, deliberately conservative) that handles algebraic equivalence, a non-trivial problem in math evaluation.[2][18] - Frontier-lab uptake. Once OpenAI evaluated o1 on the 500-problem split (and named it MATH-500 in
simple-evals), the label cascaded through every subsequent reasoning-model release. DeepSeek-R1, Kimi k1.5, Qwen2.5-Math, GLM-4.5, Nemotron-Nano, LongCat-Flash, Sarvam, and almost every open-weights reasoning checkpoint shipped a MATH-500 number from 2024 onward.[13][14][6]
How do models score on MATH-500?
The benchmark has saturated quickly. A non-exhaustive timeline drawn from primary sources:
| Date | Model | MATH-500 (pass@1) | Source |
|---|---|---|---|
| May 2023 | GPT-4 + best-of-1860 PRM | 78.2% | Lightman et al. (Fig. 3)[1] |
| Apr 2024 | GPT-4-turbo-2024-04-09 | 73.4% (full MATH, not MATH-500) | Reported via simple-evals[7] |
| May 2024 | GPT-4o (2024-05-13) | 74.6% | DeepSeek-R1 Table 4[13] |
| Aug 2024 | GPT-4o (2024-08-06) | 75.9% (full MATH, not MATH-500) | OpenAI simple-evals[7] |
| Sep 2024 | OpenAI o1-mini | 90.0% | DeepSeek-R1 Table 4[13] |
| Dec 2024 | OpenAI o1 (o1-1217) | 96.4% | OpenAI simple-evals[7][13] |
| Oct 2024 | Claude 3.5 Sonnet (2024-10-22) | 78.3% | DeepSeek-R1 Table 4[13] |
| Dec 2024 | DeepSeek-V3 | 90.2% | DeepSeek-R1 Table 4[13] |
| Jan 2025 | DeepSeek-R1-Zero | 95.9% | DeepSeek-R1 paper[13] |
| Jan 2025 | DeepSeek-R1 | 97.3% | DeepSeek-R1 paper[13] |
| Jan 2025 | Kimi k1.5 (long-CoT) | 96.2% | Kimi k1.5 technical report[14] |
| Jan 2025 | DeepSeek-R1-Distill-Qwen-32B | 94.3% | DeepSeek-R1 Table 5[13] |
| Mar 2025 | Gemini 2.5 Pro (Exp) | 95.2% | Vals AI independent evaluation[17] |
| 2025 | OpenAI o3 (high reasoning) | 99.2% | Artificial Analysis leaderboard[5] |
| 2025 | GPT-5 (high reasoning) | 99.4% | Artificial Analysis leaderboard[5] |
| 2025 | LongCat-Flash-Thinking (Meituan) | 99.2% | llm-stats leaderboard[6] |
| 2025 | GLM-4.5 (Zhipu) | 98.2% | llm-stats leaderboard[6] |
| Mar 2026 | Sarvam-105B | 98.6% | Sarvam (self-reported)[28]; llm-stats leaderboard[6] |
The headline result that crystallised MATH-500 as a frontier metric was DeepSeek-R1's January 2025 launch: the open-weights model scored 97.3% pass@1, edging out OpenAI o1-1217 at 96.4% and bringing the benchmark to near-saturation in the public eye.[13] Independent re-evaluation by Vals AI, as of its 9 January 2026 update, put Gemini 3 Pro first at 96.4%, followed by Grok 4 (96.2%) and GPT-5 (96.0%); the platform has since archived the benchmark, saying that "performance on this benchmark has saturated."[17]
Is MATH-500 saturated?
By every reasonable measure, MATH-500 is saturated for frontier models. As of November 2026, the llm-stats leaderboard tracks 33 models with an average of 0.933; the leader (LongCat-Flash-Thinking, 0.992) is about 6 points above that mean, and the top three are within 1 point of each other.[6] Artificial Analysis has benchmarked 202 models on MATH-500 but now lists it as a legacy evaluation outside its current Intelligence Index, while aggregators such as BenchLM fold it into math composites dominated by harder sets such as AIME, HMMT, BRUMO and FrontierMath.[5][16]
Several knock-on effects of this saturation are now visible:
- Retirement. Vals AI has archived MATH-500 (its final leaderboard update is dated 9 January 2026) and no longer tests new models on it.[17]
- Replacement by harder benchmarks. AIME 2024, AIME 2025, FrontierMath, HMMT 2025, USAMO, Putnam, and HLE (Humanity's Last Exam) now occupy the "hard math" slot in flagship system cards.[16][20]
- Compound metrics. BenchLM's math category combines MATH-500 with AIME, HMMT, USAMO, BRUMO and FrontierMath results, so MATH-500 is one minor input among harder contests.[16]
A small number of frontier vendors still report MATH-500 prominently, including Zhipu, NVIDIA, Meituan, Moonshot AI, Sarvam, and most small-model labs, because it remains a useful checkpoint metric and because matching o1 / R1 on MATH-500 is still a strong baseline claim.[6]
Is MATH-500 affected by data contamination?
MATH-500 is drawn from publicly available competition mathematics problems (AMC 10, AMC 12, AIME, etc.) that have been indexed, discussed, and solved on the open web, including Art of Problem Solving forums, contest archives, and innumerable solution blog posts. This visibility was already a worry for the parent MATH dataset; multiple surveys document that MATH (Hendrycks et al.) is among the most contaminated of widely used LLM benchmarks, alongside GSM8K, HumanEval, and MMLU.[21][22]
Specific concerns:
- Self-disclosure by OpenAI. OpenAI's GPT-4 Technical Report acknowledges mixing data from the MATH and GSM8K training sets into GPT-4's training; once one is comfortable training on the train split, the boundary between train and test (which contains MATH-500) becomes statistical rather than absolute.[29]
- Public solutions. Because problems originate from Art of Problem Solving and similar sites that publish worked solutions, any internet-scale crawl will incidentally encounter the test problems and their answers. The PRM800K license does not restrict this distribution.[2][11]
- Vals AI warning. The independent Vals AI evaluation notes that because the benchmark "is public, and been out for several years, it does raise questions if the models have been pre-trained on the test data."[17]
- Robustness evidence from MATH-Perturb. Huang et al.'s MATH-Perturb benchmark (ICML 2025) constructs 279 hand-perturbed variants of MATH Level 5 problems. Frontier reasoning models suffer 10-25 point drops on the "hard perturbation" variants, including o1-mini (-16.49) and Gemini 2.0 Flash Thinking (-12.9), suggesting that some of the headline MATH-500 score on Level 5 reflects memorisation rather than pure reasoning.[23][24]
These factors complicate inter-model comparisons even at the 90%+ tier. They are partly why benchmarks designed against contamination, such as FrontierMath (held-out problems written by professional mathematicians) and MathArena (real-time contests evaluated within hours of release), have grown in importance.[16][25]
How does MATH-500 compare to related benchmarks?
| Benchmark | Size (test) | Source | Typical 2025 SOTA | Saturated? |
|---|---|---|---|---|
| MATH-500 | 500 | MATH test split (Lightman 2023)[1] | 99% (GPT-5 high)[5] | Yes[17] |
| MATH (full) | 5,000 | Hendrycks 2021[8] | Rarely reported for frontier models (labs report MATH-500 instead)[7] | Largely[17] |
| GSM8K | 1,319 | Cobbe et al. 2021[26] | High 90s (frontier models)[26] | Yes[26] |
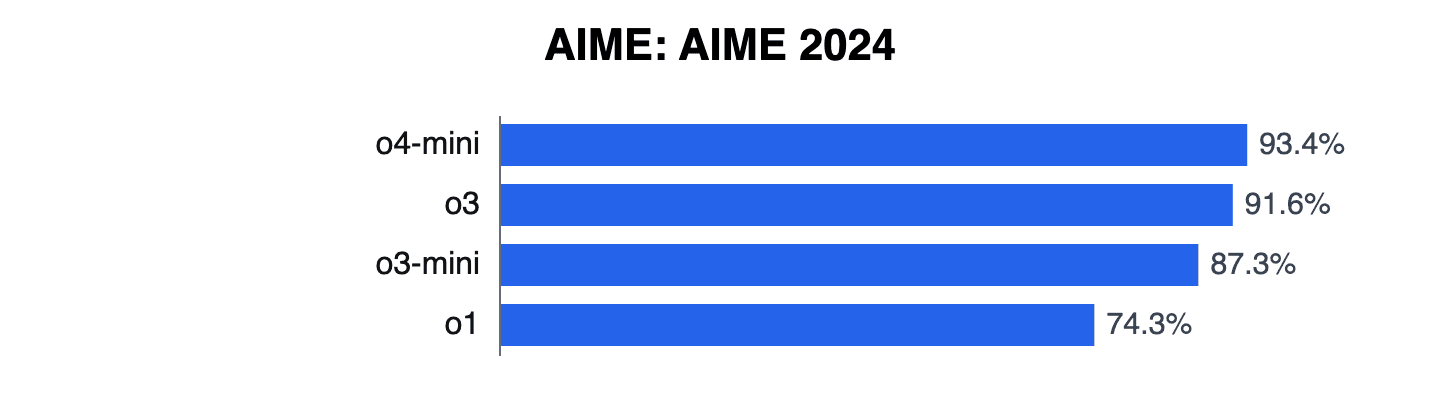
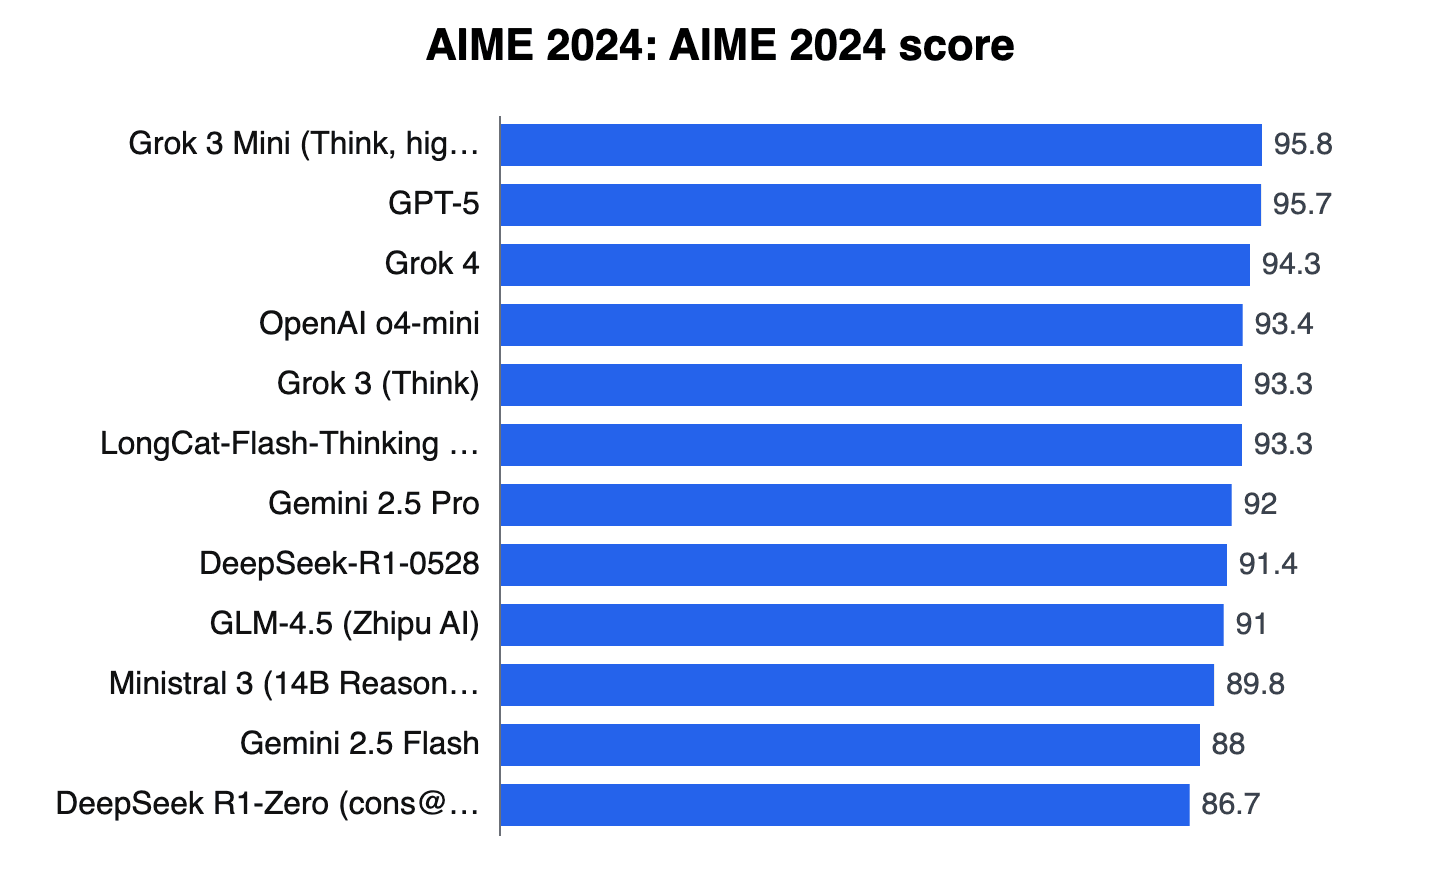
| AIME 2024 | 30 | AIME 2024 contest | approx. 90% (o3, R1)[16] | Approaching |
| AIME 2025 | 30 | AIME 2025 contest | 92-100% (GPT-5, Gemini 2.5 Pro)[16] | Approaching |
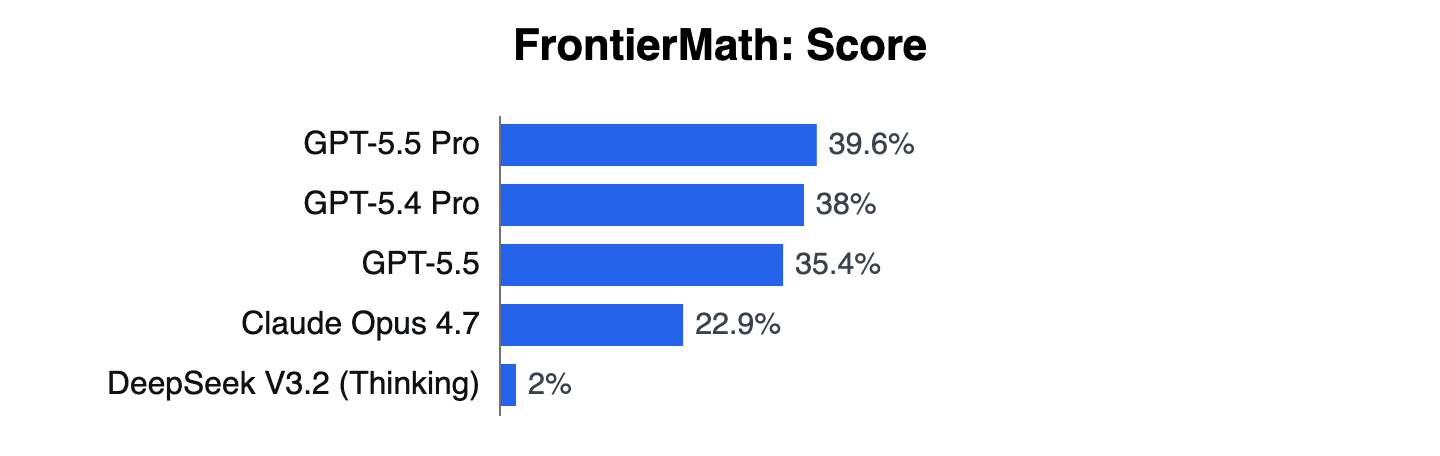
| FrontierMath | 338 (v2, June 2026) | Held-out problems by approx. 60 mathematicians[25] | Under 2% at launch (Nov 2024)[25]; about 90% on v2 Tiers 1-3 by late 2026[31] | Approaching (Tiers 1-3)[31] |
| MATH-Perturb-Hard | 279 | Perturbations of MATH Level 5[23] | drops 10-25 pts vs. MATH[23] | No |
Versus GSM8K. GSM8K is grade-school arithmetic word problems, deliberately constrained to addition, subtraction, multiplication, and division over natural numbers; SOTA models score in the high 90s and have for years.[26] MATH-500 is harder by roughly a full difficulty tier; Lightman et al. used precisely this gap (between trivial GSM8K performance and weaker MATH performance) to motivate their work on process supervision.[1] In practice, modern reasoning models now saturate both.
Versus AIME 2024/2025. AIME is a 15-problem high-school invitational; "AIME 2024" and "AIME 2025" in LLM evaluation usage typically refer to the 30 problems from both AIME I and AIME II of the given year, with cons@k or pass@k scoring. AIME problems are individually harder than the median MATH-500 problem (MATH Level 5 problems are AIME-derived, but constitute only about 27% of the 500, 134 problems), so AIME serves as the natural "harder" successor.[16][27]
Versus FrontierMath. Epoch AI's FrontierMath benchmark, introduced in late 2024, is a fundamentally different scale: 338 problems in its June 2026 v2 release, written and held in secret by professional research mathematicians, problems that take human experts hours to days. Models solved under 2% at launch, but by late 2026 third-party trackers listed top systems near 90% on the v2 Tiers 1-3 set.[25][31]
Versus MATH-Perturb. MATH-Perturb (Huang et al., ICML 2025) constructs 279 hard- and 279 simple-perturbed problems by editing MATH Level 5 originals. The authors read the drops on hard perturbations as evidence of a form of memorization, in which models apply learned solution patterns without checking whether they still fit the modified problem.[23][24]
What is MATH-500's ongoing role?
Despite saturation, MATH-500 still appears in nearly every reasoning-model release in 2025. The reasons are pragmatic: it is cheap, well-tooled (PRM800K grader is the de facto evaluator), and offers comparability with hundreds of prior published scores. As of November 2026, the HuggingFaceH4/MATH-500 dataset shows roughly 190,000 downloads per month and is listed as a training/evaluation dataset by about 150 models on the Hub.[3]
Several caveats remain in serious use of the benchmark:
- Use the PRM800K grader. Naive string-equality grading systematically under-counts correct answers because of LaTeX surface variation. The OpenAI grader (
prm800k/grading/grader.py) is the conventional choice and handles algebraic equivalence, fraction normalisation, and other surface variation.[2][18] - Report greedy / pass@1 unless you specify otherwise. Older numbers using majority voting (Maj@k) or PRM reranking (best-of-N) are not directly comparable to greedy pass@1 numbers reported by recent reasoning-model releases.[7][1]
- Disambiguate "MATH" in claims. Especially in headline numbers, papers and blog posts frequently say "MATH" when they mean MATH-500. The distinction matters when comparing across groups; checking the cited file path or the score range (above approx. 95% generally implies MATH-500) is a useful heuristic.
For most practical purposes, MATH-500's role has shifted from a discriminating benchmark to a floor: a reasoning model that does not clear approx. 90% on MATH-500 is not yet a frontier reasoning model. Discriminative comparison has migrated to AIME, USAMO, FrontierMath, and HLE.[16][25]
Continue reading
- MATHthe parent datasetMentioned 119 times above
- AIME (American Invitational Mathematics Examination)The American Invitational Mathematics Examination (AIME) is a 15-question, 3-hour mathematics competition for high school students in the United States and CanadaMentioned 21 times above
- FrontierMathFrontierMath is an advanced mathematical reasoning benchmark created by Epoch AI in collaboration with over 60 expert mathematicians, including Fields Medalists Terence Tao, Timothy Gowers, and Richard…Mentioned 8 times above
- GSM8Kthe grade-school counterpart often paired with MATHMentioned 6 times above
- MATH Level 5the hardest difficulty stratum of MATH and MATH-500Mentioned 5 times above
- AIME 2024AIME 2024 is an AI benchmark of 30 problems drawn from the 2024 American Invitational Mathematics Examination that has become the standard yardstick for measuring the mathematical reasoning of large language…Mentioned 5 times above
More to read
- Reasoning models
- AIME 2025
- Process reward model (PRM): the technique introduced alongside MATH-500
- MathArena
- Chain-of-Thought
- Test-time compute
Topics:AI BenchmarksMathematics
See also
- MATH benchmark: the parent dataset
- MATH Level 5: the hardest difficulty stratum of MATH and MATH-500
- Process reward model (PRM): the technique introduced alongside MATH-500
- GSM8K: the grade-school counterpart often paired with MATH
- AIME, AIME 2024, AIME 2025: the harder successors
- FrontierMath: research-level held-out math benchmark
- MathArena: contamination-resistant contest-time evaluation
- Reasoning models: the class of models that drove MATH-500 adoption
- Chain-of-thought: the prompting / training paradigm MATH-500 evaluates
- Test-time compute: the scaling axis MATH-500 most cleanly measures
References
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12Lightman, H., Kosaraju, V., Burda, Y., Edwards, H., Baker, B., Lee, T., Leike, J., Schulman, J., Sutskever, I., & Cobbe, K. (2023). *Let's Verify Step by Step.* arXiv preprint arXiv:2305.20050. <arxiv.org/...2305.20050>
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13OpenAI. *prm800k* GitHub repository, README and `math_splits/` documentation. <github.com/...prm800k>
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Hugging Face dataset card, *HuggingFaceH4/MATH-500*. <huggingface.co/...MATH-500>
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8OpenAI. *prm800k* README quote: "We selected these 500 test problems uniformly at random." <github.com/...prm800k>
- ^1 ^2 ^3 ^4 ^5 ^6Artificial Analysis. *MATH-500 Benchmark Leaderboard.* <artificialanalysis.ai/...math-500>
- ^1 ^2 ^3 ^4 ^5 ^6llm-stats.com. *MATH-500 Benchmark Leaderboard.* <llm-stats.com/...math-500>
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8OpenAI. *simple-evals* GitHub repository, README footnote on MATH / MATH-500 usage. <github.com/...simple-evals>
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9Hendrycks, D., Burns, C., Kadavath, S., Arora, A., Basart, S., Tang, E., Song, D., & Steinhardt, J. (2021). *Measuring Mathematical Problem Solving With the MATH Dataset.* arXiv:2103.03874; NeurIPS 2021 Datasets and Benchmarks. <arxiv.org/...2103.03874>
- ^1 ^2 ^3arXiv listing for *Measuring Mathematical Problem Solving With the MATH Dataset.* <arxiv.org/...2103.03874>
- ^1 ^2 ^3 ^4Hugging Face dataset card, *hendrycks/competition_math.* <huggingface.co/...competition_math>
- ^1 ^2hendrycks/math GitHub repository (LICENSE: MIT). <github.com/...math>
- ^1 ^2Lightman et al. 2023, abstract and §3.3; process supervision results on the held-out subset. <arxiv.org/...2305.20050>
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9 ^10 ^11 ^12 ^13DeepSeek-AI. (2025). *DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning.* arXiv:2501.12948, Tables 4 & 5. <arxiv.org/...2501.12948v1>
- ^1 ^2 ^3 ^4Kimi Team. (2025). *Kimi k1.5: Scaling Reinforcement Learning with LLMs.* arXiv:2501.12599. <arxiv.org/...2501.12599v1>
- ^EleutherAI. *lm-evaluation-harness* `hendrycks_math` task README. <github.com/...README.md>
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8 ^9BenchLM.ai. *Math Benchmarks 2026: AIME, HMMT, MATH-500 LLM Scores.* <benchlm.ai/math>
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Vals AI. *MATH 500 Benchmark.* <vals.ai/...math500-04-15-2025>
- ^1 ^2PRM800K repository, `prm800k/grading/` directory. <github.com/...prm800k>
- Independent leaderboards referencing Gemini 2.5 Pro MATH-500 score (approx. 97%). <llm-stats.com/...math-500>
- ^Epoch AI. *FrontierMath.* <epoch.ai/frontiermath>
- ^Survey of contamination methods in LLMs. arXiv:2404.00699. <arxiv.org/...2404.00699v4>
- ^Awesome Data Contamination paper list (lyy1994). <github.com/...awesome-data-contamination>
- ^1 ^2 ^3 ^4Huang, K. et al. (2025). *MATH-Perturb: Benchmarking LLMs' Math Reasoning Abilities against Hard Perturbations.* arXiv:2502.06453. <arxiv.org/...2502.06453>
- ^1 ^2MATH-Perturb project page. <math-perturb.github.io>
- ^1 ^2 ^3 ^4 ^5Glazer et al. (2024). *FrontierMath: A Benchmark for Evaluating Advanced Mathematical Reasoning in AI.* arXiv:2411.04872. <arxiv.org/...2411.04872>
- ^1 ^2 ^3 ^4Verity AI. *GSM8K & MATH: Benchmarking Mathematical Reasoning.* <verityai.co/...h-benchmarks-mathematical-reasoning>
- ^Intuition Labs. *AIME 2025 Benchmark: An Analysis of AI Math Reasoning.* <intuitionlabs.ai/...aime-2025-ai-benchmark-explained>
- ^Sarvam AI. *Open-Sourcing Sarvam 30B and 105B.* March 6, 2026. <sarvam.ai/...sarvam-30b-105b>
- ^OpenAI. (2023). *GPT-4 Technical Report*, Appendix E. arXiv:2303.08774. <arxiv.org/...2303.08774>
- ^OpenAI. (2024, September 12). *Learning to Reason with LLMs*, footnote 2. <openai.com/...learning-to-reason-with-llms>
- ^1 ^2 ^3BenchLM.ai. *FrontierMath v2 Tiers 1-3 leaderboard* (updated November 4, 2026). <benchlm.ai/...frontiermathv2tiers13>
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
12 revisions by 1 contributor · v12 · 3,820 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independent fact-check of the full article against its cited sources (110 claims, 30 sources fetched); 13 material + 18 minor fixed
Cite this page: AI Wiki. "MATH-500." aiwiki.ai, updated 28 Oct 2026, fact-checked 5 Nov 2026. CC BY 4.0. https://aiwiki.ai/wiki/math_500