

Best AI Models for Reasoning and Math
As of July 2026, the strongest general reasoning models are Anthropic's Claude Opus 4.8 and Claude Fable 5, OpenAI's GPT-5.5, and Google's Gemini 3.1 Pro and Gemini 3 Pro in its Deep Think mode, which trade the top spot depending on the task [1][2][3]. Claude Fable 5 leads the composite Artificial Analysis Intelligence Index and posts the highest Humanity's Last Exam score; GPT-5.5 and Qwen3-Max-Thinking report perfect AIME math results; and on the ARC Prize Foundation's leaderboard (checked October 2026) Claude Fable 5 has the highest ARC-AGI-2 abstract-reasoning score of the models compared here, with GPT-5.5 and Gemini 3 Deep Think close behind [2][4][5][6][24]. For open weights, GLM-5.2 and DeepSeek V4 (V4-Pro) are the reasoning leaders [7][8]. Because AIME and MATH-500 are now saturated, the benchmarks that still separate the frontier are GPQA Diamond, Humanity's Last Exam (HLE), and ARC-AGI-2.
This page ranks models by measured reasoning and math performance. For how these "thinking" models actually work (chain-of-thought, test-time compute, verifier training), see the reasoning model concept page.
The reasoning leaderboard at a glance
Last verified: July 2026. AIME = AIME 2025, pass@1, no tools, unless marked with a dagger for AIME 2026 or "wt" for with tools. GPQA Diamond, HLE and ARC-AGI-2 are percentages. MATH-500 is saturated and has been dropped from 2026 launch reports (shown as n/r). ARC-AGI-2 values are the ARC Prize Foundation's semi-private scores as listed on its leaderboard on 27 October 2026, at the highest reasoning setting shown for each model. HLE is the no-tools score. "n/r" means not reported by a source we could verify (never a zero).
| Model | Developer | AIME | GPQA Diamond | MATH-500 | ARC-AGI-2 | HLE | Access |
|---|---|---|---|---|---|---|---|
| Claude Fable 5 | Anthropic | n/r | ~94 (sat.) | n/r | 89.2 | 53.0 | Proprietary |
| Claude Opus 4.8 | Anthropic | 98.3 | 93.6 | n/r | 72.1 | 49.8 | Proprietary |
| GPT-5.5 | OpenAI | 100 | 93.5 | n/r | 85.0 | 41.4 | Proprietary |
| Claude Opus 4.7 | Anthropic | n/r | 94.2 | n/r | 75.8 | 46.9 | Proprietary |
| Gemini 3.1 Pro | Google DeepMind | n/r | 94.3 | n/r | 77.1 | 44.4 | Proprietary |
| Gemini 3 Pro (Deep Think) | Google DeepMind | n/r | 93.8 | n/r | 84.6 | 48.4 | Proprietary |
| Gemini 3 Pro (base) | Google DeepMind | 95 | 91.9 | n/r | 31.1 | 37.5 | Proprietary |
| GLM-5.2 | Z.ai | 99.2† | 91.2 | n/r | 22.8 | 40.5 | Open (MIT) |
| Qwen3.7-Max | Alibaba | n/r | 92.4 | n/r | n/r | 41.4 | Proprietary |
| Kimi K2.6 | Moonshot AI | 96.4† | 90.5 | n/r | n/r | 34.7 | Open (Mod. MIT) |
| DeepSeek V4-Pro | DeepSeek | n/r | 90.1 | n/r | n/r | 37.7 | Open (MIT) |
| Grok 4.3 | xAI | n/r | 90.1 | n/r | n/r | 35.0 | Proprietary |
| Qwen3-Max-Thinking | Alibaba | 100 wt | 87.4 | n/r | n/r | 30.2 | Proprietary |
| MiniMax M2 | MiniMax | 78 | 78 | n/r | n/r | 12.5 | Open (Mod. MIT) |
Sources: AA Intelligence Index and independent evals [1][2][9]; Anthropic system cards for Opus 4.8/4.7 [3][10]; OpenAI and Vellum transcription for GPT-5.5 [5][11]; Google model cards for the Gemini line [6][12][13]; DeepSeek, Moonshot, Z.ai, Qwen, MiniMax model cards [7][8][14][15][16]; ARC Prize verified scores [4][17].
Which AI model is best for reasoning right now?
On the composite Artificial Analysis Intelligence Index (updated July 7, 2026), the order at the top is Claude Fable 5 first, Claude Opus 4.8 second, and GPT-5.5 third, with Anthropic holding two of the top three slots [1][2]. Claude Fable 5, the general-availability edition of Anthropic's "Mythos" class released on June 9, 2026, launched at number one and is the first model to clear 53% on Humanity's Last Exam, more than seven points ahead of the next model [2]. Opus 4.8 (released May 28, 2026) is the strongest widely deployed flagship, and GPT-5.5 (April 2026) is OpenAI's leading reasoning model and the top scorer on the agentic side of the index [1][5].
No single model wins every reasoning task, so the honest answer is a per-use-case ranking.
Which model is best for the hardest math?
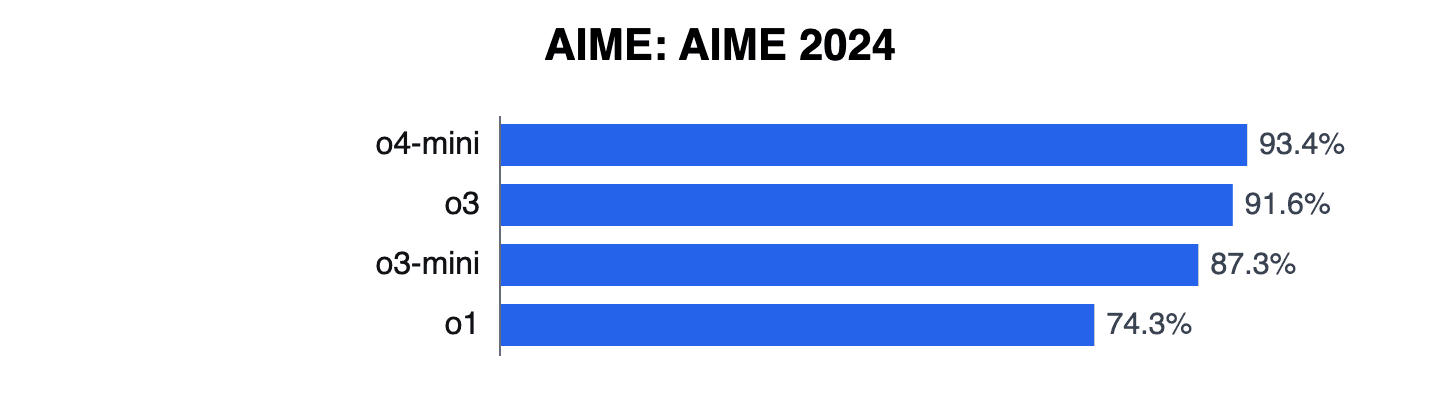
AIME 2025 is effectively solved: GPT-5.5, GPT-5.2, Qwen3-Max-Thinking and (with tools) Grok 4 and Kimi K2 Thinking all report 100%, and most 2026 launches have simply stopped listing it [5][14][18][19]. The newest open models report AIME 2026 instead, where GLM-5.2 scores 99.2% and Kimi K2.6 scores 96.4%, again near the ceiling [7][8]. Because the exam is saturated, it no longer separates the leaders.
For math that still discriminates, the differentiators are harder olympiad sets and FrontierMath. GPT-5.5 leads here, reporting roughly 51.7% on FrontierMath tiers 1 to 3 and 35.4% on the research-level tier 4, and Gemini 3 Pro reaches 100% on AIME 2025 only when allowed to run code [5][12]. The verdict: for the hardest math, GPT-5.5 and Gemini 3 Pro in Deep Think mode are the strongest, with Qwen3-Max-Thinking the best proprietary Chinese option and GLM-5.2 the best open-weight math model.
Which model is best for graduate-level science?
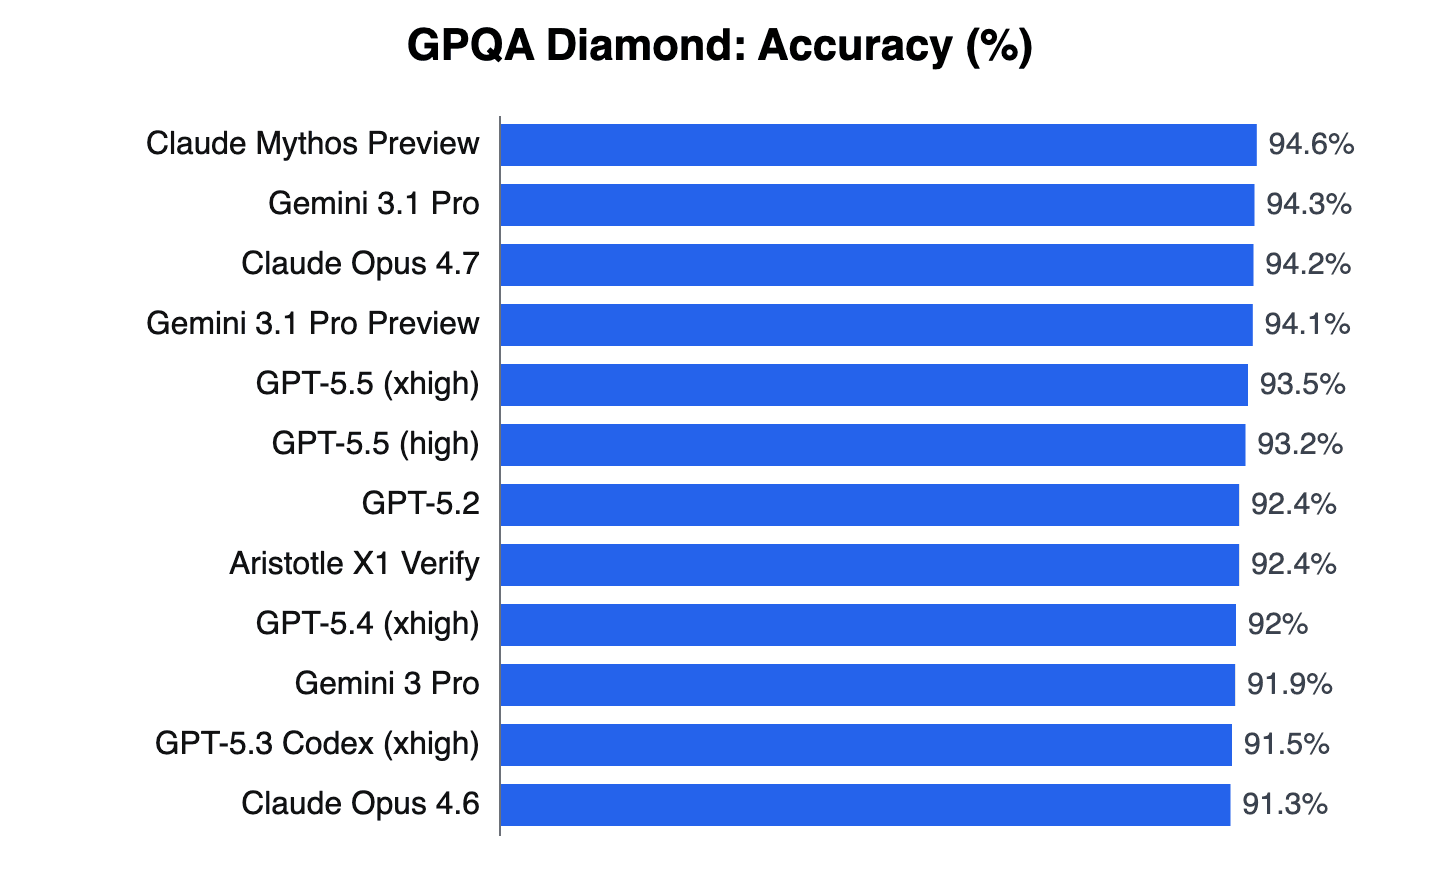
Two benchmarks matter here: GPQA Diamond (Google-proof graduate science multiple choice) and HLE (thousands of expert-written frontier questions across dozens of fields). GPQA Diamond is now near saturation: the frontier clusters between 91% and 95%, well above the roughly 70% scored by human PhDs in their own field [17][20]. The current GPQA Diamond leaders are Gemini 3.1 Pro at 94.3%, Claude Opus 4.7 at 94.2%, Gemini 3 Deep Think at 93.8%, and Opus 4.8, GPT-5.5 and Grok 4.3 in a tight band near 93.5% [3][5][12][13].
HLE is the tougher, less saturated science and knowledge test, and here Anthropic leads: Claude Fable 5 scores 53.0% and Claude Opus 4.8 scores 49.8% with no tools, ahead of Gemini 3 Deep Think at 48.4% and Gemini 3.1 Pro at 44.4% [2][3][6][13]. On Scale's independent no-tools harness, Gemini 3.1 Pro tops the public board at about 46.4% [9]. With tools enabled, Opus 4.8 rises to 57.9%, the highest verified with-tools result [3]. The verdict: for graduate science, Claude Opus 4.8 and Claude Fable 5 lead on HLE, while Gemini 3.1 Pro edges the GPQA Diamond ranking.
Which model is best for abstract and novel reasoning?
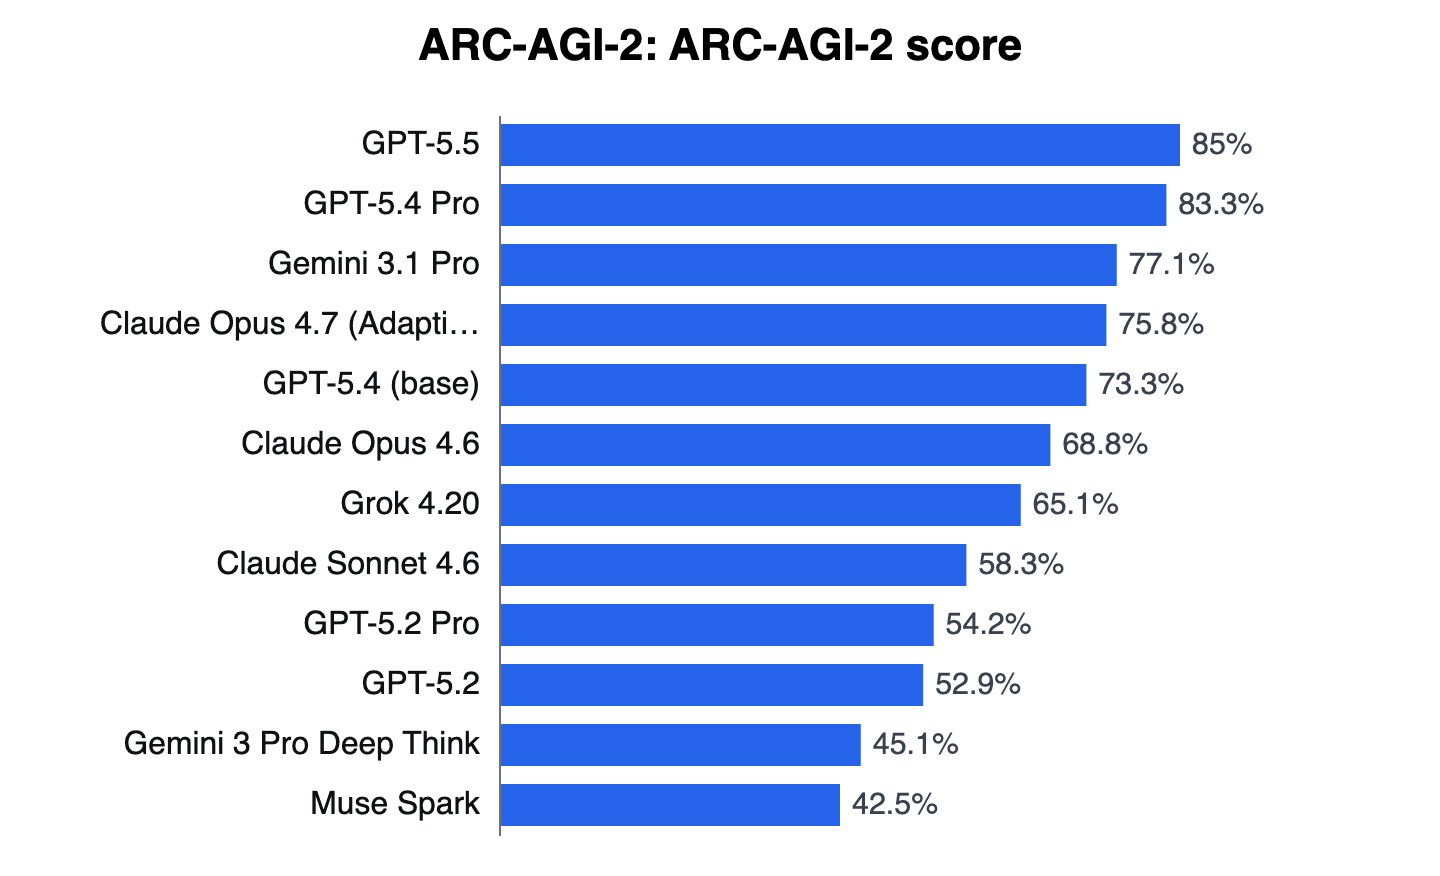
ARC-AGI-2 is the benchmark built to resist memorization: novel visual puzzles where humans average around 60% but 2025-era models scored under 20%. Scores on the ARC Prize Foundation's semi-private evaluation rose steeply during 2026. Among the models in the table above, the foundation's leaderboard (checked 27 October 2026) lists Claude Fable 5 at 89.2% at its max setting, GPT-5.5 at 85.0% at xhigh, the February 2026 version of Gemini 3 Deep Think at 84.6%, Gemini 3.1 Pro (preview) at 77.1%, Claude Opus 4.7 at 75.8% at max, and Claude Opus 4.8 at 72.1% at high [24]. Earlier entries were far lower: a preview of Gemini 3 Deep Think scored 45.1%, Claude Opus 4.5 Thinking 37.6%, Gemini 3 Flash 33.6% and Gemini 3 Pro base 31.1%; Grok 4 reached 15.9% and GPT-5 reached 9.9% [4][10][17][24]. A refinement system from Poetiq built on Gemini 3 Pro scored 54%, but it is a scaffolded system rather than a single model [10]. Models released after July 2026 score higher still; GPT-6 Astra, for example, is listed at 95.0% at its max setting [24]. The verdict: among the models compared here, Claude Fable 5 has the highest ARC-AGI-2 score, with GPT-5.5 and Gemini 3 Deep Think close behind.
An important caveat: ARC-AGI-2 scores depend heavily on the reasoning-effort setting. The ARC Prize Foundation lists several settings for most models; Claude Opus 4.7, for example, ranges from 62.1% at low effort to 75.8% at max, and GPT-5.5 from 33.3% at low to 85.0% at xhigh [24]. The 85.0%, 77.1% and 75.8% figures for GPT-5.5, Gemini 3.1 Pro and Claude Opus 4.7 are the foundation's own semi-private results, not public-set self-reports [24]. Results on the public evaluation set are a different measurement from semi-private scores [21]. Treat any single "ARC-AGI-2" percentage that does not state its evaluation set and effort setting as unreliable.
Which is the best open-weight reasoning model?
Open weights have closed much of the gap. GLM-5.2 from Z.ai (Zhipu, MIT license, released June 2026) is the highest-scoring open model on the Artificial Analysis Intelligence Index and posts 91.2% GPQA Diamond, 99.2% AIME 2026, and 40.5% HLE (54.7% with tools) [8]. DeepSeek V4-Pro (MIT license, April 2026, a 1.6-trillion-parameter mixture-of-experts model with 49B active and 1M context) is close behind at 90.1% GPQA Diamond and 37.7% HLE, and far cheaper to run [7][22]. Kimi K2.6 from Moonshot AI scores 90.5% GPQA Diamond and a strong 54.0% HLE with tools [14]. The verdict: GLM-5.2 is the best open reasoning model overall, with DeepSeek V4-Pro the best open value and Kimi K2.6 the strongest tool-using open model. Note that Alibaba's Qwen3.7-Max and Qwen3-Max-Thinking are strong reasoners but are proprietary, API-only, and not open weight [15][16].
Which reasoning model is the best value?
Among open models, DeepSeek V4-Pro delivers frontier-adjacent reasoning at about $0.44 per million input and $0.87 per million output tokens, and its smaller V4-Flash sibling runs near $0.14 in and $0.28 out, the cheapest capable reasoner here [7][22]. MiniMax M2 (about $0.30 in, $1.20 out) is another low-cost open option, though its 78% AIME and GPQA place it a tier below [16]. Among proprietary models, Grok 4.3 from xAI is priced aggressively at $1.25 in and $2.50 out while scoring around 90% GPQA Diamond [23]. The verdict: DeepSeek V4-Pro is the best value for top-tier reasoning, and Grok 4.3 is the best-value proprietary option.
How should you read these scores?
Three cautions apply to every number above. First, saturation: AIME 2025 and MATH-500 are essentially solved and have been retired from most 2026 model cards, so a perfect AIME score no longer signals a leader. GPQA Diamond is close behind, with the frontier compressed into a two-point band above human-expert level [17][20]. HLE and ARC-AGI-2 are the remaining benchmarks with real spread. Second, tools versus no tools: with-tools scores (code execution, search) run 5 to 15 points higher than no-tools scores on HLE and AIME, so only compare like with like. Third, self-report versus independent: launch-day figures are provider self-reports; independent trackers such as Artificial Analysis, Scale and Epoch AI often measure a few points lower, and ARC-AGI-2 results on the public evaluation set are not the same measurement as the ARC Prize Foundation's semi-private scores [4][9][20][21]. Scores in this fast-moving field change monthly; this page was verified in July 2026, and its ARC-AGI-2 figures were updated in October 2026.
Continue reading
- Gemini 3Gemini 3 is the third major generation of the Gemini family of multimodal models from Google DeepMind, launched on November 18, 2025 with Gemini 3 Pro as the flagship and described by Google as "our most…Mentioned 22 times above
- GPT-5.5GPT-5.5 is a large language model developed by OpenAI and released on April 23, 2026.Mentioned 15 times above
- AIME (American Invitational Mathematics Examination)The American Invitational Mathematics Examination (AIME) is a 15-question, 3-hour mathematics competition for high school students in the United States and CanadaMentioned 14 times above
- ARC-AGI-2ARC-AGI-2 (Abstraction and Reasoning Corpus for Artificial General Intelligence 2) is an abstract reasoning benchmark for artificial intelligence, released on March 24, 2025 by the ARC Prize FoundationMentioned 12 times above
- GPQA DiamondGPQA Diamond is the 198-question hardest subset of the Graduate-Level Google-Proof Q&A Benchmark (GPQA), a set of PhD-level multiple-choice questions in biology, physics, and chemistry used to measure…Mentioned 12 times above
- Claude Fable 5Claude Fable 5 is a large language model developed by Anthropic and released on June 9, 2026, as the first publicly available model in a new "Mythos class" that the company describes as "a tier of Claude…Mentioned 10 times above
More to read
Topics:Large Language ModelsModel EvaluationReasoning Models
References
- ^1 ^2 ^3 ^4Artificial Analysis, "LLM Leaderboard and Intelligence Index," artificialanalysis.ai/leaderboards/models (accessed July 2026).
- ^1 ^2 ^3 ^4 ^5 ^6Artificial Analysis, "Claude Fable 5 tops the Intelligence Index," artificialanalysis.ai/models/claude-fable-5 and /articles/claude-fable-5-mythos-intelligence-index.
- ^1 ^2 ^3 ^4 ^5Anthropic, "Introducing Claude Opus 4.8," anthropic.com/news/claude-opus-4-8 (May 28, 2026); Claude Opus 4.8 System Card.
- ^1 ^2 ^3 ^4ARC Prize Foundation, verified ARC-AGI-2 semi-private results, arcprize.org/leaderboard and x.com/arcprize (Gemini 3 Deep Think 45.14%, Gemini 3 Pro 31.11%, Grok 4 15.9%, GPT-5 9.9%).
- ^1 ^2 ^3 ^4 ^5 ^6OpenAI, "Introducing GPT-5.5," openai.com/index/introducing-gpt-5-5 (April 23, 2026).
- ^1 ^2 ^3Google, "Gemini 3 Deep Think," blog.google/products/gemini/gemini-3-deep-think (HLE 41.0% at launch, 48.4% after Feb 2026 update).
- ^1 ^2 ^3 ^4 ^5DeepSeek, "DeepSeek V4 Technical Report," arxiv.org/abs/2606.19348 and huggingface.co/deepseek-ai/DeepSeek-V4-Pro (MIT license).
- ^1 ^2 ^3 ^4Z.ai (Zhipu), "GLM-5.2," z.ai/blog/glm-5.2 and huggingface.co/zai-org/GLM-5.2 (MIT license, June 2026).
- ^1 ^2 ^3Scale AI, "Humanity's Last Exam leaderboard (SEAL)," labs.scale.com/leaderboard/humanitys_last_exam.
- ^1 ^2 ^3ARC Prize Foundation, "ARC Prize 2025 Results and Analysis," arcprize.org/blog/arc-prize-2025-results-analysis (Opus 4.5 Thinking 37.6%, Poetiq system 54%).
- ^Vellum, "Everything you need to know about GPT-5.5," vellum.ai/blog/everything-you-need-to-know-about-gpt-5-5 (transcribes OpenAI launch table).
- ^1 ^2 ^3Google DeepMind, "Gemini 3 Pro Model Card," storage.googleapis.com/deepmind-media/Model-Cards/Gemini-3-Pro-Model-Card.pdf (AIME 95% no tools, GPQA Diamond 91.9%, ARC-AGI-2 31.1% verified, HLE 37.5%).
- ^1 ^2 ^3Google, "Gemini 3.1 Pro," blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-3-1-pro (GPQA Diamond 94.3%, HLE 44.4%, self-reported ARC-AGI-2 77.1%).
- ^1 ^2 ^3Moonshot AI, "Kimi K2.6," huggingface.co/moonshotai/Kimi-K2.6 (GPQA Diamond 90.5%, AIME 2026 96.4%, HLE 34.7% / 54.0% with tools).
- ^1 ^2Qwen (Alibaba), "Qwen3-Max-Thinking," qwen.ai/blog?id=qwen3-max-thinking (AIME 2025 100% with tools, GPQA 87.4%).
- ^1 ^2 ^3MiniMax, "MiniMax M2," huggingface.co/MiniMaxAI/MiniMax-M2; Qwen3.7-Max page, artificialanalysis.ai/models/qwen3-7-max.
- ^1 ^2 ^3 ^4Epoch AI, "GPQA Diamond benchmark," epoch.ai/benchmarks/gpqa-diamond (human PhD baseline 69.7%; Grok 4 87%).
- ^OpenAI, "Introducing GPT-5.2," openai.com/index/introducing-gpt-5-2 (first 100% AIME 2025, no tools).
- ^LM Council, "AI Model Benchmarks (July 2026)," lmcouncil.ai/benchmarks (cross-model AIME and GPQA board; Claude Opus 4.8 AIME 98.3%).
- ^1 ^2 ^3Artificial Analysis, "GPQA Diamond and Humanity's Last Exam evaluations," artificialanalysis.ai/evaluations/gpqa-diamond and /humanitys-last-exam.
- ^1 ^2Imbue, "The evolution of ARC-AGI-2 (public versus semi-private)," imbue.com/blog/2026-02-27-arc-agi-2-evolution.
- ^1 ^2DeepSeek, "API pricing," api-docs.deepseek.com/quick_start/pricing; NIST/CAISI, "Evaluation of DeepSeek V4-Pro," nist.gov/news-events/news/2026/05/caisi-evaluation-deepseek-v4-pro.
- ^xAI, "Grok 4.3 model documentation," docs.x.ai/developers/models/grok-4.3 (pricing and release, April 30, 2026).
- ^1 ^2 ^3 ^4 ^5 ^6ARC Prize Foundation, "ARC-AGI Leaderboard," arcprize.org/leaderboard, with leaderboard data at arcprize.org/media/data/evaluations.json (ARC-AGI-2 semi-private scores by model and reasoning setting; accessed 27 October 2026).
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
5 revisions · v5 · 2,155 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Cite this page: AI Wiki. "Best AI Models for Reasoning and Math." aiwiki.ai, updated 27 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/best_ai_models_for_reasoning