

Flash Attention
FlashAttention is a family of exact, input/output-aware algorithms and GPU kernels for scaled dot-product attention. It accelerates the attention layer in Transformer models by tiling the calculation, keeping temporary score blocks in fast on-chip memory, and avoiding materialization of the full attention matrix in off-chip memory. The original 2022 algorithm retains the quadratic arithmetic work of dense attention but reduces auxiliary memory from quadratic to linear in sequence length and reduces traffic through the slow level of the memory hierarchy.[1]
"Exact" describes the mathematical operation, not bit-for-bit identity between every implementation. For a fixed attention mask, FlashAttention evaluates the same dense softmax attention as a conventional implementation. Because it changes the order of floating-point operations, its last bits can differ. Block-sparse variants are exact for the sparse mask they are given, but that mask can define an approximation to full dense attention.
Definition and scope
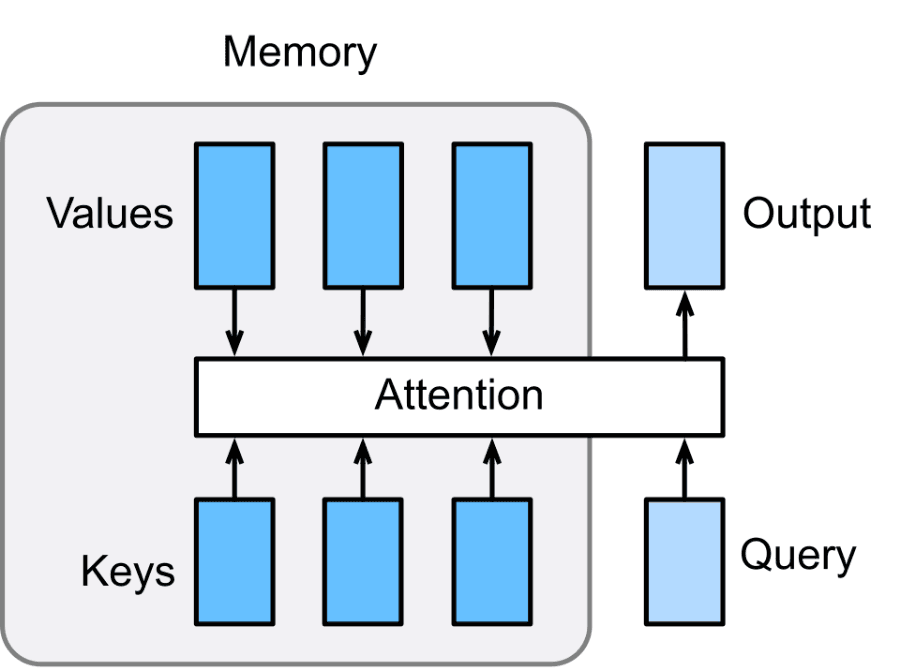
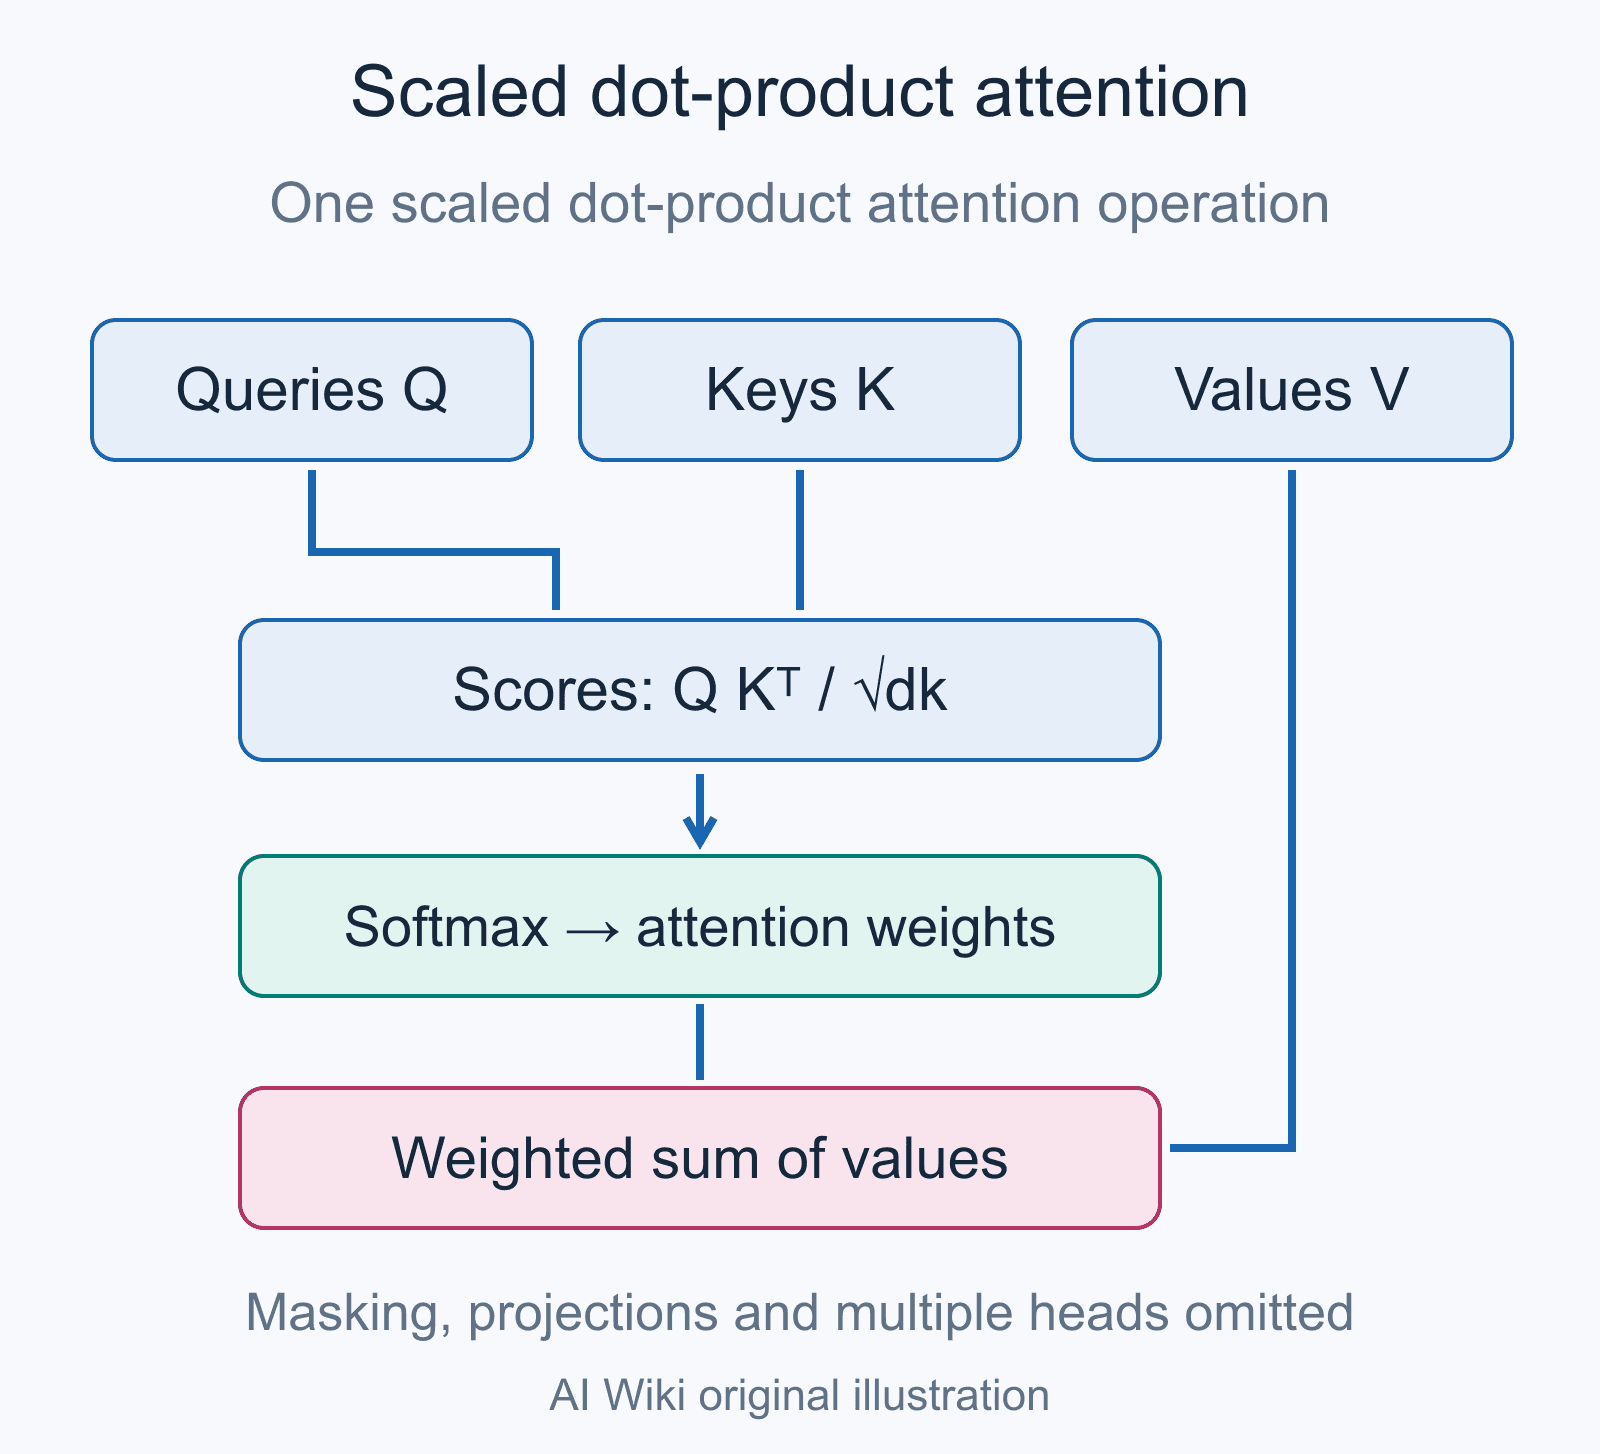
Scaled dot-product attention maps query, key, and value matrices to an output:
Here d is the head dimension. Multi-head attention applies this calculation to several heads, then combines their outputs. The Transformer paper established this formulation as the central mixing operation in its architecture.[2]
A straightforward implementation launches one operation to form QK^T, another to apply softmax, and another to multiply by V. That decomposition is clear and mathematically sound, but it normally writes an N by N score or probability matrix to high-bandwidth memory and reads it back. N is the sequence length. These intermediate matrices can dominate activation memory and memory traffic even though callers do not need them after the output and gradients have been produced.
FlashAttention changes the schedule, not the attention rule. It combines tiling, an online softmax recurrence, operation fusion, and backward-pass recomputation. The name also refers to the open-source flash-attn project and to successive hardware-specialized kernels, so version names and backend limitations matter when interpreting a performance or compatibility claim.
Why attention can be limited by input and output
Arithmetic work and data movement
Dense attention performs O(N^2 d) arithmetic operations. A conventional materializing implementation also moves O(N^2) intermediate elements through off-chip memory. A modern GPU can often execute matrix multiplication faster than it can repeatedly transfer those intermediates. In that regime, reducing data movement can lower elapsed time even if a kernel performs some extra arithmetic.
This distinction is the basis of an input/output, or IO, complexity model. The original paper models a fast on-chip memory of capacity M and a larger, slower HBM. For head dimension d and the range d <= M <= Nd, its tiled algorithm requires Theta(N^2 d^2 / M) HBM accesses, compared with Theta(Nd + N^2) for a standard materializing schedule. The paper also gives a lower bound showing that no exact attention algorithm can asymptotically improve this HBM-access count for every value of M in the model.[1]
The result is not a statement that every attention call is memory-bound. Short sequences, small heads, unusual layouts, synchronization, masking, compilation choices, and hardware generation can move the bottleneck. It is also not a claim of subquadratic computation. FlashAttention still evaluates all score pairs required by dense attention.
Memory hierarchy
The useful conceptual split is between large off-chip memory and much smaller per-multiprocessor storage such as shared memory and registers. The latter has much lower latency and much higher effective bandwidth, but a whole N by N matrix does not fit there. FlashAttention therefore processes rectangular blocks whose working set does fit.
The word "SRAM" is often used informally for this fast level. Hardware specifications require more care. A capacity quoted for a GPU can refer to a combined L1, texture, and shared-memory pool, to the configurable shared-memory portion, or to a distinct structure. Treating those quantities as interchangeable leads to incorrect block-size and capacity comparisons.
The tiled exact algorithm
Forward pass
The forward kernel partitions Q into row blocks and K and V into column blocks. For each query block it repeatedly:
- loads a key block and its matching value block into on-chip memory;
- forms a local score block;
- applies causal, local, bias, or other supported score modifications;
- updates a running softmax maximum and normalizer;
- multiplies the exponentiated scores, taken relative to the running maximum, by the value block; and
- updates the running output accumulator.
This is the loop order used from FlashAttention-2 onward. The 2022 kernel nested the loops the other way: its outer loop ran over key and value blocks and its inner loop over query blocks, so each query block's partial output and softmax statistics were loaded from HBM, updated, and written back once per key block.[1] FlashAttention-2 swapped the order so that the outer loop runs over query row blocks, which are independent and can be scheduled on different thread blocks without communication; its backward pass keeps an outer loop over key and value column blocks and uses atomic adds to accumulate the query gradient.[5]
Only block-sized scores exist at any one time. Once a block has contributed to the running statistics and output, its score values can be discarded. The final output, rather than the full score or probability matrix, is written to HBM.
Kernel fusion is essential to the schedule. An unfused expression such as:
scores = q @ k.transpose(-2, -1)
probabilities = scores.softmax(dim=-1)
output = probabilities @ v
exposes the intermediate tensors to the framework. A FlashAttention kernel performs their logical work inside a fused CUDA or equivalent backend kernel, with the exact launch and pipeline structure varying by version.
Online softmax
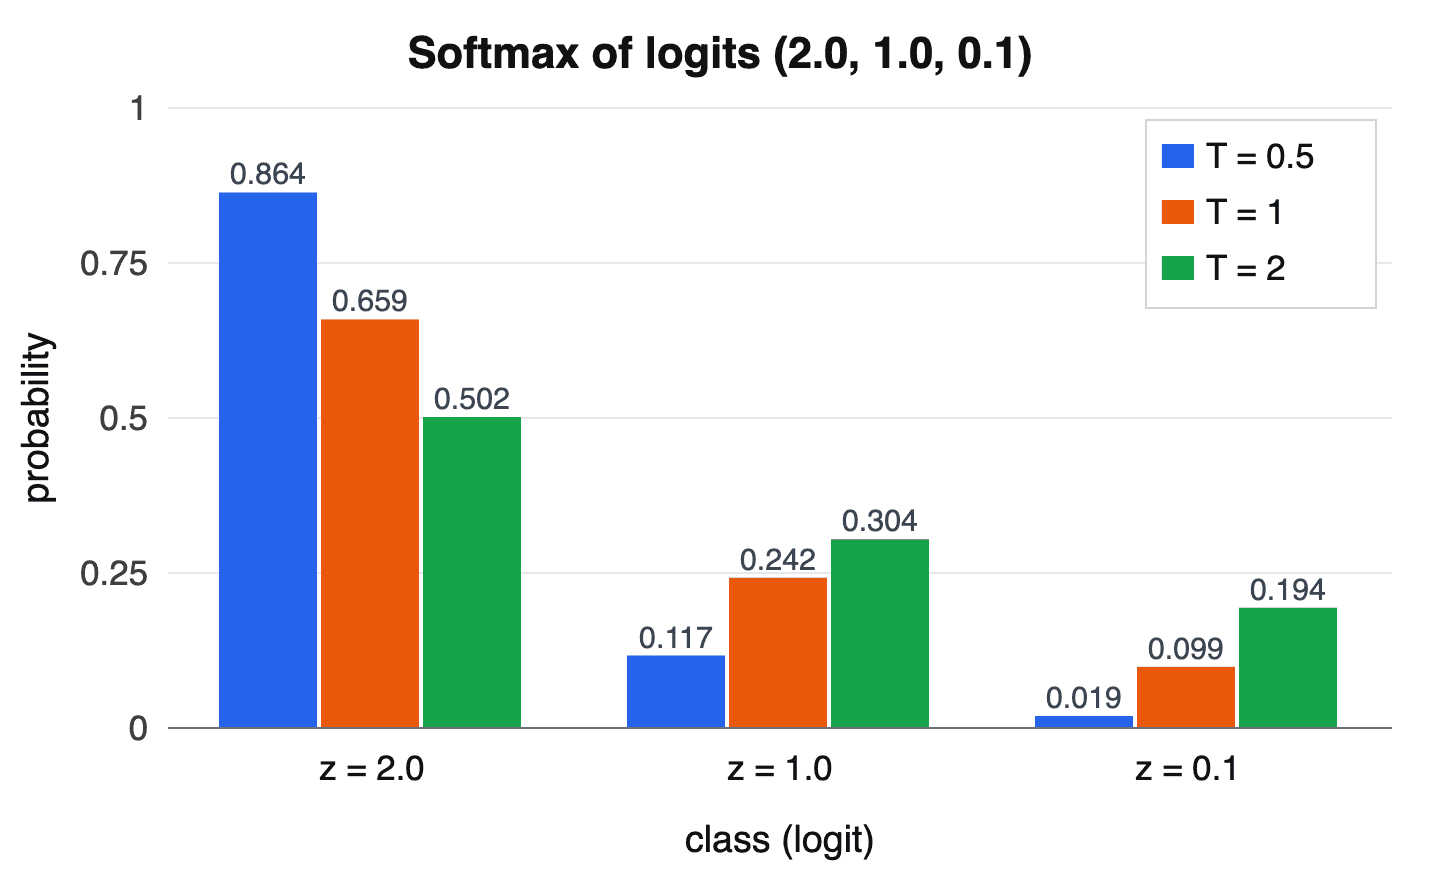
Stable softmax normally subtracts a row maximum before exponentiation. Tiling appears to create a problem because a block does not yet know the maximum of later blocks. Online softmax solves it by carrying a running maximum m, a running exponential sum l, and an unnormalized output accumulator.
Suppose a new score block has values s_j. If m_old and l_old summarize earlier blocks, the update is:
The old output numerator is multiplied by the same correction factor before the new block contribution is added:
After all key and value blocks have been processed, the row output is O = \widetilde O / l. These rescalings preserve a common normalization reference when the running maximum rises. Milakov and Gimelshein introduced the online-normalizer method as a way to reduce safe-softmax memory accesses; their paper reports three memory accesses per input element instead of four for a conventional safe implementation and up to 1.3 times speedup for softmax on its V100 tests.[3] FlashAttention extends the recurrence to the attention-weighted value sum.
Masks are applied before the local exponentials. A causal mask, for example, sets future-position scores to negative infinity within each applicable block. Attention dropout can also be fused, provided the implementation preserves the intended random-mask and scaling semantics.
Backward pass and recomputation
Gradients with respect to Q, K, and V depend on the attention probabilities. Saving those probabilities would restore a quadratic activation. FlashAttention instead stores the output and a per-row normalization statistic, commonly a log-sum-exp value, then recomputes score and probability blocks during backpropagation. The extra matrix operations are often cheaper than writing and rereading the full probability matrix.
For fixed head dimension, the saved attention-specific state is linear in N, rather than quadratic. This is an auxiliary-memory claim: inputs, outputs, model parameters, and other layer activations still consume memory. Peak memory also depends on the framework, tensor layout, dropout state, and workspace used by the selected backend.
Correctness and floating point
In real arithmetic, the block recurrence is algebraically equivalent to row-wise softmax followed by multiplication by V. Stable maximum subtraction prevents exponent overflow in the same way as conventional safe softmax.
Floating-point addition and multiplication are not associative. A tiled kernel can therefore disagree with a reference implementation in low-order bits, and two backends can use different accumulation precision. Correct testing should use tolerances appropriate to dtype, input scale, hardware, and backend rather than a universal fixed threshold. Deterministic backward modes, when offered, concern repeatability of a particular implementation and may have a performance cost; they do not make all implementations bit-identical.
Earlier memory-efficient exact attention
FlashAttention was not the first proof that exact self-attention need not save a quadratic matrix. Rabe and Staats described an exact formulation with O(1) memory in sequence length for single-query attention and O(log N) for self-attention, plus a practical square-root-memory implementation. Their sequence-length 16,384 experiments reported 59 times less inference memory and 32 times less differentiation memory than their baseline, while checkpointed differentiation added runtime.[4] FlashAttention combined recomputation with an IO-aware tiled schedule and fused kernels designed for high wall-clock throughput.
Versions
FlashAttention
The first paper was written by Tri Dao, Daniel Y. Fu, Stefano Ermon, Atri Rudra, and Christopher Ré and appeared at NeurIPS 2022. It introduced the tiled exact forward and backward algorithms, analyzed their HBM traffic, and included a block-sparse extension.[1]
The reported results are benchmark-specific. In the paper's tested settings, the attention computation for GPT-2 was up to 7.6 times faster than the PyTorch attention implementation it was compared with. End-to-end examples included a 15 percent wall-clock training improvement for BERT-large (sequence length 512) over the Nvidia implementation that set the MLPerf 1.1 training speed record, measured on 8 A100 GPUs; up to 3 times faster training for GPT-2 at sequence length 1,024 than the Hugging Face implementation (and up to 1.7 times faster than Megatron-LM); and a 2.4 times speedup on Long Range Arena tasks at sequence lengths from 1,024 to 4,096. The same experiments showed memory use growing linearly with sequence length for FlashAttention and reductions reaching about 20 times against the exact baselines at the tested long lengths. None of those values is a promise for arbitrary models, GPUs, or software versions.
The paper also used the saved memory and speed to run longer-context experiments. The authors report that FlashAttention gave the first Transformer to reach better-than-chance accuracy on the Path-X task (sequence length 16K, 61.4 percent accuracy), and that block-sparse FlashAttention reached 63.1 percent on Path-256 (sequence length 64K).[1] Those quality results demonstrate what the implementation made practical in the tested training runs, not that changing an attention kernel by itself improves a fixed model's mathematical predictions.
FlashAttention-2
FlashAttention-2 was released as a 2023 preprint by Tri Dao and accepted at ICLR 2024. It retained the same attention formulation and made three central scheduling changes:
- it reduced non-matrix-multiplication operations in the inner loop;
- it parallelized over query sequence blocks as well as batch and heads; and
- it split query work across warps, avoiding the shared-memory reduction required by the first version's split-key partition.
The paper reports roughly twice the speed of FlashAttention in its comparisons (1.7 to 3.0 times across its A100 80GB SXM4 benchmarks, and 3 to 10 times faster than a standard attention implementation), 50 to 73 percent of the theoretical maximum throughput on A100, and up to 225 TFLOP/s per A100, or 72 percent model FLOP utilization, when training GPT-style models of 1.3B and 2.7B parameters end to end on 8 A100 GPUs. It also covers multi-query attention and grouped-query attention, where several query heads share fewer key and value heads.[5]
The important advance was work partitioning, not a new approximation. Better sequence parallelism matters when batch size and head count alone do not expose enough independent thread blocks to occupy the GPU.
FlashAttention-3
FlashAttention-3 was developed for Hopper GPUs by Jay Shah, Ganesh Bikshandi, Ying Zhang, Vijay Thakkar, Pradeep Ramani, and Tri Dao and appeared at NeurIPS 2024. It used Hopper's Tensor Memory Accelerator (TMA) and warp-group matrix-multiply (WGMMA) instructions. Warp specialization splits each thread block into producer warps, which issue TMA loads of key and value tiles into a circular shared-memory buffer, and consumer warp groups, which run the matrix multiplications and softmax. On top of that, a "pingpong" schedule uses barriers so that the softmax of one consumer warp group runs while another warp group's matrix multiplications occupy the tensor cores, with the roles then swapping; the paper also overlaps softmax with matrix multiplication inside a single warp group. The motivation is the gap between H100's 989 TFLOPS of FP16 matrix throughput and its 3.9 TFLOPS of special-function throughput for exponentials. As one data point, the authors report that pingpong scheduling raised FP16 forward throughput from 570 to 620-640 TFLOP/s at head dimension 128 and sequence length 8,192.[6] The separate Flash Attention 3 article covers the design in more detail.
Its low-precision path applied block quantization and an incoherent-processing transform based on random signs and a Hadamard transform. Applying the same orthogonal transform to queries and keys preserves their real-arithmetic dot products while redistributing outliers. In the NeurIPS 2024 paper's H100 SXM5 experiments, BF16 was 1.5 to 2.0 times faster than FlashAttention-2 in the forward pass, reaching as high as 840 TFLOP/s (about 85 percent utilization), and 1.5 to 1.75 times faster in the backward pass; FP8 forward reached 1.3 PFLOP/s. The authors reported 2.6 times lower numerical error for their FP8 method than a baseline using per-tensor FP8 quantization, in a test with outlier features.[6] The July 2024 arXiv preprint had reported lower ceilings: up to 740 TFLOP/s in FP16 (75 percent utilization) and close to 1.2 PFLOP/s in FP8.[26]
The conference figures supersede the preprint and project-blog numbers for the final peer-reviewed algorithm. The paper also states important limits: optimizing for LLM inference and understanding the effects of low-precision attention in large-scale training remained future work.
FlashAttention-4
FlashAttention-4 was posted to arXiv on 5 March 2026 by Ted Zadouri, Markus Hoehnerbach, Jay Shah, Timmy Liu, Vijay Thakkar, and Tri Dao.[7] It was published in the Proceedings of Machine Learning and Systems 8 (MLSys 2026); the proceedings version lists five authors (Zadouri, Hoehnerbach, Shah, Thakkar, and Dao) and repeats the preprint's headline B200 figures.[25] Before the paper, Dao had presented preliminary FlashAttention-4 results at Hot Chips in August 2025, according to a September 2025 analysis by Modal.[37] It targets the asymmetric scaling of Blackwell B200 and GB200 hardware, where tensor-core throughput grew faster than shared-memory bandwidth and special-function throughput.[7]
The design combines a deeper asynchronous pipeline, two-CTA matrix-multiply modes, Tensor Memory, a partly software-emulated exponential, conditional softmax rescaling, revised backward scheduling, and a deterministic backward option. Conditional rescaling only rescales the output accumulator when the running maximum has grown by more than a threshold; because the kernel keeps track of the total scaling it has applied, it still recovers the true normalizer for the final output. The paper describes a typical threshold of log2(256) = 8, corresponding to a rescaling factor of 256; it does not support a universal claim that a fixed percentage of rescalings is always skipped. Its degree-three polynomial approximation of the exponential runs on the FMA units and is applied to only a subset of each softmax row (10 to 25 percent, tuned per tile configuration), with the rest computed by the hardware MUFU.EX2 instruction; after rounding to BF16, the measured error is dominated by BF16 quantization in the evaluated setup. The paper's deterministic backward mode reached up to 75 percent of the speed of the nondeterministic 1-CTA backward pass.[7]
On selected B200 BF16 attention shapes (head dimension 64 or 128, plus the (192, 128) head-dimension configuration that the paper associates with DeepSeek V3; sequence lengths 1K to 32K with 32K total tokens per batch), the paper reports up to 1,613 TFLOP/s, or 71 percent of peak, 1.1 to 1.3 times the forward speed of cuDNN 9.13, and 2.1 to 2.7 times the speed of the compared Triton kernel. The authors state that, starting with versions 9.13 and 9.14, they worked with the cuDNN team to incorporate some FlashAttention-4 techniques, and that newer cuDNN versions (they also tested 9.19.1.2) yield performance similar to FlashAttention-4.[7] The implementation uses CuTe DSL; the paper's measured compile times were 2.5 seconds for a forward kernel and 1.4 seconds for a backward kernel, compared with 55 and 45 seconds for the listed FlashAttention-3 compilation, respectively. These are scoped measurements, not general installation-time guarantees.
The versions can be summarized as follows:
| Version | Publication | Primary hardware focus | Main scheduling contribution | Selected reported ceiling |
|---|---|---|---|---|
| FlashAttention | 2022 | Ampere A100 | IO-aware tiling, online softmax, recomputation | up to 7.6 times attention speedup in paper comparisons |
| FlashAttention-2 | 2023 preprint, ICLR 2024 | Ampere A100 | less scalar work, sequence parallelism, query-split warps | 50 to 73 percent of A100 theoretical maximum |
| FlashAttention-3 | 2024 preprint, NeurIPS 2024 | Hopper H100 | TMA, warp specialization, asynchronous overlap, FP8 path | 840 TFLOP/s BF16 and 1.3 PFLOP/s FP8 (conference version) |
| FlashAttention-4 | March 2026 preprint, MLSys 2026 | Blackwell B200 and GB200 | pipeline co-design, Tensor Memory, conditional rescaling | 1,613 TFLOP/s BF16, 71 percent of peak |
The table intentionally mixes only values reported by each primary paper. It should not be read as a controlled cross-generation benchmark.
Open-source implementation
The official project is maintained in the Dao-AILab/flash-attention repository and uses the BSD 3-Clause license; as of 31 October 2026 the repository had about 25,200 GitHub stars. The FlashAttention-2 package is named flash-attn, while FlashAttention-4 is distributed separately as flash-attn-4. The repository covers more than one implementation generation, and a feature shown in the README is not necessarily available on every backend.[8]
FlashAttention-4 has shipped only as beta releases. The first tags (fa4-v4.0.0.beta0, beta1, beta2, and beta4; there is no beta3 tag) appeared on 5 March 2026, the day the paper was posted, and betas have followed roughly weekly since late March. As of 31 October 2026, the latest was fa4-v4.0.0.beta37, dated 28 October 2026 and published on PyPI as flash-attn-4 4.0.0b37; the package metadata still carries the "Development Status :: 3 - Alpha" classifier. The latest stable FlashAttention-2 release was v2.8.3.post2, dated 13 October 2026, a maintenance release that the project describes as having no kernel feature changes: it backports fixes for two security advisories (CVE-2026-31253 and CVE-2026-62239) and an int32 overflow in the backward pass that could cause illegal memory accesses or NaN gradients on very large inputs.[9][27]
The FlashAttention-2 line added features through minor versions, as recorded in the project changelog:
| Version | Release | Change recorded in the changelog |
|---|---|---|
| 2.0 | 2023 | Complete rewrite, about 2 times faster; unpadded functions renamed to varlen |
| 2.1 | August 2023 | Causal mask aligned to the bottom-right corner when query and key lengths differ |
| 2.2 | September 2023 | Inference optimization for very short queries: KV-cache loading split across thread blocks, flash_attn_with_kvcache |
| 2.3 | September 2023 | Local (sliding-window) attention, contributed with Mistral AI |
| 2.4 | December 2023 | ALiBi and deterministic backward pass |
| 2.5 | January 2024 | Paged KV cache |
| 2.6 | July 2024 | Softcapping, as used in Gemma-2 and Grok models |
| 2.7 | November 2024 | Compatibility with torch.compile |
Release months are the GitHub release dates of the corresponding .0 tags; the 2.0 rewrite predates the repository's first 2.0.x GitHub release in August 2023.[8][9]
CUDA packages
The main FlashAttention-2 CUDA package documents Linux, PyTorch 2.2 or later, and CUDA 12 or later. Its listed NVIDIA targets are Ampere, Ada, and Hopper, with FP16 and BF16 forward and backward kernels for head dimensions up to 256. Turing support is directed to a separate repository. This is narrower and more accurate than treating every NVIDIA architecture from Volta onward as supported by the same current package.[8]
The repository's FlashAttention-3 path is a beta package for H100 and H800, built from the hopper subdirectory as flash-attn-3; it requires CUDA 12.3 or later, recommends CUDA 12.8, and as of October 2026 the README lists FP16 and BF16 forward and backward plus FP8 forward. The FlashAttention-4 package is written in CuTe DSL and is described as optimized for Hopper and Blackwell, including B200. It installs with pip install flash-attn-4 (with a cu13 extra recommended on CUDA 13) and is imported from flash_attn.cute. Version-specific installation instructions should be followed rather than assuming that pip install flash-attn selects every generation automatically.[8][28]
AMD backends
The repository also documents ROCm backends, both implementing FlashAttention-2 and requiring ROCm 6.0 or later. The default Composable Kernel backend lists MI200x, MI250x, MI300x, MI355x, and RDNA 3 and 4 GPUs, with FP16 and BF16 forward and backward support up to head dimension 256. A Triton backend, whose kernels come from AMD's aiter package bundled as a git submodule, lists CDNA (MI200, MI300) and RDNA GPUs with FP16, BF16, and FP32; its README entry covers causal masking, variable sequence lengths, MQA and GQA, dropout, rotary embeddings, ALiBi, paged attention, and FP8 through the FlashAttention-3 interface, with sliding-window attention still marked as work in progress as of October 2026.[8] Separately, PyTorch 2.7 (April 2025) added a Composable Kernel flash-attention backend for its own ROCm builds.[35]
Support statements are therefore multidimensional. GPU architecture, dtype, head dimension, forward versus backward, mask form, dropout, deterministic mode, and KV-cache features can each affect dispatch. A backend may reject an input or fall back to a different implementation.
Features
The official documentation lists causal attention, local sliding windows, ALiBi bias, deterministic backward, softcapping, paged KV caches, and MQA or GQA among supported capabilities. Some APIs also combine rotary embedding updates and KV-cache writes with attention for decoding. These lists describe the project as a whole. Users should check the exact function and backend, especially for dropout, variable-length inputs, FP8, and backward support.[8]
Framework integration
PyTorch scaled dot-product attention
The documentation note for torch.nn.functional.scaled_dot_product_attention lists three implementations: FlashAttention-2, a memory-efficient fused implementation, and a C++ math implementation. The SDPBackend enum used with sdpa_kernel also includes CUDNN_ATTENTION and OVERRIDEABLE, as of the PyTorch 2.15 documentation.[10][33] The cuDNN backend arrived as a beta feature in PyTorch 2.5 (October 2024), whose release notes reported up to 75 percent speedup over FlashAttention-2 on H100.[34] PyTorch exposes sdpa_kernel so a caller can request particular backends. The fused choices have input restrictions, and a forced backend can emit a warning when it cannot run. The stable documentation explicitly warns that floating outputs can differ by backend; it also labels GQA support experimental and notes that dropout is applied according to the passed probability even during evaluation unless the caller passes zero.[10]
PyTorch 2.2 announced that FlashAttention-2 had replaced the prior FlashAttention backend for SDPA and reported about twice the performance of the previous implementation in the release team's benchmark context.[11] Later versions added newer FlashAttention generations as opt-in implementations rather than defaults:
| PyTorch release | Date | FlashAttention-related change |
|---|---|---|
| 2.10 | January 2026 | "Add Flash Attention 4 to sdpa"; torch.nn.attention gains register_flash_attention_impl and activate_flash_attention_impl, documented with the identifier "FA4" |
| 2.11 | March 2026 | Documented identifiers become "FA3" and "FA4"; FlexAttention's FlashAttention-4 backend (initial support was listed in the 2.10 notes) is headlined for Hopper and Blackwell; torch.compile support for FP8 SDPA using FlashAttention-3 |
| 2.15 | October 2026 | FlashAttention-4 allowed in SDPA with different query/key and value head dimensions; the FlashAttention SDPA backend enabled in Windows CUDA builds for Ampere and newer GPUs |
The documentation says backend providers should not activate their implementation on import; users opt in by calling activate_flash_attention_impl (or through environment variables) so that several provider libraries can coexist.[29][30][31][32][40] This history explains why "PyTorch uses FlashAttention" is incomplete without a PyTorch version, selected backend, and input shape.
A minimal backend request is:
import torch.nn.functional as F
from torch.nn.attention import SDPBackend, sdpa_kernel

with sdpa_kernel(backends=[SDPBackend.FLASH_ATTENTION]):
    output = F.scaled_dot_product_attention(
        query,
        key,
        value,
        is_causal=True,
        dropout_p=0.0,
    )
Automatic dispatch is usually preferable when portability matters. Forcing a backend is useful for testing, but it converts unsupported combinations into a warning or error instead of allowing another kernel.
Hugging Face Transformers
Hugging Face Transformers exposes attention backends through its AttentionInterface. Its documentation lists names including sdpa, flash_attention_2, flash_attention_3, flex_attention, and paged variants, while model support and accepted mask representation can vary. The FlashAttention integrations consume a base two-dimensional padding mask in documented paths rather than an arbitrary pre-expanded four-dimensional score mask.[12]
Initial FlashAttention-4 support (attn_implementation="flash_attention_4", which calls the flash_attn.cute package) was added in Transformers v5.4.0 in March 2026.[36] The documentation also describes loading FlashAttention kernels from the Hugging Face Hub through the Kernels library (for example kernels-community/flash-attn2), and requesting FlashAttention by name falls back to the Hub kernel when the package is not installed.[12]
The availability of a backend name does not prove that a particular model was trained with it. Claims about named model training recipes require model-specific primary evidence. Broad lists saying that essentially every modern model uses FlashAttention are therefore not reliable substitutes for such evidence.
Triton and other implementations
The Triton fused-attention tutorial provides an inspectable implementation of the tiled forward and backward ideas and a benchmark harness. It is educational and useful for kernel development, but its supported shapes and results should not be assumed identical to the official CUDA project or to framework dispatch.[13]
Other libraries and vendor stacks contain fused attention kernels inspired by similar IO-aware principles. "Flash-style" is a design description, not proof that code is the official FlashAttention implementation or that it shares its license, numerical behavior, supported masks, or performance.
Training and autoregressive decoding
Training and prompt processing usually present many query rows, so parallelism can be distributed across batch, heads, and query blocks. One-token autoregressive decoding has a very different shape: the query length can be one while the cached key and value sequence is long. A training-oriented kernel may then expose too few independent query blocks to occupy the GPU.
Flash-Decoding
Flash-Decoding adds parallelism over the key and value sequence. It splits the KV cache into chunks, runs a FlashAttention-style calculation for each chunk, and combines partial outputs using their log-sum-exp statistics. The Stanford CRFM report described three stages: parallel per-split attention, per-split statistics, and a small reduction to produce the final output.[14]
On a CodeLlama-34B, batch-one A100 benchmark, the report measured up to 8 times end-to-end decoding speedup at long context and attention-kernel speedups up to 50 times. xFormers 0.0.22 announced the feature with the same scoped maxima.[15] In flash-attn itself, the 2.2 release added the same kind of split KV-cache loading with a separate combine kernel for very short queries, crediting the xFormers team.[8] The gain is workload-dependent and shrinks when batch and heads already provide enough parallel work.
FlashDecoding++
FlashDecoding++ is a separate MLSys 2024 system. It combines an asynchronous unified-max softmax approach, flat-GEMM optimization, double buffering, and a heuristic choice among dataflows. Across the paper's evaluated models and devices it reported an average 1.37 times speedup over FlashDecoding, with maxima of 4.86 times over the Hugging Face baseline on NVIDIA and 4.35 times on AMD.[16] It should not be conflated with a numbered FlashAttention release.
Related and complementary methods
Block-sparse FlashAttention
The original paper included block-sparse FlashAttention. It skips masked score blocks, so its work and IO scale with the number of retained blocks. In the paper's experiments it was 2 to 4 times faster than dense FlashAttention and supported tested sequences up to 64K.[1]
The word "exact" needs a reference point. If an architecture defines a particular block-sparse mask, the kernel can compute that masked operation exactly. If the mask is introduced as a substitute for full dense attention, the resulting attention pattern is an approximation to the dense operation. Causal and fixed local masks likewise define which score pairs exist; efficient masking does not itself imply an approximation once that operation is specified.
FlexAttention
PyTorch's FlexAttention accepts a score_mod function and a block mask, then lowers supported patterns into fused Triton kernels. It is intended for custom biases and masks that are awkward to encode as a fixed FlashAttention option. In the 2024 prototype blog's A100 causal benchmark, it reached about 90 percent of FlashAttention-2 forward performance and 85 percent of backward performance. The same source notes that block-mask construction can be costly and that the published figures were not universal.[17]
FlexAttention complements FlashAttention: one prioritizes programmable score semantics, while the other offers highly specialized kernels for a defined feature set. Which is faster depends on the pattern, sparsity, shape, compilation, and hardware.
PagedAttention
PagedAttention, introduced with vLLM, addresses KV-cache allocation and fragmentation in serving by storing cache blocks in noncontiguous physical memory and mapping logical token blocks to them. It is orthogonal to how the local attention scores are tiled. A serving system can use paged KV-cache management and a FlashAttention-family kernel together.[18]
The PagedAttention paper reports 2 to 4 times throughput improvements over FasterTransformer and Orca in its serving experiments. Those gains include memory-management and batching effects and should not be attributed to FlashAttention.
FlashInfer
FlashInfer is a serving-oriented attention engine presented at MLSys 2025. It offers customizable templates, just-in-time specialization, multiple KV-cache layouts, and load-balanced scheduling for changing request lengths. Its paper describes integration into systems including vLLM, SGLang, and MLC Engine.[19] It belongs to the wider ecosystem of IO-aware attention kernels, but it is not a FlashAttention version.
FlashMLA and low-precision derivatives
FlashMLA, released by DeepSeek in February 2025, is a separate open-source kernel library for multi-head latent attention; despite the name, it is not part of the Dao-AILab project.[39] Research on lower-precision variants also builds on FlashAttention-4: a September 2026 single-author preprint describes FP4 attention paths for Blackwell and reports up to 2.13 times the BF16 forward throughput on a GB200 for noncausal inference, while also reporting that every MXFP4 probability and value training run it tested diverged. These are one preprint's results and have not been peer reviewed.[38]
Ring Attention
Ring Attention distributes long sequences across devices. Each device computes blockwise attention over local query blocks while key and value blocks circulate around a ring, overlapping communication with computation. The method can use a memory-efficient exact local kernel, including FlashAttention-style tiling, but it solves a multi-device distribution problem rather than replacing the local kernel.[20]
Approximate sparse attention, linear attention, recurrent state-space models, KV-cache quantization, and attention-sink methods address other scaling limits. Their complexity or semantics differ, so they should not be grouped under FlashAttention merely because they reduce memory or run time.
Hardware interpretation
Ampere A100
NVIDIA's A100 whitepaper specifies 192 KB per streaming multiprocessor for the combined L1 data cache and shared-memory structure, with shared memory configurable up to 164 KB. It also lists 1,555 GB/s HBM2 bandwidth for the 40 GB A100 configuration.[21] Saying simply that A100 has "192 KB SRAM" erases the cache carve-out and can overstate the space available to one attention tile.
FlashAttention and FlashAttention-2 were designed and benchmarked around Ampere capabilities, including tensor cores and asynchronous global-to-shared-memory copies. Their block sizes are implementation choices shaped by head dimension, dtype, register pressure, shared-memory limits, and desired occupancy, not constants inherent to the algorithm.
Hopper H100
The Hopper tuning guide lists 228 KB of shared-memory capacity per H100 SM and up to 227 KB addressable by one thread block, within a 256 KB combined L1, texture, and shared-memory structure. It also describes TMA as an asynchronous engine for one- through five-dimensional transfers between global and shared memory and lists HBM3 bandwidth up to 3 TB/s.[22]
FlashAttention-3 was built to exploit those capabilities along with warp-group matrix multiplication. Porting an older kernel without rescheduling would leave some of Hopper's asynchronous and low-precision throughput unused.
Blackwell B200
For compute capability 10.0, the Blackwell tuning guide gives 228 KB shared-memory capacity per SM and a 256 KB combined L1, texture, and shared-memory structure.[23] FlashAttention-4 additionally uses Blackwell Tensor Memory, described in its paper as 256 KB per SM, for accumulator storage. Tensor Memory is distinct from the combined L1 and shared-memory pool.[7]
The FlashAttention-4 paper argues that Blackwell scaling is asymmetric: matrix throughput increased more than shared-memory bandwidth and exponential-function throughput. Its software-emulated exponentials, conditional rescaling, and deeper overlap respond to that imbalance. As a result, the fastest schedule is generation-specific even though the underlying attention equation is unchanged.
Performance interpretation
Published maxima answer a narrow question: how fast did a particular kernel run for a chosen shape, dtype, mask, software build, GPU, clock and power state, and comparison library? They do not establish a single "FlashAttention speedup."
Before comparing results, check:
- whether the number is an attention-kernel measurement or end-to-end model throughput;
- forward, backward, prompt processing, or one-token decoding;
- batch, sequence length, head count, head dimension, and MQA or GQA ratio;
- causal, full, local, or sparse mask;
- dtype and accumulation path, including whether FP8 error is part of the comparison;
- whether dropout, bias, variable lengths, or a KV-cache update is fused;
- the precise GPU and software versions; and
- whether the baseline is an unfused framework expression, a prior FlashAttention release, Triton, cuDNN, or another optimized kernel.
Memory savings also need a denominator. "Linear memory" describes the attention-specific auxiliary state for fixed head dimension. Total training memory can still be dominated by parameters, optimizer states, other activations, temporary workspaces, allocator fragmentation, or the KV cache. A fused kernel can reduce attention activations dramatically without reducing the model's entire memory footprint by the same factor.
End-to-end gains depend on the fraction of time previously spent in attention. If feed-forward layers, communication, data loading, or sampling dominate, a large kernel-level speedup produces a smaller application-level improvement. Conversely, very long sequence lengths can make attention a larger fraction of time and memory.
Limitations and operational considerations
Quadratic arithmetic remains
Dense FlashAttention still computes O(N^2 d) dot-product work. Tiling changes memory traffic and storage, not the number of dense query-key pairs. At sufficiently long contexts, compute time remains quadratic unless the attention pattern, model, or distribution strategy changes.
Specialized kernels have boundaries
Fast paths are specialized by architecture, dtype, head dimension, layout, and feature combination. A framework can silently select another backend, or a forced backend can reject the call. Performance-sensitive deployments should record dispatch and benchmark the actual production shapes.
Arbitrary per-element masks are especially challenging because they can defeat block-level skipping and regular memory access. Packing several documents into one sequence, combining causal and bidirectional regions, or using irregular biases deserves explicit correctness tests. Cross-attention can have unequal query and key lengths, so causal-window conventions must be checked rather than borrowed uncritically from self-attention.
Compilation and installation
Building CUDA template kernels can be resource-intensive. The official repository notes that without Ninja a build can take about two hours because it does not use multiple CPU cores, while with Ninja compilation takes three to five minutes on a 64-core machine. That is not evidence that builds normally take hours under a correctly configured parallel toolchain.[8]
FlashAttention-4's CuTe DSL substantially shortened the paper's individual kernel compile measurements, but package installation still depends on toolchain, architecture targets, memory, cached artifacts, and the number of generated variants.
Numerical validation
Backends should be checked against a trusted reference over representative masks, lengths, dtypes, and value ranges. Tests should include fully masked rows if the API permits them, noncontiguous layouts, variable-length batches, dropout behavior, MQA or GQA head mapping, and gradients. Tolerances must reflect the backend and dtype.
FP8 paths add quantization choices beyond floating-point reassociation. FlashAttention-3's error reduction was measured against a particular per-tensor FP8 baseline, while FlashAttention-4's BF16 exponential approximation was evaluated in its own pipeline. Neither result supports a blanket statement that all low-precision FlashAttention outputs are bit-equivalent to a high-precision reference.
Reproducibility and dispatch
Record the project or framework version, selected backend, GPU model, driver and CUDA or ROCm version, dtype, flags, and input shape. Automatic dispatch can change after a framework upgrade. A reproducible report should distinguish mathematical equivalence, numerical agreement within a stated test, and deterministic repeatability on one stack.
Project significance
FlashAttention made IO cost a first-class design variable for a central deep-learning operation. Its influence is visible in framework dispatch, custom attention compilers, serving kernels, and hardware-specific pipelines. The project also provides a clear example of algorithm and kernel co-design: the mathematical recurrence persists while the execution schedule changes from Ampere to Hopper to Blackwell.
Stanford lists FlashAttention as a 2024 winner of its Open Source Software Prize, citing its efficiency contribution and adoption. The official page does not state that it was selected from a pool of more than 75 projects, so that often-repeated number is not retained here.[24]
The lasting contribution is not a universal speed ratio. It is the demonstration that exact attention can avoid saving its quadratic intermediate and can be scheduled around a real memory hierarchy. The best implementation remains dependent on workload and hardware, but that IO-aware principle continues across the numbered releases.
Continue reading
- AttentionAttention is a family of operations in neural networks that computes an output by assigning data-dependent weights to a collection of representations and combining them.Mentioned 83 times above
- TransformersA Transformer is a deep learning architecture, introduced by eight Google researchers in the 2017 paper "Attention Is All You Need", that uses attention as the sole mechanism for modeling relationships between…Mentioned 6 times above
- SoftmaxSoftmax is a function that converts a finite vector of real-valued scores into a vector of positive numbers that sum to one.Mentioned 19 times above
- Full SoftmaxFull softmax (also called the standard softmax or exact softmax) is the softmax computation that calculates a probability for every possible output class in a classification modelMentioned 19 times above
- CuDNNNVIDIA cuDNN (CUDA Deep Neural Network library) is a proprietary GPU-accelerated library of primitives for deep learning, first released by NVIDIA on September 7, 2014, that provides highly tuned…Mentioned 6 times above
- Triton (OpenAI GPU programming language)Triton is an open-source, Python-embedded programming language and compiler, originally created by Philippe Tillet and released by OpenAI in July 2021Mentioned 6 times above
More to read
- Matrix multiplication
- KV Cache
- Tri Dao
- Self-attention
- PagedAttention
- ALiBi (Attention with Linear Biases)
Topics:Machine Learning
References
- ^1 ^2 ^3 ^4 ^5 ^6Dao, T., Fu, D. Y., Ermon, S., Rudra, A., and Ré, C. (2022). "FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness." *Advances in Neural Information Processing Systems 35*. NeurIPS proceedings.
- ^Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., and Polosukhin, I. (2017). "Attention Is All You Need." *Advances in Neural Information Processing Systems 30*. NeurIPS proceedings.
- ^Milakov, M., and Gimelshein, N. (2018). "Online normalizer calculation for softmax." arXiv:1805.02867.
- ^Rabe, M. N., and Staats, C. (2021). "Self-attention Does Not Need O(n^2) Memory." arXiv:2112.05682.
- ^1 ^2Dao, T. (2024). "FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning." *International Conference on Learning Representations*. OpenReview.
- ^1 ^2Shah, J., Bikshandi, G., Zhang, Y., Thakkar, V., Ramani, P., and Dao, T. (2024). "FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-precision." *Advances in Neural Information Processing Systems 37*. NeurIPS proceedings.
- ^1 ^2 ^3 ^4 ^5Zadouri, T., Hoehnerbach, M., Shah, J., Liu, T., Thakkar, V., and Dao, T. (2026). "FlashAttention-4: Algorithm and Kernel Pipelining Co-Design for Asymmetric Hardware Scaling." arXiv:2603.05451.
- ^1 ^2 ^3 ^4 ^5 ^6 ^7 ^8Dao-AILab. (2026). "flash-attention." Official project repository and README, as of October 31, 2026. GitHub; BSD 3-Clause license.
- ^1 ^2Dao-AILab. (2026). "flash-attention releases." Official project release record through October 31, 2026, including v2.8.3.post2 and fa4-v4.0.0.beta37. GitHub releases.
- ^1 ^2PyTorch contributors. (2026). "`torch.nn.functional.scaled_dot_product_attention`." PyTorch documentation (stable, version 2.15 as of October 2026).
- ^PyTorch Foundation. (2024). "PyTorch 2.2: FlashAttention-v2 integration, AOTInductor." PyTorch blog.
- ^1 ^2Hugging Face. (2026). "Attention backends." Transformers documentation.
- ^Triton contributors. (2026). "Fused Attention." Triton documentation.
- ^Dao, T., Haziza, D., Massa, F., and Sizov, G. (2023). "Flash-Decoding for long-context inference." Stanford Center for Research on Foundation Models.
- ^xFormers contributors. (2023). "xFormers 0.0.22 release." GitHub release.
- ^Hong, K., Dai, G., Xu, J., Mao, Q., Li, X., Liu, J., Chen, K., Dong, Y., and Wang, Y. (2024). "FlashDecoding++: Faster Large Language Model Inference with Asynchronization, Flat GEMM Optimization, and Heuristics." *Proceedings of Machine Learning and Systems 6*. MLSys proceedings.
- ^He, H., Guessous, D., and PyTorch contributors. (2024). "FlexAttention: The Flexibility of PyTorch with the Performance of FlashAttention." PyTorch blog.
- ^Kwon, W., Li, Z., Zhuang, S., Sheng, Y., Zheng, L., Yu, C. H., Gonzalez, J. E., Zhang, H., and Stoica, I. (2023). "Efficient Memory Management for Large Language Model Serving with PagedAttention." *Proceedings of the 29th Symposium on Operating Systems Principles*. arXiv:2309.06180.
- ^Ye, Z., Chen, L., Lai, R., Lin, W., Zhang, Y., Wang, S., Chen, T., Kasikci, B., Grover, V., Krishnamurthy, A., and Ceze, L. (2025). "FlashInfer: Efficient and Customizable Attention Engine for LLM Inference Serving." *Proceedings of Machine Learning and Systems 7*. MLSys proceedings.
- ^Liu, H., Zaharia, M., and Abbeel, P. (2023). "Ring Attention with Blockwise Transformers for Near-Infinite Context." arXiv:2310.01889.
- ^NVIDIA. (2020). "NVIDIA A100 Tensor Core GPU Architecture." A100 whitepaper.
- ^NVIDIA. (2025). "NVIDIA Hopper Tuning Guide." CUDA documentation.
- ^NVIDIA. (2026). "NVIDIA Blackwell Tuning Guide." CUDA documentation.
- ^Stanford University. (2026). "Open Source Software Prize." Open Source Program Office.
- ^Zadouri, T., Hoehnerbach, M., Shah, J., Thakkar, V., and Dao, T. (2026). "FlashAttention-4: Algorithm and Kernel Pipelining Co-Design for Asymmetric Hardware Scaling." *Proceedings of Machine Learning and Systems 8 (MLSys 2026)*. MLSys proceedings.
- ^Shah, J., Bikshandi, G., Zhang, Y., Thakkar, V., Ramani, P., and Dao, T. (2024). "FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-precision." Preprint, version 2. arXiv:2407.08608.
- ^Python Package Index. (2026). "flash-attn-4." PyPI.
- ^Dao-AILab. (2026). "FlashAttention-4 (CuTeDSL)." README and package metadata.
- ^PyTorch contributors. (2026). "PyTorch 2.10.0 release notes." GitHub release.
- ^PyTorch contributors. (2026). "PyTorch 2.11.0 release notes." GitHub release.
- ^PyTorch contributors. (2026). "PyTorch 2.15.0 release notes." GitHub release.
- ^PyTorch contributors. (2026). "`torch.nn.attention.activate_flash_attention_impl`." PyTorch 2.15 documentation.
- ^PyTorch contributors. (2026). "`torch.nn.attention.SDPBackend`." PyTorch 2.15 documentation.
- ^PyTorch contributors. (2024). "PyTorch 2.5.0 release notes." GitHub release.
- ^PyTorch contributors. (2025). "PyTorch 2.7.0 release notes." GitHub release.
- ^Hugging Face. (2026). "Transformers v5.4.0 release notes." GitHub release.
- ^Frye, C., Wang, N., and Feng, T. (2025). "We reverse-engineered Flash Attention 4." Modal blog.
- ^Hu, R. (2026). "Hardware-Aware FP4 FlashAttention-4." arXiv:2609.04105.
- ^DeepSeek. (2025). "FlashMLA: Efficient Multi-head Latent Attention Kernels." GitHub.
- ^PyTorch contributors. (2026). "`torch.nn.attention.activate_flash_attention_impl`." PyTorch 2.10 documentation.
Improve this article
Add missing citations, update stale details, or write a clearer explanation. Anyone can edit: changes go live when you publish, and every edit is checked by an editor.
12 revisions · v14 · 6,831 words · full history
Fact-checks are independent of edits: a reviewer re-verifies the article against its sources and stamps the date. How we verify
Research and drafting on this wiki are AI-assisted, under named human editorial standards. How AI is used here
Reviewer note: Independently verified 2026-10-31 against the FlashAttention 1-4 papers (arXiv, NeurIPS, ICLR, MLSys 2026 versions), the Dao-AILab GitHub releases and README, PyPI, PyTorch release notes/docs, Transformers releases and ROCm docs; 4 minor verifier defects fixed before stamping.
Cite this page: AI Wiki. "Flash Attention." aiwiki.ai, updated 31 Oct 2026, fact-checked 31 Oct 2026. CC BY 4.0. https://aiwiki.ai/wiki/flash_attention